# ai-muninn — Full Site Content
# https://ai-muninn.com
# Generated: 2026-10-09
# Articles: 187
This file contains the full text of all articles on ai-muninn.com.
It is intended for AI tools that need complete site context.
For the article index only, see /llms.txt.
---
# One face, eight outfits: keeping a character consistent with Qwen-Image 2.1 on an RTX 5090
URL: https://ai-muninn.com/en/blog/qwen-image-21-same-face-8-outfits-rtx-5090
Date: 2026-10-09
import YouTubeEmbed from "@/components/YouTubeEmbed";
One reference photo plus a prompt that says "same woman, only change her clothing" gave me 8 outfits from Qwen-Image 2.1 on an RTX 5090. The face, the mole under her left eye, the wooden hairpin and the background held in all 8. Swapping locations instead, or both at once, works too. An 8-character Traditional Chinese sign came out right, and transparent PNG is built in. Two misses: a landmark hid one letter of a poster headline, and a menu drew 亞 in its simplified form once.
---
Before this, keeping one character consistent across images meant training a [character LoRA](/en/blog/train-character-lora-wan22-rtx5090) (a small add-on weight file that teaches the model one specific face). Without it, asking for the same person in different clothes usually gave me a different person.
Qwen-Image 2.1 is an open-weight image model from the Qwen team, released on September 20, 2026. The [weights](https://huggingface.co/Qwen/Qwen-Image-2.1) are free to download under Qwen's research license; commercial use needs a separate license from Qwen. It accepts reference images, meaning you hand it an existing picture and tell it what to keep. I wanted to know if that could replace the LoRA step. For outfit changes, it can.
## Eight outfits, one face: the mole and the hairpin survived every edit
I started from one reference image: a young woman in a pale-blue qipao in an old Taiwanese tea house. Then I asked for eight edits: a pink Song-dynasty Hanfu with embroidered plum blossoms, a Taiwanese high-school uniform, a charcoal business suit, a chef jacket with a tall hat, a NASA-style spacesuit with the helmet under her left arm, a camel winter coat with a red scarf, a pastel idol stage costume, and a black wuxia outfit with a sword on her back.
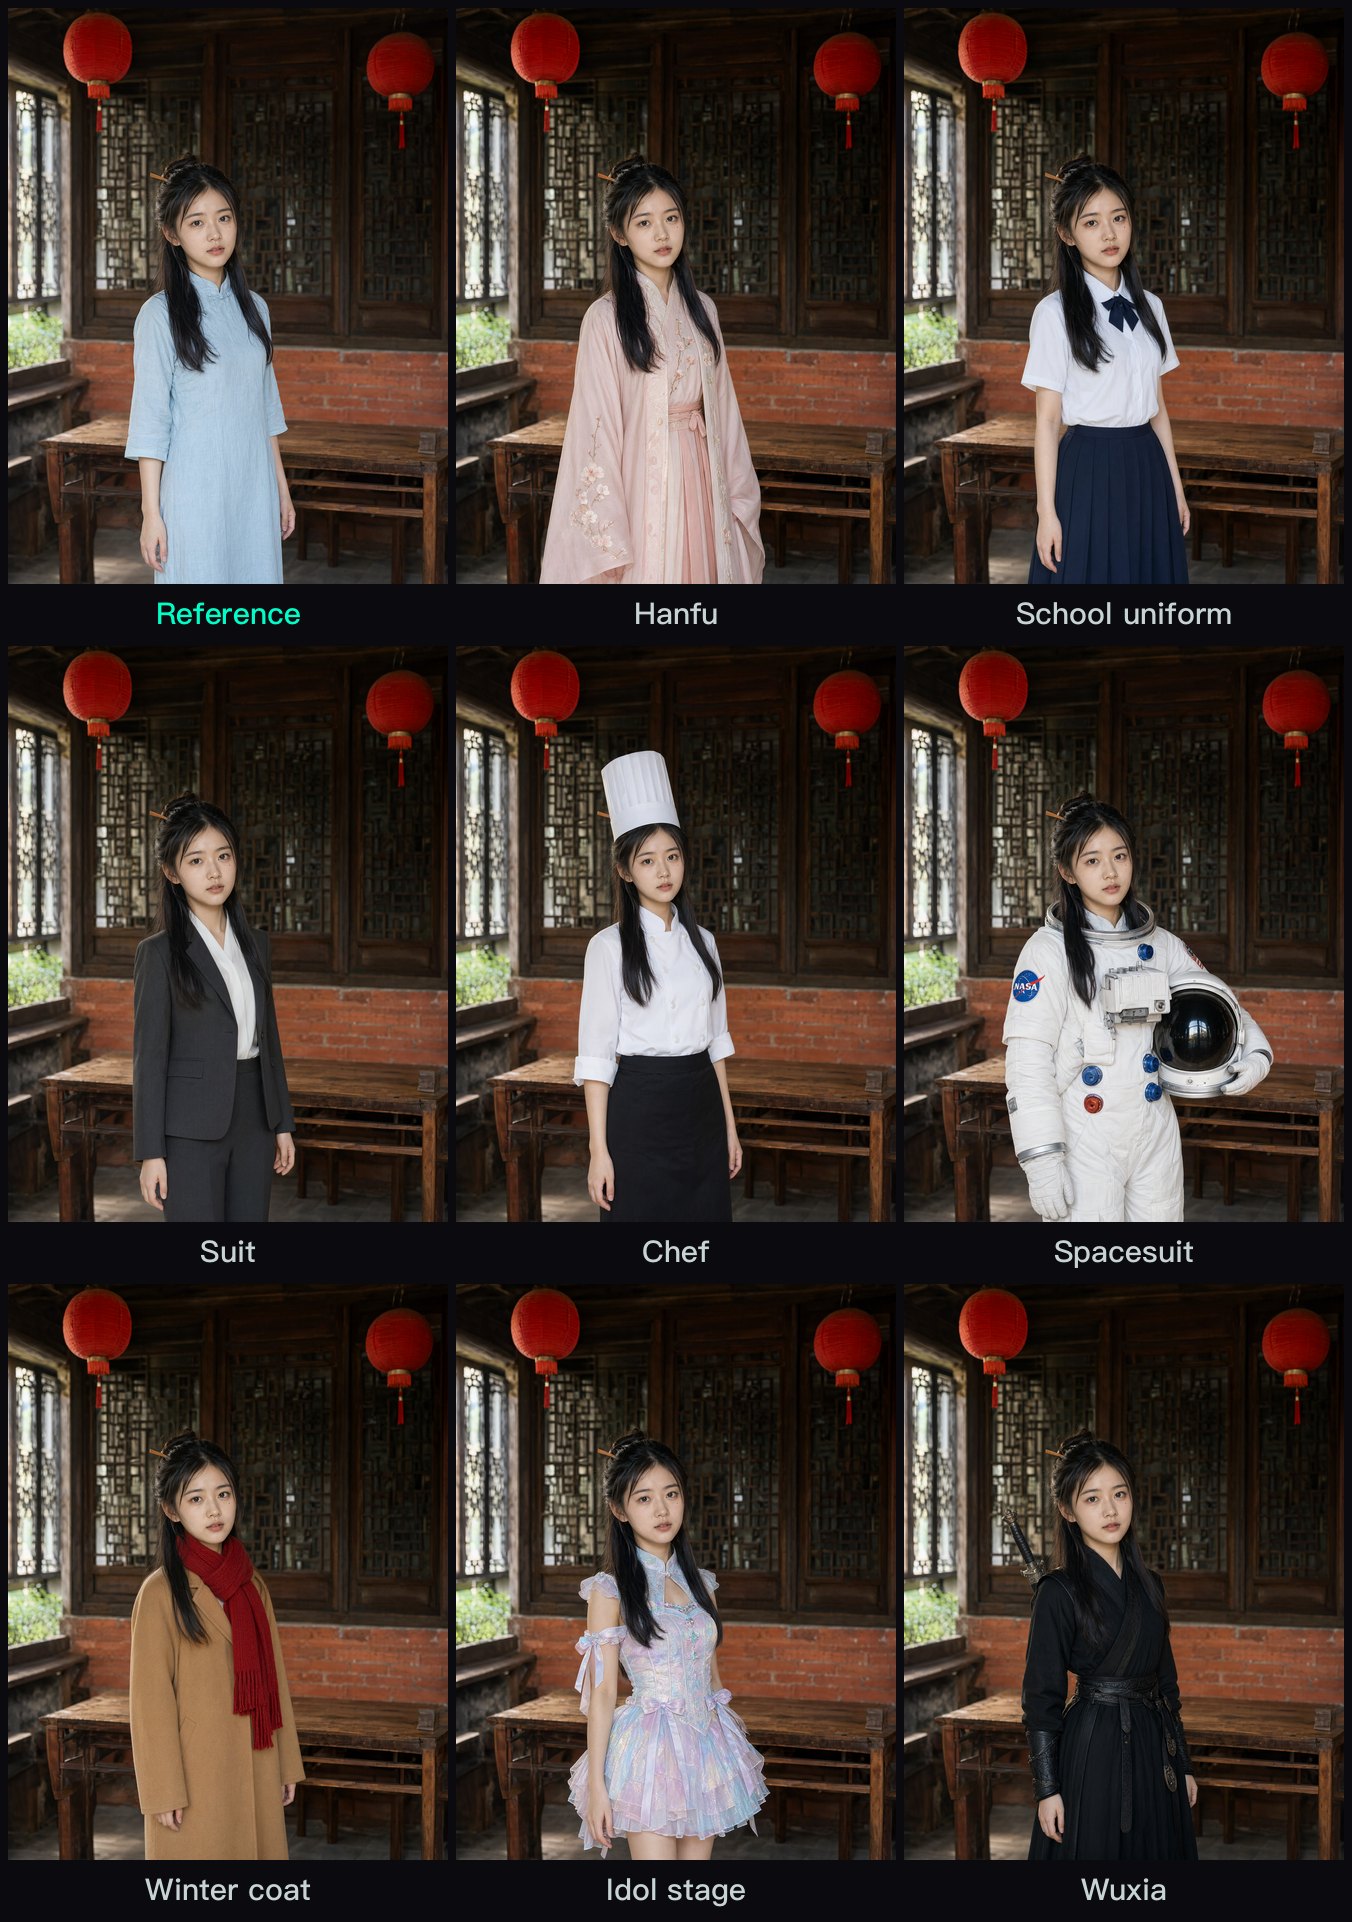
The background didn't move either. Red lanterns, lattice windows, brick wall and tea table sit in the same place in all eight, and so does she: same spot, same size in the frame. That part took a second attempt, covered in the how-to.
The face is the part that matters, so I cropped all nine.
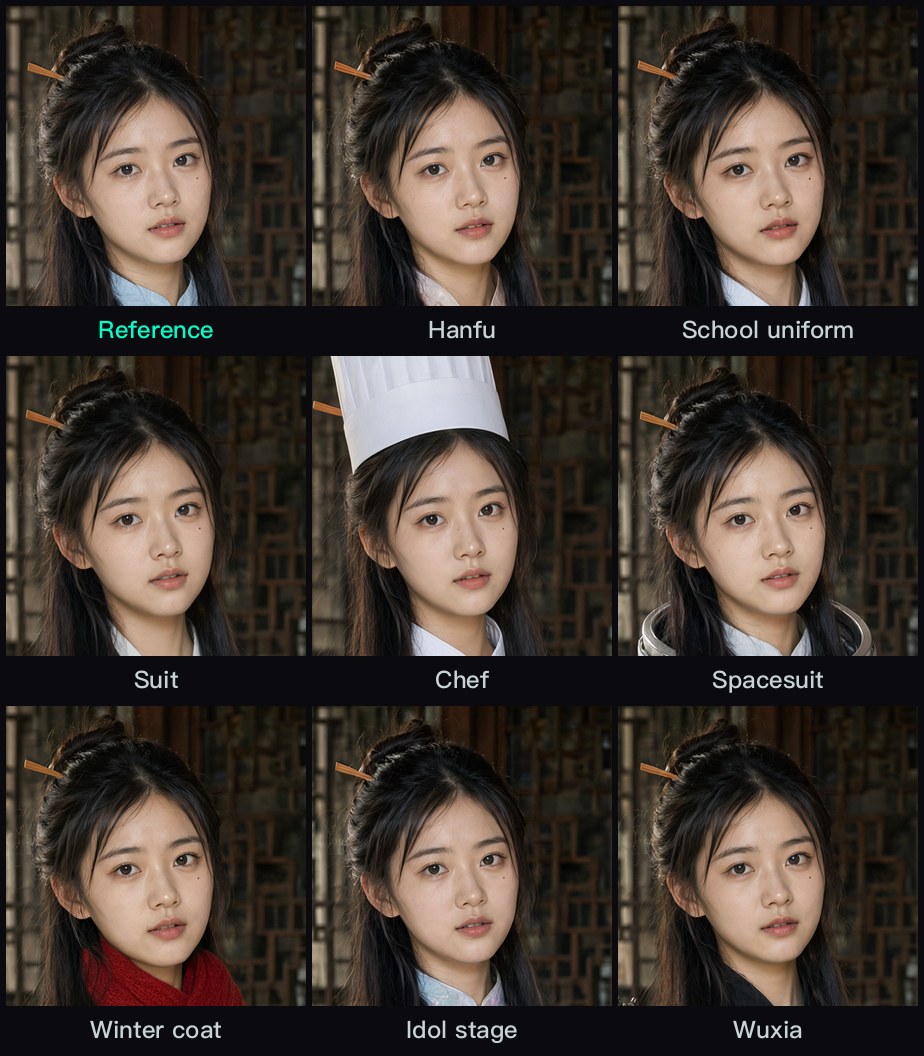
The mole under her left eye is there in all nine. In the chef image, the wooden hairpin still pokes out beside the hat. I didn't train anything for this.
## How to do it: one reference image, one template, a prompt that lists what stays
This section is for running it on your own machine, so expect file names and settings. If you only want to see what it can do, skip to the next section.
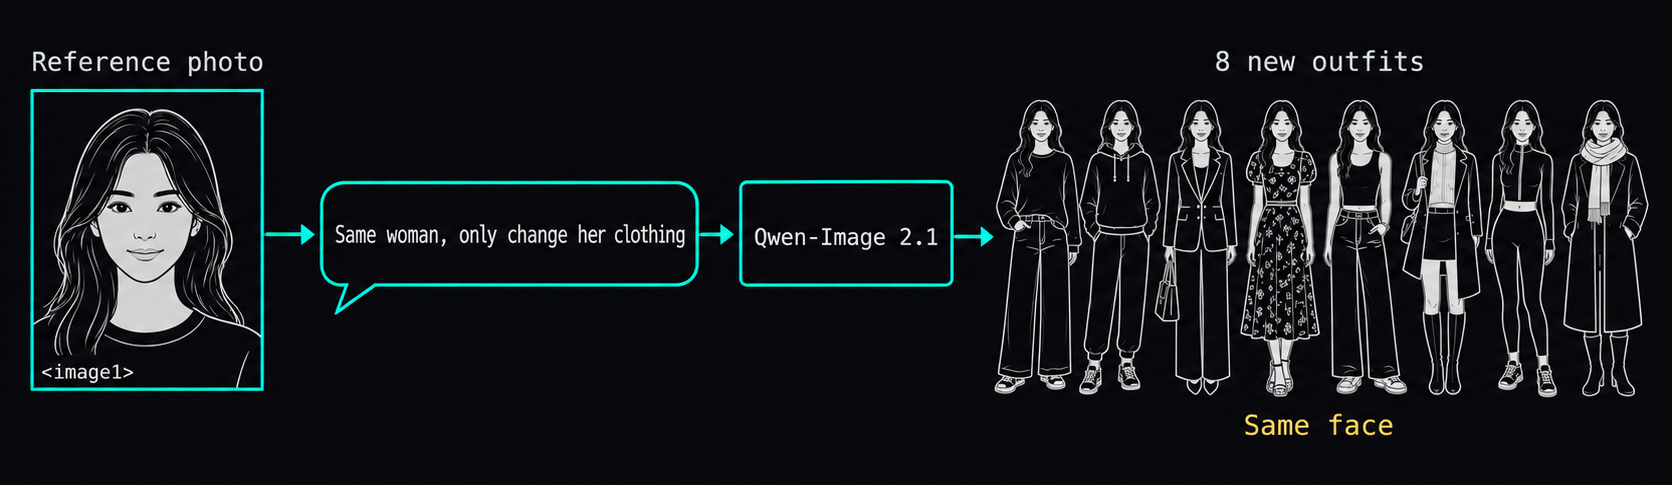
### Step 1: get ComfyUI and three files
[ComfyUI](https://github.com/Comfy-Org/ComfyUI) is a free, local, node-based image generation app: you wire boxes together into a pipeline, and the official Qwen-Image 2.1 templates come pre-wired. I used ComfyUI 0.37.0. Any version that ships the Qwen-Image 2.1 templates works. The files come from [Comfy-Org/Qwen-Image-2.1](https://huggingface.co/Comfy-Org/Qwen-Image-2.1). The diffusion model is the one to pay attention to:
| Folder | File | Size |
|---|---|---|
| `diffusion_models/` | `qwen_image_2.1_int8_convrot.safetensors` | 6.76 GiB |
| `text_encoders/` | `qwen3vl_8b_w4a8.safetensors` | 5.88 GiB |
| `vae/` | `qwen_image_2.1_vae_bf16.safetensors` | 0.63 GiB |
The int8 model is Comfy-Org's quantized version. In my own same-prompt comparison its quality was close to bf16, at half the file size, and it fits easily in the 5090's 32 GB. The text encoder reads your prompt and the reference image. I actually ran a community de-refusal ("heretic") variant of the w4a8 encoder, but every prompt here is ordinary and the official one is fine.
### Step 2: load a reference image into the edit template
I generated my reference with Qwen-Image 2.1 too: the same description with three seeds (the random number that decides which variation you get), and I picked one of the three. Your own photo works just as well.
Open the ComfyUI template "Qwen Image 2.1 Image Edit". The template preselects a different text encoder (`qwen3vl_8b_int8_convrot`), so switch its loader to the `qwen3vl_8b_w4a8` file you downloaded, and leave the template's optional prompt-rewriting branch off. Then wire the reference into the `image_1` input of the "Text Encode Qwen Image 2.1" node, and refer to it as `` in the prompt. The official templates wire up to 10 reference images. This post only uses one.
The template has a `custom_size` switch. Leave it off, which is the default. Off means the sampler starts from the `latent` output of `Text Encode Qwen Image 2.1`, which is sized to match the resized reference. On means it uses whatever width and height you type. My first batch did the equivalent of turning it on: I fed a 1536x2048 canvas while the node had resized the reference to 1344x1760, and her position and size drifted from image to image. Details in the deep dive. I set `resolution` to 1536, so the reference is resized to 1344x1760 and the outputs come out at that size too.
### Step 3: say what stays, lock the framing, then say the one change
This is the suit prompt, verbatim:
```text
The same woman from , with exactly the same face, the same small mole under her left eye, the same hairstyle with the wooden hairpin, the same standing pose, in exactly the same tea house background with the same red lanterns, windows, brick wall, tea table and lighting. Keep exactly the same framing, crop and camera distance as . Only change her clothing: she now wears a tailored charcoal-grey business suit jacket and trousers with a white blouse. Keep everything else unchanged. Photorealistic.
```
The "Keep exactly the same framing..." sentence came later. Without it, the suit and the winter coat pulled the camera back into a head-to-toe shot. Leave shoes out of the outfit description too: mention heels or boots and the model wants the feet in frame.
Everything before the clothing sentence is the same across all eight. You don't need to copy my wording.
### Step 4: check each result, reroll the odd one out
Most edits land on the first try. When her face sat in the wrong spot, I ran the same prompt with 3 more seeds and kept the one closest to the reference. That happened for 7 of the 23 edits in this post.
Sampling: 40 steps, euler, simple, cfg 1.0. The official template defaults to 25 steps; the official pipeline guidance is about 40 to 50.
## The reverse works too: same qipao, eight places, and the lighting follows
Then I flipped it. I kept the outfit and pose fixed, kept the framing line, and changed only the background and lighting, with "Only change the background and lighting: she now stands in ..." in the prompt. Eight places: a Taiwanese night market, a tropical beach, a snowy mountain village, a rainy neon Tokyo street, an old library, a space station with Earth in the window, a cherry-blossom path, and a desert at sunset.
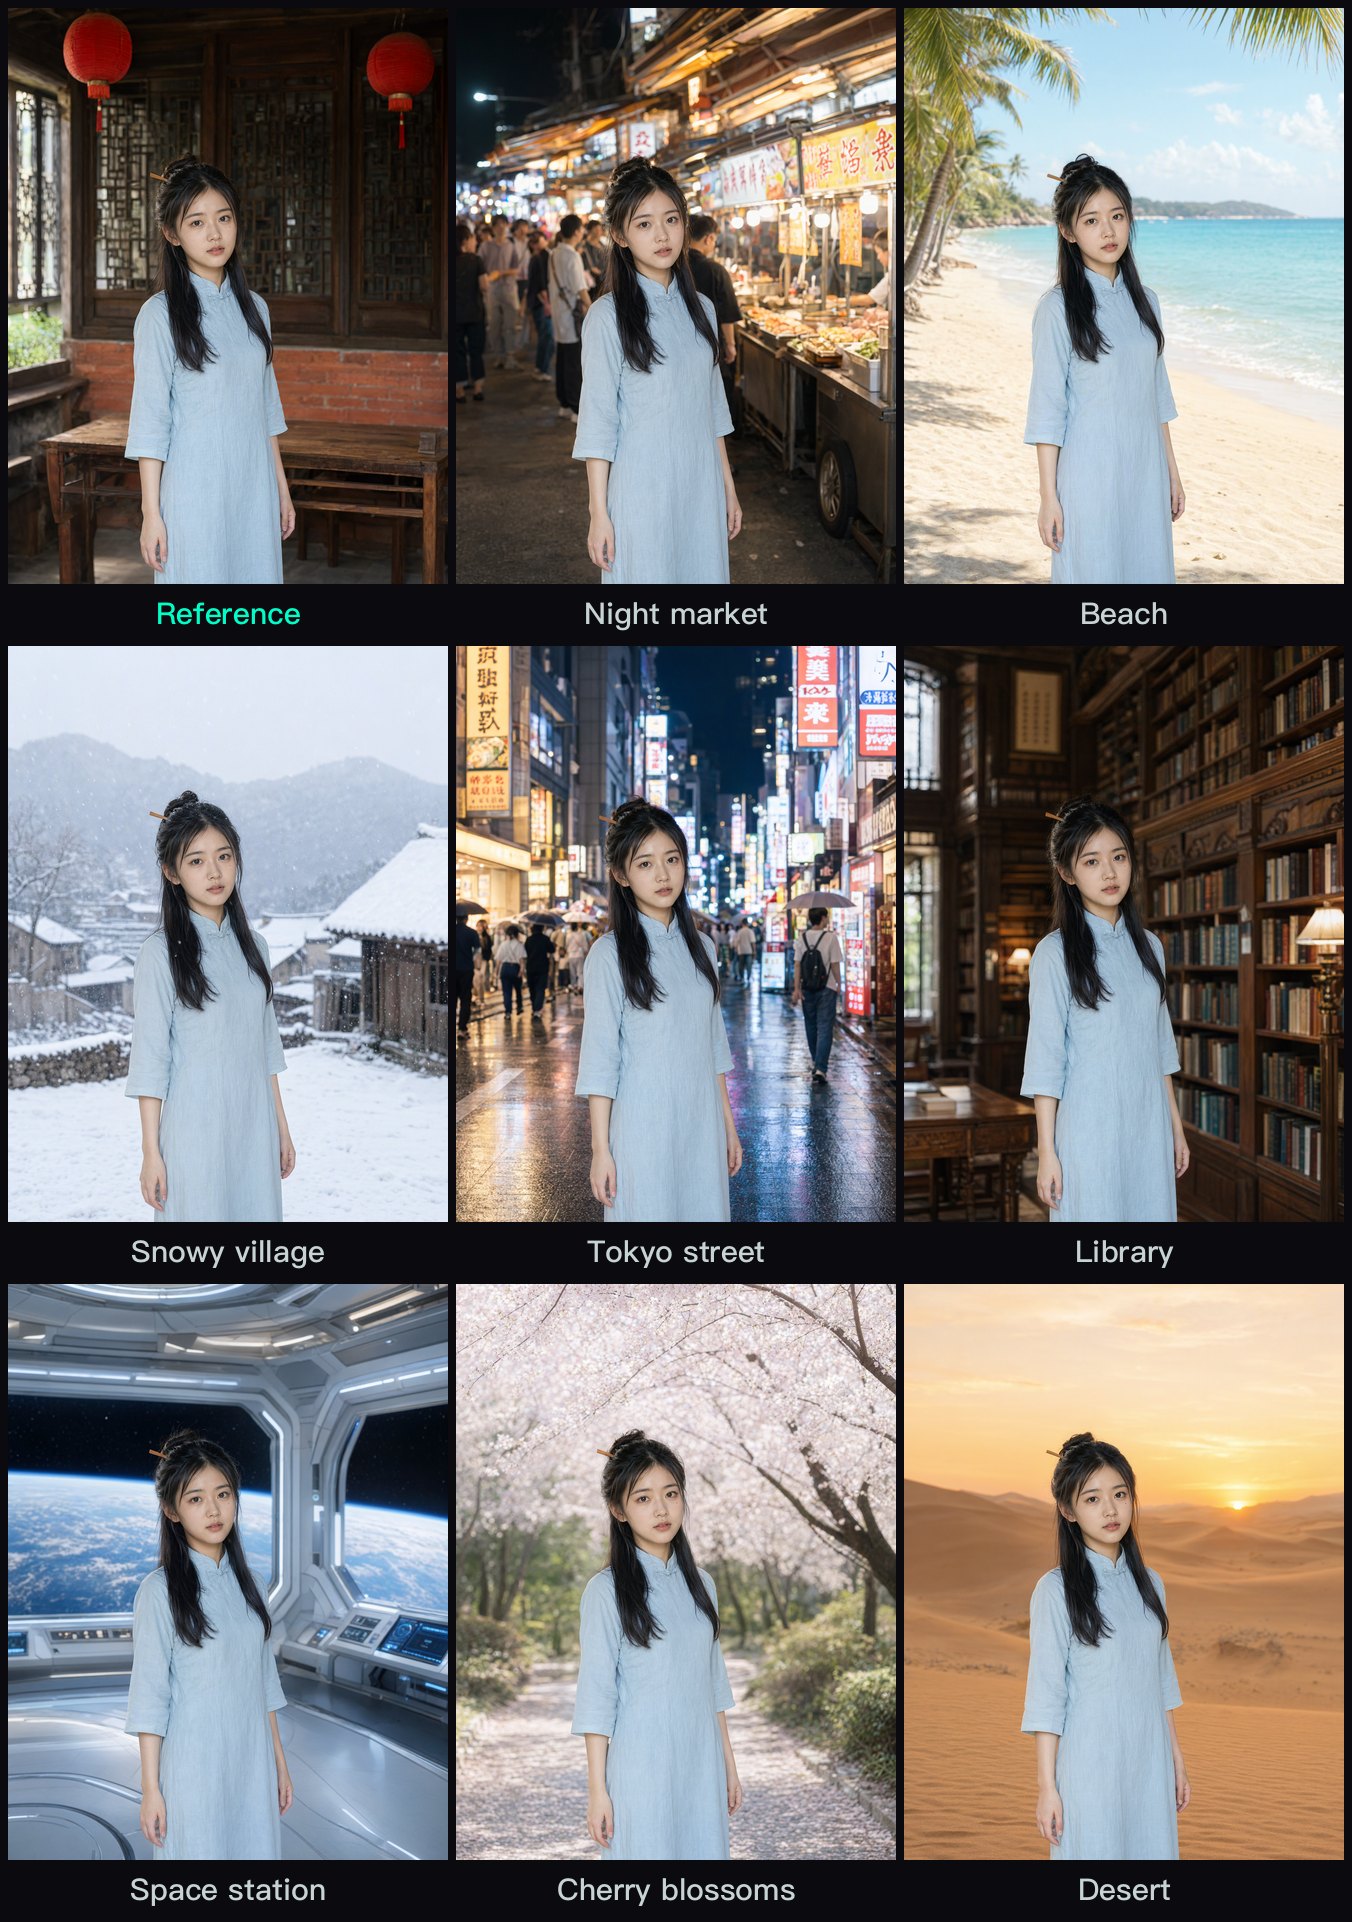
The lighting follows the scene instead of being pasted on. Neon reflects off the wet Tokyo pavement. In the desert, her face picks up a warm sunset tint. Same person in every frame, hairpin included.
## Outfit and location together: do it in two passes
For "Hanfu under cherry blossoms" I didn't ask for both changes in one prompt. I changed the outfit first, then used that result as the reference for a background swap. The second prompt is shorter because the outfit is already in the reference:
```text
The same woman from , with exactly the same face, hairstyle, clothing and standing pose. Keep exactly the same framing, crop and camera distance as . Only change the background and lighting: she now stands in a park path under full-bloom cherry blossom trees. Photorealistic, natural light matching the new scene.
```
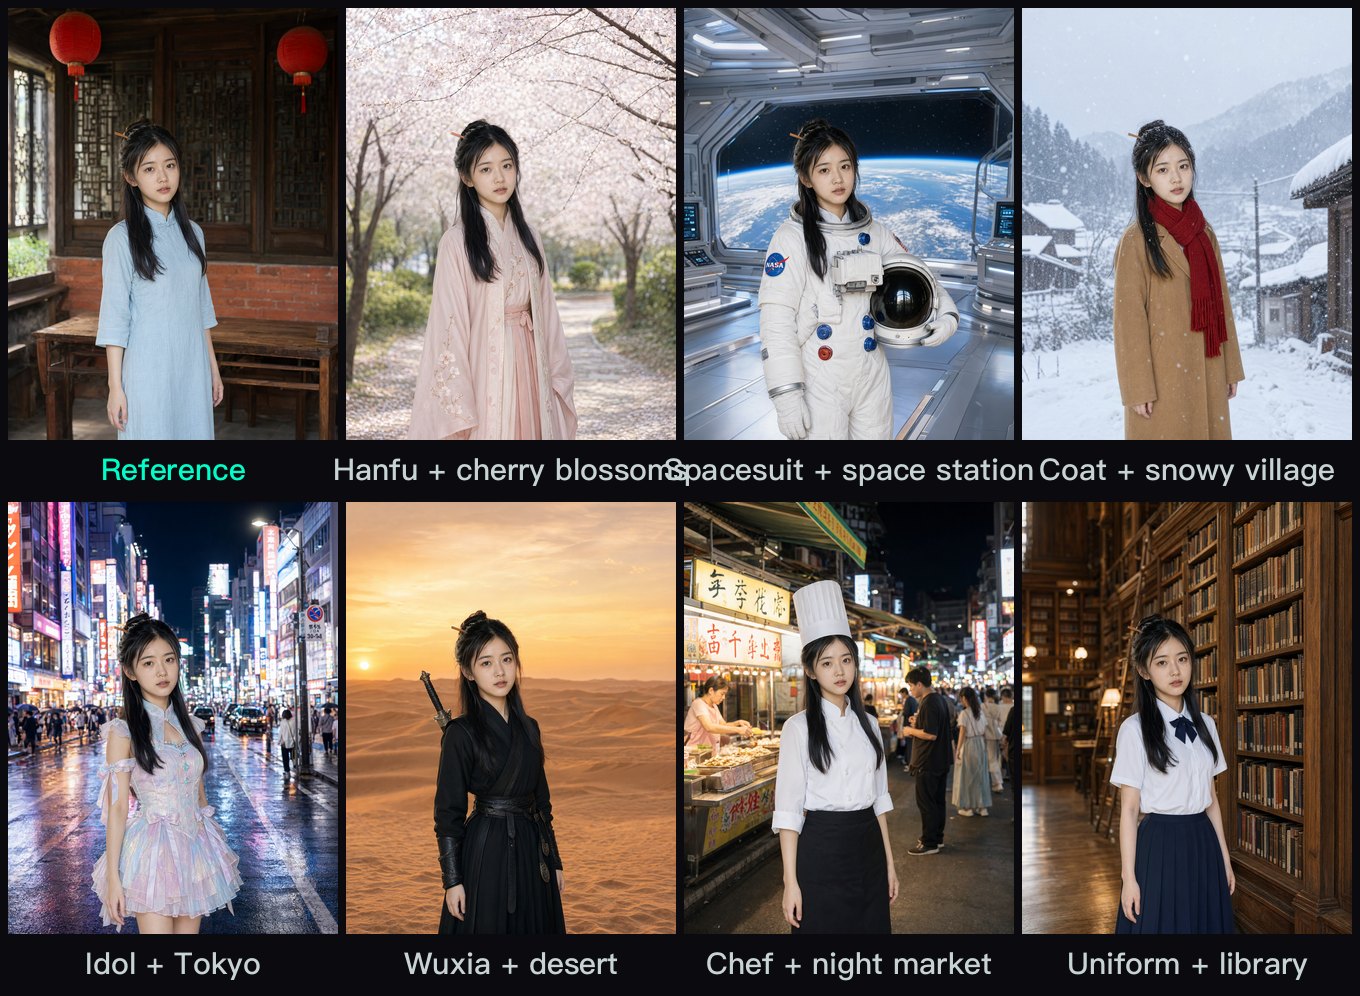
Seven combos, one face, one position. Together with the 16 single-change images, that's enough for a stop-motion style quick-cut short.
## Text in images: a Chinese sign came out right, with two misses elsewhere
I prompted for a sign reading 巷口阿伯的燒餅油條 ("Uncle's sesame flatbread and fried dough sticks at the alley entrance"). All eight Traditional Chinese characters came out correct, including dense ones like 燒, 餅 and 條.
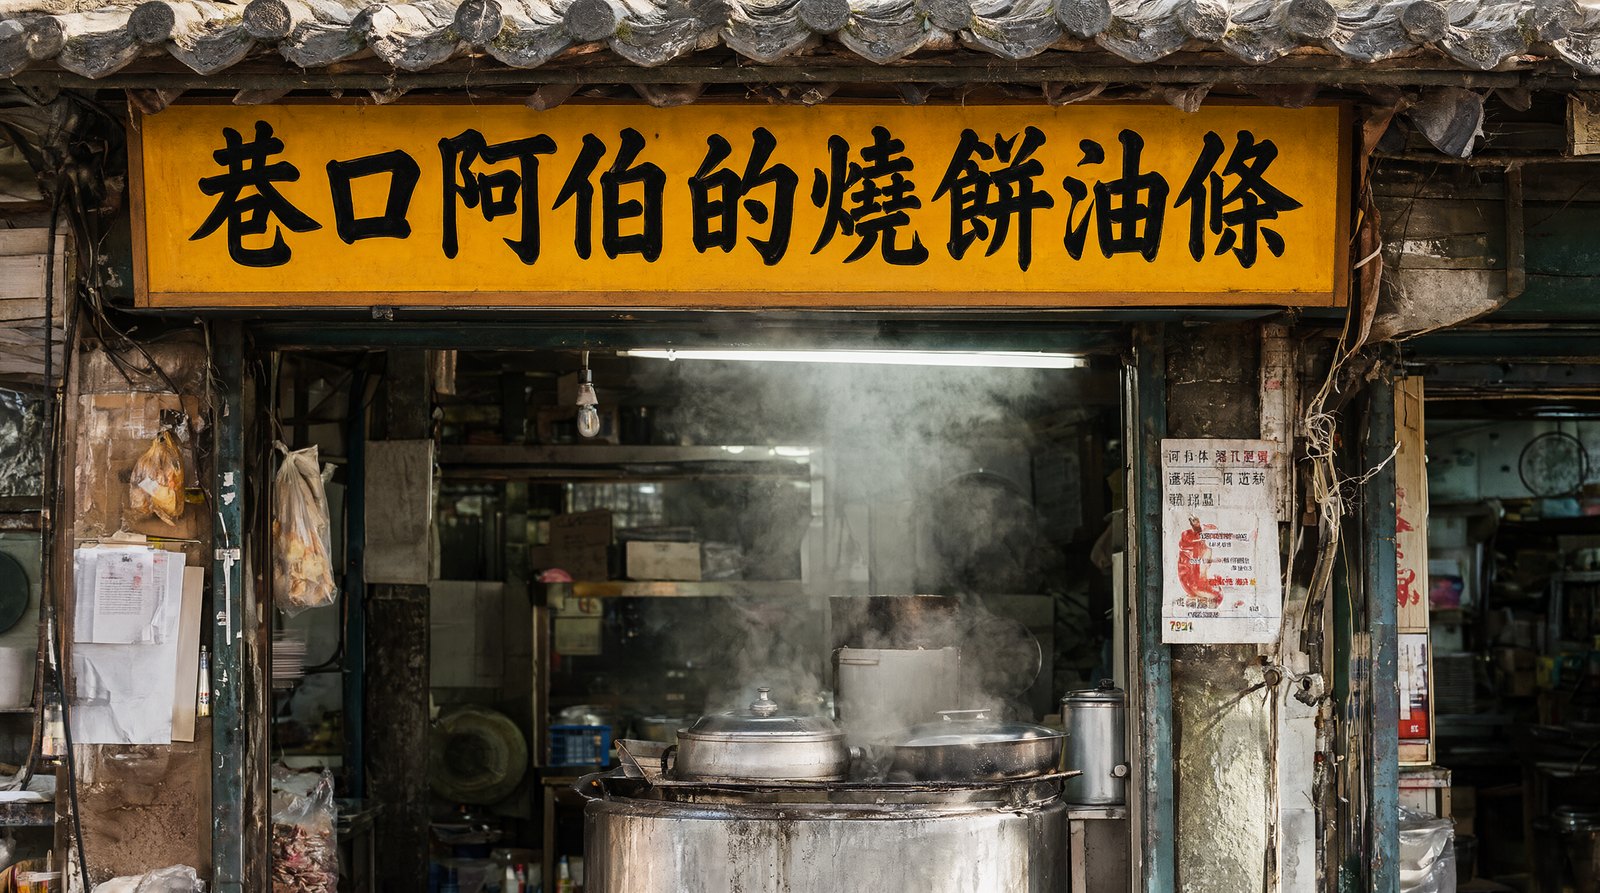
Two other tests each had one miss.
An English travel poster: headline "VISIT TAIPEI AT NIGHT", bottom line "Night markets · Hot springs · Bubble tea". Spelling was correct. But Taipei 101 runs through the headline and hides the N in NIGHT; only its right stroke shows.
A chalkboard coffee menu in Chinese and English, with prices: Ethiopia 180, Kenya 200, Alishan 220, Latte 150. All the English and all four prices were right. The miss: in 衣索比亞 (Ethiopia), 亞 is drawn in its simplified form 亚, while the next line, 肯亞 (Kenya), uses the traditional 亞.
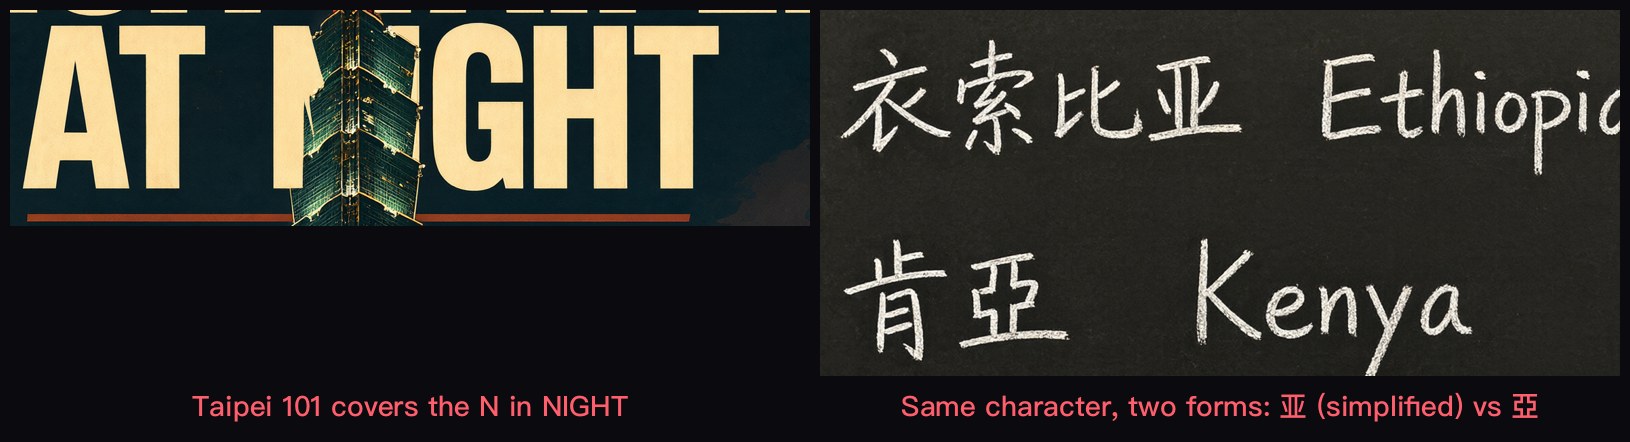
The model makes up any text you don't specify. The stall signs in the night-market images are Chinese-looking strokes that aren't real characters. Put every word you need in the prompt. For dense small text, add it in a layout app afterward.
## Transparent PNG straight out of the model, no background removal
Qwen-Image 2.1 can output an alpha channel (the per-pixel transparency layer in a PNG). Wrap your description in two fixed sentences:
```text
This is an RGBA image with transparency. The image has alpha channel and the background is transparent.
```
My test was a cat barista sticker holding bubble tea. The output is an RGBA PNG. On a checkerboard and on a dark teal background, the edge is clean with no white fringe.
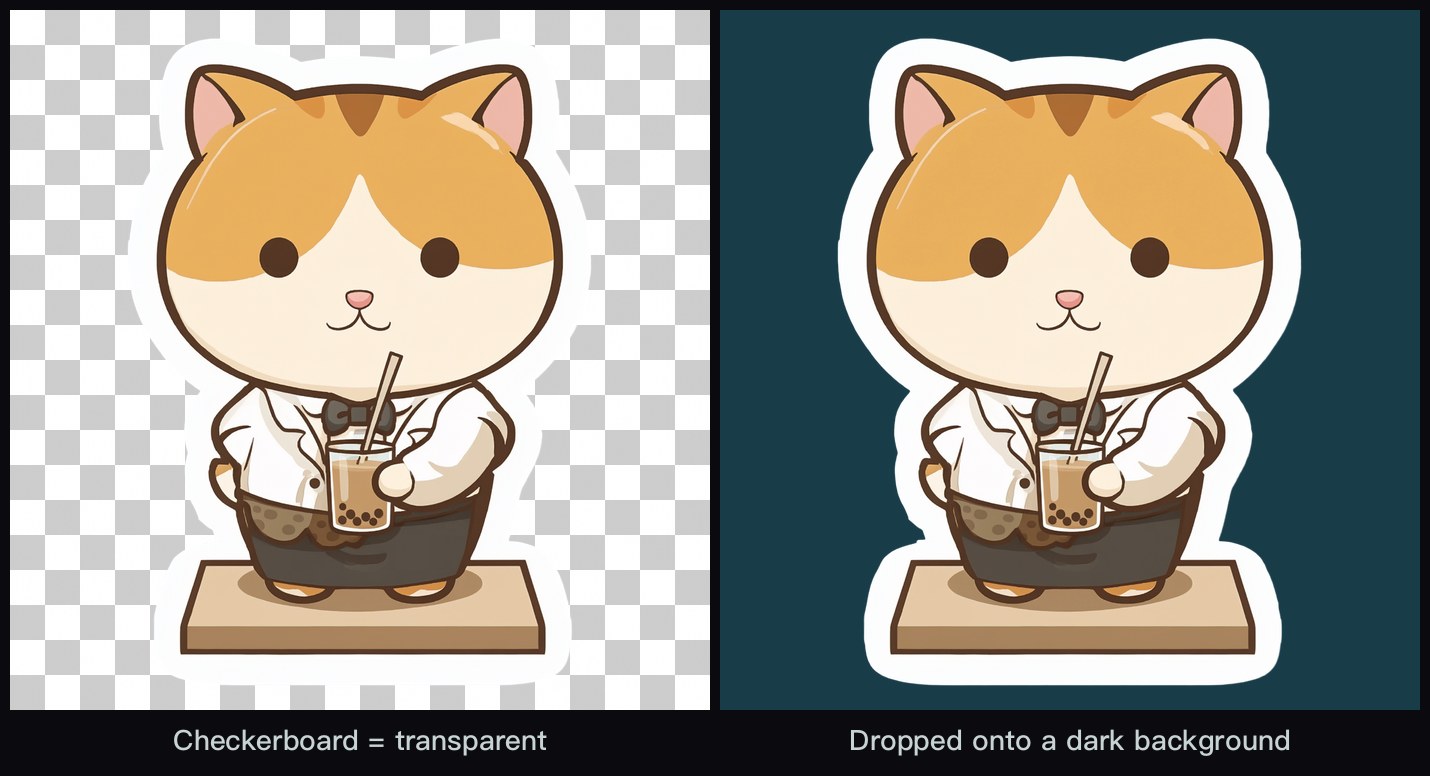
## Speed: about 5.5 s per edit on the 5090, about 11 s on a modded 2080 Ti
Speed isn't why I'd pick this model, so this is short. Each number is from warm runs, three per test. The two machines use **different settings**, so the rows aren't a head-to-head comparison. The 5090 column is the machine that made the images in this post.
| Task | RTX 5090 (int8, 40 steps) | Modded RTX 2080 Ti 22GB (turbo int8, 6 steps) |
|---|---|---|
| 1024x1024 generate | ~6.4 s (~1.2 s with a 4-step LoRA) | ~7.5 s |
| Edit with reference | ~5.5 s (768x1024) | ~10.8 s |
| 1536x2048 generate | ~22.5 s | not run |
The [modded 2080 Ti](/en/blog/modded-2080ti-22gb-local-agent) is my everyday setup at home. Turing has no bf16, so ComfyUI needs to be switched to fp16 to be fast. Details below.
## Deep dive: settings, prompts, two ComfyUI 0.37 gotchas, and raw timings
You can skip this section; nothing above depends on it. It's here for anyone who wants to reproduce the results, or hand the whole post to an LLM.
### Machine and settings
- RTX 5090 32 GB, ComfyUI 0.37.0, torch 2.13.0+cu130, comfy-kitchen 0.2.35.
- Model files as in the table above. The text encoder is the heretic (de-refusal) variant of `qwen3vl_8b_w4a8`. The official one refuses some prompts, so I use this one daily. Nothing in this post would be refused.
- Sampling: 40 steps, euler, simple, cfg 1.0. No speed LoRA on any article image.
- Resolutions: reference 1536x2048; every outfit, location and combo edit at `resolution` 1536, output 1344x1760; sign 2752x1536; poster 1536x2048; menu and sticker 2048x2048.
- Sampler start: the `latent` output of `Text Encode Qwen Image 2.1`, not an `EmptyLatentImage`.
- Seeds: reference from 202001 to 202003, picked 202002.
- Outfits: Hanfu, uniform, chef, spacesuit, idol and wuxia one run each (303000, 303001, 303003, 303004, 303006, 303007). Suit and coat, after the prompt fix, 3 seeds each; picked 707000 and 707003.
- Locations: 808000 to 808007 one run each; the library drifted, so 3 more seeds, picked 909132.
- Combos: coat + snow 809002, idol + Tokyo 809003, uniform + library 809006 on the first try; Hanfu + cherry blossoms, spacesuit + space station, wuxia + desert, chef + night market 3 seeds each, picked 909022, 909033, 909077, 909099.
- All images regenerated on 2026-10-09.
### The base prompt (text-to-image, no reference)
```text
Full-body photograph of a young Chinese woman in her twenties standing in the exact center of the frame, facing the camera, long black hair in a half-up bun with a simple wooden hairpin, oval face, small mole under her left eye. She stands in an old Taiwanese tea house: dark wooden lattice windows, two hanging red paper lanterns, a red brick wall and a low wooden tea table behind her. She wears a pale-blue cotton qipao. Soft afternoon window light from the left, photorealistic, 50mm lens, natural skin texture.
```
### The location prompt (night market)
```text
The same woman from , with exactly the same face, the same small mole under her left eye, the same hairstyle with the wooden hairpin, the same pale-blue qipao and the same standing pose. Keep exactly the same framing, crop and camera distance as . Only change the background and lighting: she now stands in a busy Taiwanese night market at night with glowing food stalls. Photorealistic, natural light matching the new scene.
```
### Why the first batch drifted: the canvas didn't match the reference
For the first batch I wired a 1536x2048 `EmptyLatentImage` into the sampler. At `resolution` 1536, `Text Encode Qwen Image 2.1` resizes the reference to 1344x1760, so the two sizes disagreed. The node's own tooltip in the ComfyUI source says exactly this about its `latent` output: "Empty latent on the first reference image's size, to match with sampling as any other size shifts the edit." That latent is empty (all zeros). It carries no pixels from the reference; its job is to make the canvas the same size. The template's `custom_size` switch, when on, takes the same path my first batch did.
I measured the eye midpoint and eye distance in both batches with the YuNet face detector, after resizing every image to 1344x1760:
| Batch | Images | Eye midpoint x | Eye midpoint y | Eye distance |
|---|---|---|---|---|
| First (my own 1536x2048 canvas) | 17 | 548–634 | 501–696 | 54.5–83.1 (±18.9%) |
| Final (node's latent output) | 24 | 611–627 | 645–661 | 73.5–79.6 (±3.9%) |
Both include the reference itself (midpoint 618, 650; eye distance 79.2). The worst first-batch outliers were the suit and the coat (eye distance 58.4 and 54.5, pulled back) and the cherry-blossom shot (x drifted to 548).
### The suit and coat still went wide on the right canvas
With the canvas fixed, the suit and coat edits still came out as full-body shots. Rerolling didn't help: 3 seeds each on the same prompt, all six landed at eye distance 51.3–59.3, against 79.2 for the reference.
For the second round I changed two things at once: I added `Keep exactly the same framing, crop and camera distance as .` and dropped the heels and boots from the outfit descriptions. Again 3 seeds each; all six came out at 77.7–79.5. I didn't test the two changes separately, so the how-to keeps both.
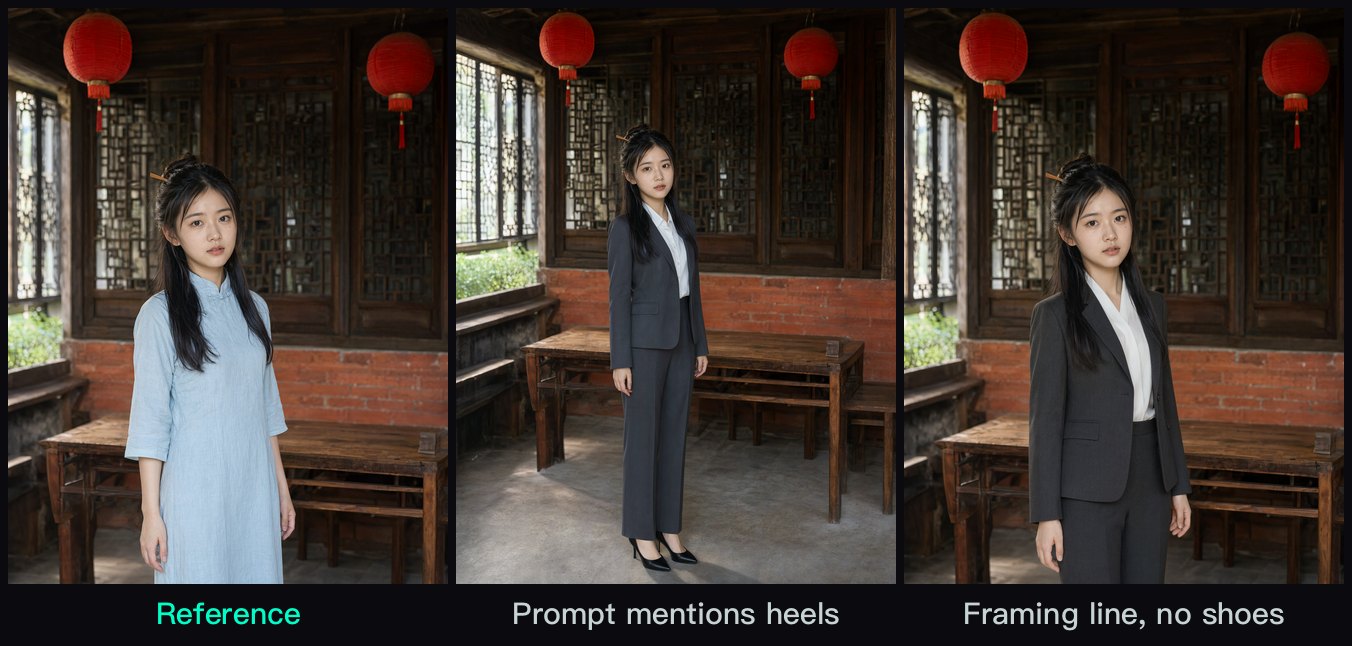
### Small pose drift in the outfit set
Face and background are stable across the outfit set. Hands and stance adjust slightly to the clothes. The prompt says "the same standing pose", but the spacesuit requires holding a helmet under the left arm.
### ComfyUI 0.37.0 gotcha 1: two required inputs on the text encode node
In 0.37.0, `TextEncodeQwenImage21` requires two inputs, `negative_prompt` and `resolution`. A hand-built workflow that leaves either out fails through the API with HTTP 400 and this error type:
```
required_input_missing
```
Add both inputs to the node and the request goes through.
### Gotcha 2: an identical workflow hits the cache in 0.0 s
Submit the exact same workflow twice and ComfyUI returns its cached result: 0.0 s and the same filename. Change the seed when you benchmark, or when you actually want a new image.
### Regular outputs carry an alpha channel too
Even without the transparency sentences, outputs are RGBA PNGs. The alpha isn't all 255; the lowest value I saw was 251, far too small a change to see. Convert to RGB before compositing or putting the image on the web.
### Raw speed table
Method: warm, three runs each, seed changed every run, timed from submit to image. The first run is slower because it loads the model and the reference image; the tables in the main text use the later runs.
| Machine | Task | Runs (s) |
|---|---|---|
| RTX 5090 | 1024x1024, 4-step LoRA | 2.26 / 1.22 / 1.20 |
| RTX 5090 | 1024x1024, 40 steps | 6.88 / 6.37 / 6.40 |
| RTX 5090 | 768x1024 edit, 40 steps | 7.4 / 5.5 / 5.5 |
| RTX 5090 | 1536x2048 generate / edit, 40 steps | ~22.5 / ~32.7 |
| RTX 2080 Ti 22GB | 1024x1024 generate, Viggle 6-step int8 | 8.9 / 7.5 / 7.6 |
| RTX 2080 Ti 22GB | 1024 edit, Viggle 6-step int8 | 16.6 / 10.8 / 10.8 |
### Why no article image uses the 4-step LoRA
The 4-step LoRA is the `4step-lora-r64` file from [Viggle/Qwen-Image-2.1-viggle-turbo](https://huggingface.co/Viggle/Qwen-Image-2.1-viggle-turbo). The LoRA's README says complicated edits, including identity-preserving ones and instructions with several constraints, can still fall short of the base model, with identity drift.
### Getting the 2080 Ti fast: fp16, then the 6-step turbo
The 2080 Ti runs the same repo's `v0.3-6step-int8_convrot` merged checkpoint at 6 steps, cfg 1.0. Turing has no bf16, so ComfyUI falls back to fp32, which is slow. I added fp16 to ComfyUI's `QwenImage21.supported_inference_dtypes` and moved to torch 2.9.1+cu130. The same int8 40-step job went from 159 s to 42 s. Then I switched to the 6-step turbo checkpoint, which gives the 7.5 s per 1024x1024 image above.
---
# Kandinsky 6.0 Pro on an RTX 5090: lip-synced English dialogue works, Chinese isn't quite there yet
URL: https://ai-muninn.com/en/blog/kandinsky-6-pro-lip-sync-rtx-5090
Date: 2026-10-08
import YouTubeEmbed from "@/components/YouTubeEmbed";
Kandinsky 6.0 Pro (29B, MIT) makes a 5-second clip with 44 kHz audio and lip-synced speech in one pass. On an RTX 5090, English dialogue came out word-for-word correct and the mouth timing looked natural. Chinese was understandable, with an accent and a few wrong words. Clip time: 277 s in bf16, 206.7 s with SageAttention, 141.5 s median with an NVFP4 copy I made along the way (60.3 GB down to 20.1 GB, on Hugging Face). Lite (3B) handled English but garbled Chinese.
---
## Why I tried it: a video model that moves the mouth to match the words
Kandinsky 6.0 was open-sourced on 2026-10-06. I saw the release news and ran a quick test on my RTX 5090. The part I cared about was lip-sync: you write a line of dialogue, and the model generates the video and the voice together, with the mouth moving in time.
The short answer: English is great, Chinese isn't quite there, but it isn't bad either.
Along the way I quantized the Pro model to NVFP4 so it runs faster on a 32 GB card. I uploaded it so the next person doesn't have to redo it.
## Kandinsky 6.0 makes video and audio in one pass, and the dialogue goes in the prompt
[Kandinsky 6.0](https://github.com/kandinskylab/kandinsky-6) comes in two sizes: Lite (3B) and Pro (29B), both MIT-licensed. Each pass produces a 5-second clip plus 44 kHz audio, lip-sync included. It does text to video+audio and image+text to video+audio. A separate super-resolution model can upscale to 1920×1080.
The design has two streams: one for video and a newly trained one for audio, and they attend to each other (bidirectional cross-attention, meaning each stream looks at the other at every layer). That's why the mouth timing lines up with the sound. Text goes in through Qwen2.5-VL 7B plus CLIP-L. Video uses the HunyuanVideo VAE (the part that compresses frames into a small latent space and back). Audio uses the MMAudio VAE and a BigVGAN vocoder.
The [paper (arXiv 2610.05608)](https://arxiv.org/abs/2610.05608) has a human evaluation against Kling 2.6, Veo 3.1 Fast, MiniMax H3, Seedance 2.0, LTX 2.5 and Kandinsky 5.0 Pro, and claims speech quality is especially competitive. I didn't check the win rates in the PDF, so I'm not quoting numbers.
A prompt has two parts. The video caption describes the scene, and the spoken line goes inside it, wrapped in `` and ``. A separate audio caption describes the voice and the ambience. This is the one I used:
```text
Medium close-up of a beautiful young Chinese woman in traditional Hanfu, pale blue silk with embroidered sleeves, hair in an elegant bun with a jade hairpin, standing in a quiet classical garden courtyard with a wooden pavilion behind her. The camera is static. She looks straight into the camera, smiles gently and says: Welcome to AI Muninn. Here's today's AI news. Soft afternoon light, photorealistic, shallow depth of field.
```
```text
A clear, warm young female voice speaking English at a calm pace, quiet garden ambience with soft birdsong.
```
For the Chinese run I changed only two things: the line inside `…` became 「歡迎來到 AI Muninn,今天帶你看最新的 AI 消息。」 ("Welcome to AI Muninn, today I'll show you the latest AI news"), and "English" in the audio caption became "Mandarin Chinese".
The official ComfyUI workflow expands short prompts with Qwen3.5 by default (a "beautifier" step). I wrote full English captions myself and turned it off.
## English came out word-for-word; Chinese is understandable, with an accent
I ran each clip through Whisper large-v3-turbo to check the spoken words. Whisper only tells you what was said, not whether the mouth matches. The lip-sync judgment is mine, from watching the clips: in the English ones, the timing looks natural.
**English.** Both bf16 and NVFP4 were word-for-word correct. The only miss was the made-up word "Muninn", heard as "Munnin" or "Manin". Unmute the clip; it starts muted.
**Chinese.** The paper says the training captions were written in Russian and English, and RL prompts were picked in either language with equal probability. Chinese isn't mentioned anywhere. Even so, it's understandable. It sounds like a foreign speaker, with a few wrong words. Here is what Whisper heard:
| Run | Whisper transcript | What it says |
|---|---|---|
| Written line | 歡迎來到 AI Muninn,今天帶你看最新的 AI 消息 | Welcome to AI Muninn, today I'll show you the latest AI news |
| Pro bf16 | 欢迎来到AI慕您,请演带您看最起的AI消息 | "Welcome to AI" right; the middle is off; "latest" became a different word |
| Pro NVFP4 | 欢迎来到AI母您,今天带你看最起的AI消息 | "Welcome to AI" right; "today I'll show you" right; "latest" still wrong |
"Welcome to AI" is correct in both. The word for "latest" (最新) came out as 最起 in both. NVFP4 got "today I'll show you" right, but that's one run each, so I can't claim quantization improved the Chinese. The simplified characters are Whisper's default output, not something the model chose.
## What you need to run it on an RTX 5090
My machine: RTX 5090 (32 GB), 61.6 GB of system RAM, Windows.
1. **ComfyUI 0.38.0 or newer.** The official nodes require it. My main ComfyUI is 0.37 with a full MiniMax-H3 node set I didn't want to break, so I made a separate 0.38.2 git worktree with its own venv on port 8189. The old one keeps 8188. Commands are in the deep dive.
2. **The official `kandinsky6` nodes.** Search for them in ComfyUI Manager, or copy the repo's `comfyui/` folder into `custom_nodes/kandinsky6/`.
3. **The models.** The workflow has a "Download models" button, or follow the manual table in the node README. You need the Pro distilled transformer (60.3 GB), Qwen2.5-VL 7B plus CLIP-L, the HunyuanVideo VAE, the MMAudio audio VAE (`v1-44.pth`) and the BigVGAN vocoder.
4. **SageAttention.** A faster attention kernel; ComfyUI picks it up automatically once installed. Skip it and the same clip takes 277 s instead of 206.7 s.
Sampling settings: Pro distilled uses 10 steps, CFG 1.0, audio VAE scaling 0.417. "Distilled" means a version trained to get there in far fewer steps. The non-distilled model needs 50 steps at CFG 5.0 and is much slower.
I ran my own API version of the workflow, with the same nodes and settings: 864×480, 121 frames (24 fps, about 5 s), seed 42.
## bf16 takes 206.7 s per clip, NVFP4 takes 141.5 s
Every number here is wall-clock, from submit to saved file, with model loading included. All at 864×480, 121 frames. I only compare the model against itself: same Pro distilled checkpoint, bf16 versus my NVFP4 copy. With the same English line, seed 42 and SageAttention on, bf16 took 206.7 s and NVFP4 took 141.5 s. The 277 s row is bf16 before I installed SageAttention, kept for reference.
| Setup | Time per clip |
|---|---|
| Pro distilled bf16, no SageAttention | 277.2 / 277.0 s |
| Pro distilled bf16 + SageAttention | 206.7 s |
| Pro distilled NVFP4 + SageAttention | 131.4 / 141.5 / 151.5 s |
The three NVFP4 runs used different lines and seeds: English seed 42 (141.5 s), Chinese seed 42 (131.4 s) and English seed 7 (151.5 s).
Why bf16 is slow: the 60.3 GB model doesn't fit in 32 GB. ComfyUI 0.38 stages weights in and out as it runs (the log shows `57486MB Staged`). Moving those weights is where the extra time goes.
## My NVFP4 build looks nearly identical to bf16
NVFP4 is a 4-bit number format that newer NVIDIA GPUs compute natively. bf16 had to stream 60 GB through the card on every run, so I converted the model first and kept testing on that. The conversion took 59 s.
Same seed, same English line: composition, costume, background and the timing of the mouth opening are nearly identical. Some small face details differ, but there's no added noise. That surprised me a little, because my earlier NVFP4 conversion of Qwen-Image 2.1 came out muddy.
The weights: [coolthor/Kandinsky-6.0-Pro-distill-5s-NVFP4](https://huggingface.co/coolthor/Kandinsky-6.0-Pro-distill-5s-NVFP4).
To use it: it loads natively in ComfyUI 0.38.2 with no node changes. Drop the file into `models/diffusion_models/`, pick it in Load Diffusion Model, and leave everything else as is.
kabachuha had already released an int8 version on Hugging Face, which needs ComfyUI PR #16825. When I checked on 10-08, I didn't see an NVFP4, fp8 or GGUF version.
## Lite gets English right and garbles Chinese
Lite is the 3B model. The official nodes block Lite distilled, so only the regular 50-step mode runs (no SageAttention): 488.7 to 498.7 s per clip. English came out correct. Chinese didn't. Whisper heard 微信来就爱一门呢 今天大家试试AAI什么系. That is unrecognizable.
For lip-sync, I'd use Pro distilled.
## Deep dive: install commands and the NVFP4 conversion
You can skip this section without missing anything you need to use the model. It's the full record for anyone reproducing the setup, or for an AI reading this page on someone's behalf.
### A separate ComfyUI 0.38.2 worktree, so the main install stays untouched
The official Kandinsky nodes need 0.38.0 or newer. Instead of upgrading my 0.37 install in place and risking the H3 nodes, I made a git worktree at v0.38.2 with its own venv (PowerShell):
```powershell
git -C C:\Users\coolt\ComfyUI fetch --tags origin
git -C C:\Users\coolt\ComfyUI worktree add --detach C:\Users\coolt\ComfyUI-k6 v0.38.2
python -m venv C:\Users\coolt\venv-k6
C:\Users\coolt\venv-k6\Scripts\python.exe -m pip install torch==2.13.0 torchvision torchaudio --index-url https://download.pytorch.org/whl/cu130
git clone --depth 1 https://github.com/kandinskylab/kandinsky-6 C:\Users\coolt\k6-src
Copy-Item -Recurse C:\Users\coolt\k6-src\comfyui C:\Users\coolt\ComfyUI-k6\custom_nodes\kandinsky6
```
It runs on port 8189; the old install keeps 8188. To undo: `git worktree remove` and delete the venv.
### The official nodes block the Lite distilled checkpoint
Loading the Lite distilled checkpoint fails in the official node's `register.py` with:
```
Distilled K6 Lite checkpoints are not supported.
```
So Lite runs in regular mode only: 50 steps, CFG 5.0, audio scaling 0.5302. This is a node limitation, not a broken model.
### pip stalled on big wheels; uv and an offline wheel fixed it
On Windows, pip stalled twice at 0 bytes while downloading large wheels from PyPI. curl fetched the same files without trouble. I switched to uv and installed SageAttention from an offline wheel:
```powershell
uv pip install --python C:\Users\coolt\venv-k6\Scripts\python.exe sageattention-2.2.0+cu130torch2.10.0andhigher.post6-cp310-abi3-win_amd64.whl triton-windows==3.7.1.post27
```
Smoke test:
```python
import torch, sageattention
q = torch.randn(1, 8, 256, 128, dtype=torch.float16, device="cuda")
print(sageattention.sageattn(q, q, q).shape)
```
### SageAttention took the first bf16 run from 277 s to 206.7 s
The first bf16 runs took 277.2 and 277.0 s. Installing SageAttention was the only change, and the next run took 206.7 s. One NVFP4 smoke run came in at 211.9 s, but I didn't record whether SageAttention was active for it, so I left it out of the chart.
### The NVFP4 conversion: comfy-quants, kand6 branch
The tool is Comfy-Org/comfy-quants. I used kabachuha's [`kand6` branch](https://github.com/kabachuha/comfy-quants/tree/kand6), commit `4b96626`. Config:
```yaml
model:
family: kandinsky6
dtype: bf16
components:
transformer: quantize
text_encoder: keep_bf16
vae: keep_bf16
audio_vae: keep_bf16
quant:
algorithm: nvfp4
target_dtype: nvfp4
scale:
granularity: block
axis: in_features
method: amax
rounding: nearest_even
modules:
include:
- "visual_transformer_blocks.*"
- "video_text_transformer_blocks.*"
- "audio_text_transformer_blocks.*"
exclude:
- "visual_transformer_blocks.0.*"
- "visual_transformer_blocks.1.*"
- "visual_transformer_blocks.58.*"
- "visual_transformer_blocks.59.*"
fallback:
on_error: keep_bf16
```
This quantized 1,840 Linear layers: 1,792 in the visual blocks, 24 in the video-text blocks, 24 in the audio-text blocks. Visual blocks 0, 1, 58 and 59 stay bf16, following LTX-2's official NVFP4 release; the first and last layers are more sensitive to precision. Norms and biases are copied as-is.
| | Source (bf16) | Output (NVFP4) |
|---|---|---|
| Size | 60,344,993,576 bytes | 20,094,169,424 bytes (18.71 GiB) |
| Tensors | 4,471 | 9,991 |
The tensor count goes up because each quantized Linear gets a `weight_scale` and a `weight_scale_2`. The conversion took 59.26 s, and the converter process peaked at 49.33 GiB (Windows working set).
That peak fits on a 61.6 GB machine because the exporter reads tensor by tensor from disk (`safe_open(..., device="cpu")`) and never loads all 60 GB at once.
### The first conversion failed at save_file
The first `save_file` failed because NumPy was missing from the venv, so nothing was written. Installing it with uv fixed the retry.
### Checking the output
The output key names match what the official ComfyUI node expects, so no renaming was needed. ffprobe on the smoke video shows 121 frames and 44,100 Hz audio, and the ComfyUI log shows native `nvfp4` mixed-precision ops.
---
# Testing EmbeddingGemma 2 on Our Knowledge Base: Recall@5 from 50% to 58.3%
URL: https://ai-muninn.com/en/blog/embeddinggemma-2-knowledge-base-test
Date: 2026-10-07
Series: AI Workflow (Part 24)
import YouTubeEmbed from "@/components/YouTubeEmbed";
I tested EmbeddingGemma 2 against v1 as the search model for my AI assistant's notes, same code and precision on an M1 Max. Note search: recall@5 went from 50.0% to 58.3%, MRR from 0.4406 to 0.4855, and no query dropped out of the top 5. Code search: correct file ranked first 4/10 vs 1/10. Cost: indexing 1.7x slower, peak memory 1.03 GiB to 2.75 GiB, query latency unchanged. Image search on scene pictures mostly worked; music search missed. The test ran separately; the production knowledge base still runs v1 and can't switch yet, because llama.cpp can't load v2.
---
## Why I tested v2
My AI assistant searches its own notes before it starts any task. The search tool is [qmd](https://github.com/tobi/qmd), a local search engine, and its "search by meaning" side runs Google's EmbeddingGemma v1 (`embeddinggemma-300M-Q8_0`, a GGUF file) through llama.cpp. It gets called dozens of times a day.
An embedding model turns text into a list of numbers, so text with similar meaning ends up with similar numbers. EmbeddingGemma's list has 768 numbers (768 dimensions). Search ranks notes by how close their numbers are to the query's.
Google shipped EmbeddingGemma 2. I wanted two answers: if I swap v1 for v2, does the assistant find the right note more often, and what does it cost in memory and time?
## What v2 adds: images and audio in the same 768-dim space, and a big code score jump
Most of the table is context. The two rows that matter for a text knowledge base are the code score and the size, which tells you where the extra memory goes.
| | v1 ([embeddinggemma-300m](https://huggingface.co/google/embeddinggemma-300m)) | v2 ([embeddinggemma-2](https://huggingface.co/google/embeddinggemma-2)) |
|---|---|---|
| Inputs | Text | Text, images, video, audio, one shared 768-dim space |
| Size | 300M (per the name) | 740M = text 270M + image 170M + audio 300M |
| MTEB multilingual text | 61.15 | 61.36 |
| MTEB code | 68.76 | 78.68 |
v2 is Apache 2.0 (v1 ships under the Gemma license) and covers 100+ languages. With both the image and audio parts turned off, v2 loads only its 270M text part; my code below turns off audio only, so it loads text plus image. The official numbers say text quality barely moved and code moved a lot. Google's [announcement post](https://blog.google/innovation-and-ai/technology/developers-tools/embeddinggemma-2) has the rest.
## How I tested: take one line from my log and see if it finds its note
In short: I use 60 lines from my LOG as test questions, each with a known answer (the note it originally linked to), and I count how often each model ranks that answer in the top 5. If you don't plan to run the code, this paragraph and the figure below are enough.
Every time my assistant finishes a task, it appends one line to a LOG file. The line ends with `→ [[note-name]]`, pointing at the note where the details live. That gives me free test data: strip the link, use the rest of the sentence as the search query, rank all 813 notes, and check where the linked note lands.
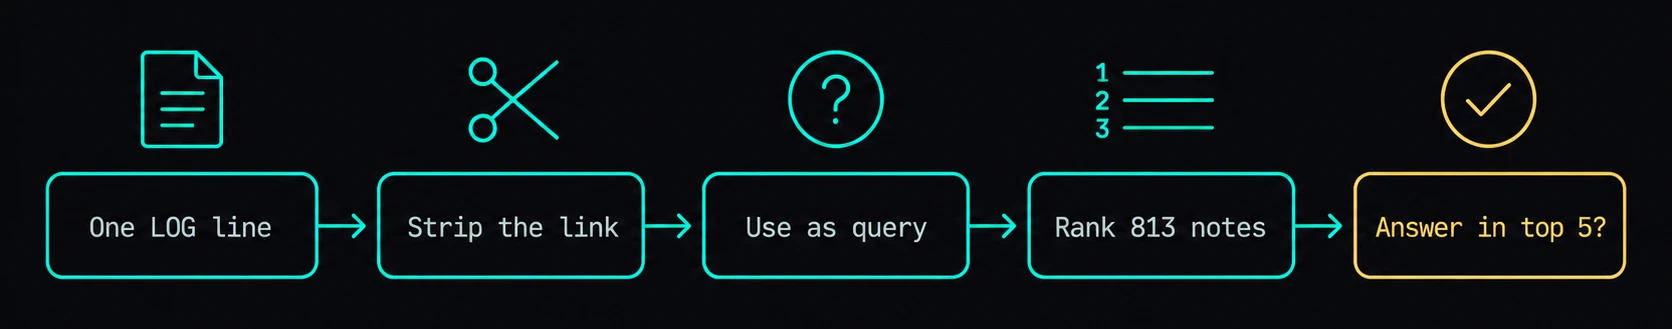
I sampled 60 of the 1,547 eligible lines with a fixed seed. Three numbers come out:
- **recall@1**: the correct note is ranked first.
- **recall@5**: the correct note is somewhere in the top 5. This is closest to real use, since the assistant reads several notes per lookup.
- **MRR** (mean reciprocal rank): the average of 1/rank. First place scores 1, second 0.5, and so on.
### Running it yourself: the core code
Both generations ran through the same code, in float32, on the Mac's GPU (MPS):
```python
import torch
from sentence_transformers import SentenceTransformer
model = SentenceTransformer(
"google/embeddinggemma-2", # v1: google/embeddinggemma-300m
device="mps",
model_kwargs={"torch_dtype": torch.float32},
config_kwargs={"audio_config": None}, # skip the audio encoder for text/image-only search
)
docs = model.encode(
[f"title: {name} | text: {body[:1500]}" for name, body in notes],
batch_size=16,
)
query = model.encode("task: search result | query: " + log_line)
```
Each note goes in as its first 1,500 characters, formatted `title: | text: `. Each query gets the prefix `task: search result | query: `. The prefix string is identical for both generations; I checked.
For the second test (code search), the setup is the same, with source files as the documents and the prefix `task: code retrieval | query: `.
## Before you run it: no float16, v1 is gated, and watch Mac memory
- **Don't use float16.** The model card says it produces NaN. I ran float32 for both.
- **v1 on Hugging Face is gated.** You have to accept the license first. An anonymous download returns 401.
- **On a Mac, if memory blows up,** lower `batch_size` or run each test in its own process. I hit this one; details are in the deep dive.
## Note search: recall@5 went from 50% to 58.3%, and nothing fell out of the top 5
Look at the recall@5 row. That's the one that maps to how the assistant actually uses search.
| 60 queries, 813 notes | v1 | v2 |
|---|---|---|
| recall@1 | 38.3% (23) | 41.7% (25) |
| recall@5 | 50.0% (30) | 58.3% (35) |
| MRR | 0.4406 | 0.4855 |
The 5 extra top-5 hits are all new entries; no query that v1 had in the top 5 fell out with v2. At top-1, v2 fixed 2 queries that v1 missed and lost none. Per query, 25 ranks improved, 25 stayed the same and 10 got worse, but none of those 10 fell out of the top 5 or lost first place. In both of v2's wins, two notes covered the same event. v1 picked the related note; v2 picked the one the LOG line actually pointed to. For a query about reassigning a stalled job, v1 found the note about the stall, and v2 found the reassignment decision.
The other thing the table says: even with v2, about 40% of log lines don't find their note in the top 5. A log line is a one-line conclusion; the note it points to opens with background. The wording differs a lot.
## Code search: top-1 went from 1/10 to 4/10
For code I used the open-source inference engine [TensorFold](https://github.com/ashhart/TensorFold) 0.6.6: 424 `.py` and `.cu` files, and 10 questions written in Chinese, like "how does the recurrent state round at each step."
The correct file ranked first for 1 of 10 questions with v1 and 4 of 10 with v2. Recall@3 was also 0.10 vs 0.40. That's the same direction as the official MTEB code score.
v2's three extra wins were questions about recurrent state rounding (`cuda/kernels/gdn.cu`), the DFlash2 CPU best-first search (`drafters/dflash_tree.py`), and walking the draft tree to find the accepted path (`kernels/qwen/dense/v1/lane_tree.py`). Both models failed badly on "prune orphan nodes": the question uses a metaphor, and the word "orphan" never appears in the code. v1 ranked the right file 91st, v2 ranked it 308th. Ten questions is a small sample, so read this as direction only.
## Cost: indexing 1.7x slower, peak memory from 1.03 GiB to 2.75 GiB
The memory row is the one to watch if you run this on a laptop next to other things.
| M1 Max, float32 | v1 | v2 |
|---|---|---|
| Index 813 notes | 81.8 s | 138.8 s |
| Median query latency (70 queries) | 50.3 ms | 48.3 ms |
| Peak RSS | 1.03 GiB | 2.75 GiB |
| Load time | 7.7 s | 7.6 s |
v2 here had its text and image parts loaded, not audio. RSS doesn't fully count what MPS allocates on the GPU side, so real usage is only higher. Query latency was essentially unchanged.
## Image search mostly worked; music search missed
v2 puts images and audio in the same space as text, so I tried both. These ran on v2 only.
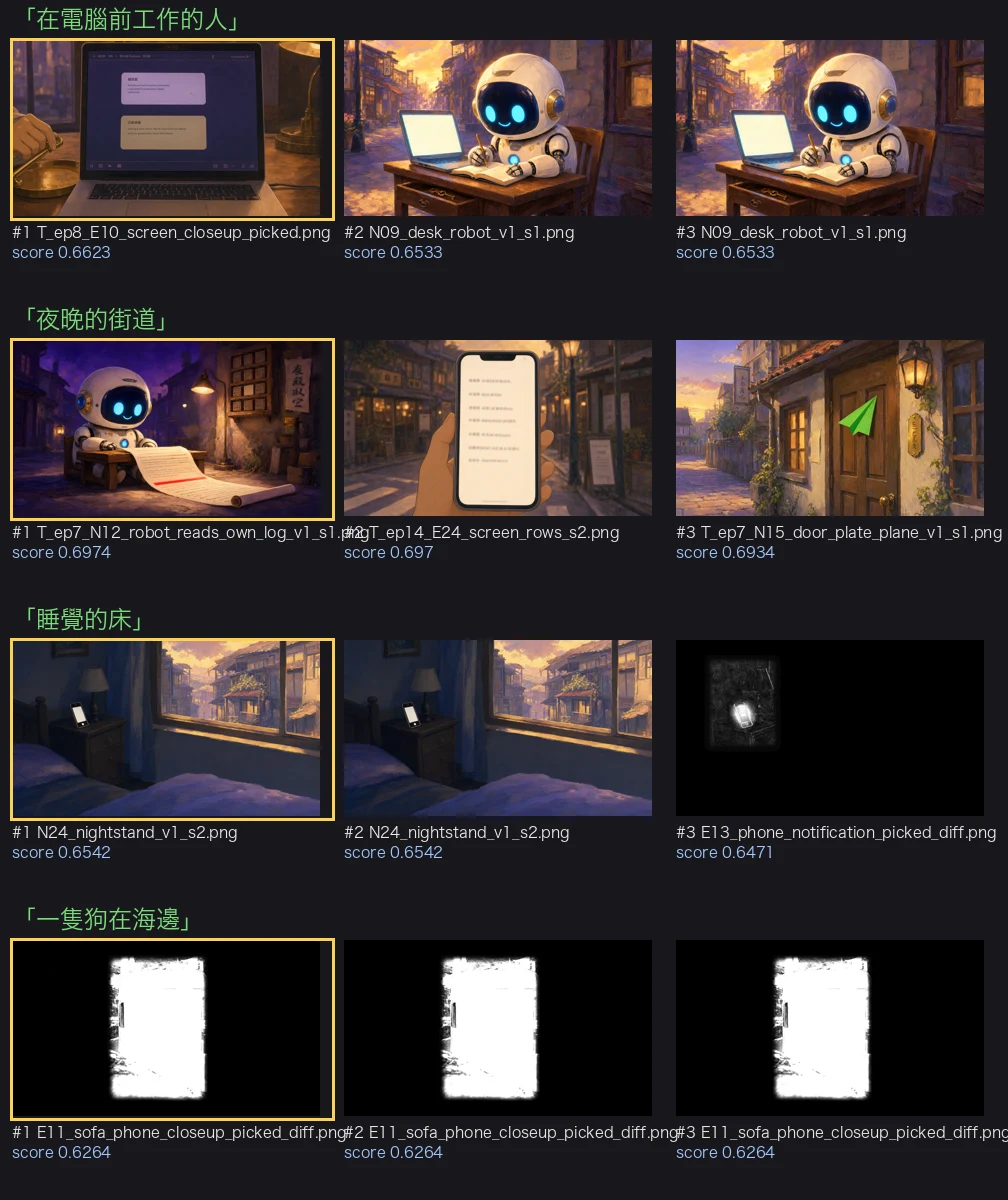
**Images.** I took 300 random anime-style scene images from my explainer-video keyframes (2,553 total) and indexed them in 105.1 s. All three real queries returned a reasonable first result, though one was only a rough match. The control query, "a dog at the beach," had no matching image in the library, and its top-1 got the lowest score of the four.
Searching screenshots worked less well. On 200 images from this blog's `public/` folder, 2 of 3 queries were right, but all scores sat between 0.66 and 0.70 and the gap between first and second place was under 0.01.
**Audio.** 40 clips, first 20 seconds each: 22 narration, 12 music, 6 sound effects. "A person talking" returned narration for all top 3. "Upbeat music" returned two speech clips and then a mix with narration over it; the pure-music intro didn't make the top 3. My library has only one genuinely distinct music track, so the test set is weak, but the result is a miss.
Encoding images and audio uses the same `model.encode`, with dicts instead of strings:
```python
model.encode([{"image": PIL.Image.open(path).convert("RGB")}])
model.encode([{"audio": path}]) # needs librosa; don't pass audio_config=None
```
## Did I switch? Not yet: llama.cpp can't load v2
qmd runs GGUF models through llama.cpp. I pointed Homebrew's llama.cpp v9750 at the v2 GGUF (`ggml-org/embeddinggemma-2-GGUF`, Q8_0) and got this:
```
unknown model architecture: 'gemma-embedding2'
```
Even once it loads, switching means re-indexing everything: v1 and v2 vectors don't live in the same space, so you can't mix them. The plan is to build a second index next to qmd's current one when llama.cpp adds support, run both side by side for a few days, then decide. The whole test ran outside qmd; it never touched qmd's config or production index.
## Deep dive: per-question results, screenshot search, and the problems I hit
You can skip this section; the results above stand on their own. This is the full detail for anyone reproducing the test, or for an AI reading this page on someone's behalf.
### Environment
- Apple M1 Max, 32 GB, macOS 27.0.1
- sentence-transformers 6.1.0, transformers 5.19.0, torch 2.14.1
- float32, device `mps`, both generations
- v1: `google/embeddinggemma-300m`; v2: `google/embeddinggemma-2`
### How test A was built
- Source: my LOG files, one line per finished task, each ending in `→ [[note-name]]`.
- 1,547 lines were eligible. I sampled 60 with `seed=7`.
- Corpus: 813 notes. Excluded: the LOG files themselves, `MEMORY.md`, and `KB_MAP.md`.
- Documents: first 1,500 characters, formatted `title: | text: `.
- Query prefix: `task: search result | query: `. v1's sentence-transformers prompt list doesn't include a prompt named `SearchQuery`, so I spliced the prefix in by hand for both generations, so the string is byte-identical.
### The two queries v2 fixed
Both are cases where one event produced two notes.
1. A query about reassigning a job to another coding agent after the first one stalled twice. The correct note was `feedback_dispatch_fallback_chain_2026-09-21.md`. v1 ranked `discovery_agy_print_mode_kills_background_jobs_2026-09-21.md` first, the note about why the first agent died.
2. A query about promoting cc-dash-kit with social posts only, with drafts in blog-staging. The correct note was `reference_buffer_social_post_method.md`. v1 ranked `project_goal_only_harness_rollout_2026-09-23.md` first.
### Test B per question
Rank of the correct file, 1 = first place.
| Question (written in Chinese) | Correct file | v1 | v2 |
|---|---|---|---|
| Sampling RNG from seed + position | `engine/exact_sampling.py` | 1 | 1 |
| Prune orphan nodes | `engine/lane_engine.py` | 91 | 308 |
| Find a repeated span in prior text as a draft | `engine/lane_engine.py` | 12 | 32 |
| Which draft source this round | `engine/lane_family.py` | 144 | 15 |
| Boot-time bitwise check, how many rows | `families/glm5_next/runtime.py` | 228 | 117 |
| 4-bit matmul per row | `cuda/kernels/qmm.py` | 22 | 6 |
| Recurrent state rounding each step | `cuda/kernels/gdn.cu` | 8 | 1 |
| DFlash2 CPU best-first | `drafters/dflash_tree.py` | 20 | 1 |
| GPU minimum version check | `cuda/build.py` | 29 | 7 |
| Walk the draft tree for the accepted path | `kernels/qwen/dense/v1/lane_tree.py` | 4 | 1 |
Two got worse (orphan nodes, repeated span). Three improved a lot without reaching first place (draft source, 4-bit matmul, GPU version check).
### v2 ran out of MPS memory on test B
When I ran test B right after test A in the same process, v2's MPS "other allocations" grew to 35–38 GB and it went out of memory at batch size 16, then 4, then 2. v1 was fine in the same setup.
What fixed it:
- Run each test in its own process.
- Call `torch.mps.empty_cache()` periodically.
- Set `max_seq_length=2048`. That matches v1's native 2,048-token limit, so both models read the same length of each file.
Because of that extra load, v2's test B index time (167.5 s vs v1's 102.5 s) isn't a fair comparison. Use the test A numbers for cost.
### A literal `<|image|>` string in the code breaks v2
TensorFold's `vision/glm_processing.py` contains the literal string `<|image|>`. v2's multimodal processor treats that as an image placeholder, finds no image attached, and errors out. I changed it to `<| image |>` in both generations' corpus, in that one file only. Metrics were unchanged on a rerun.
If you index code or chat templates with v2, grep the corpus for special tokens first.
### Screenshot search (test C, v2 only)
200 random images from this blog's `public/` folder (`seed=7`). Indexing took 80.4 s, peak RSS 3.59 GiB.
| Query | Top-1 | Score | Right? |
|---|---|---|---|
| Screenshot with a bar chart | A phone chat screenshot | 0.6974 | No |
| Terminal screen | A terminal dashboard screenshot | 0.6812 | Yes |
| Mobile web page | A mobile layout screenshot | 0.6877 | Yes |
All scores fell between 0.66 and 0.70, and top-1 beat top-2 by less than 0.01 every time.
### Scene images and audio, in detail
Scene images: 300 sampled from 2,553 keyframes with `random.seed(11)`, indexed in 105.1 s.
- "A person working at a computer": a laptop screen close-up with a person's hand, 0.6623. Roughly right; "robot typing at a desk," a better fit, ranked 2nd.
- "Street at night": a night alley with a robot, 0.6974. Right.
- "Bed for sleeping": a night bedroom bedside, 0.6542. Right.
- "A dog at the beach" (control; no dog or beach in the library): a black-and-white diff image, 0.6264, the lowest top-1 of the four.
Some images exist in two folders, so the same image shows up twice in a row in the results.
Audio: 40 clips, first 20 seconds each, 16 kHz mono WAV (22 narration, 12 music, 6 sound effects). Indexing took 7.5 s.
- "A person talking": top 3 all narration, scores 0.754, 0.751, 0.750.
- "Upbeat music": two narration clips (0.6991, 0.6952), then a music mix with narration (0.6936). The pure-music intro jingle wasn't in the top 3.
The only genuinely distinct music track in my library is that intro jingle; the rest are copies of it or mixes with narration. Audio needs `librosa` installed, and you must not pass `audio_config=None` since that skips the audio encoder.
### llama.cpp support
qmd uses GGUF through llama.cpp, so production depends on llama.cpp support, not sentence-transformers. The v2 GGUF from `ggml-org/embeddinggemma-2-GGUF` comes as two files: the Q8_0 text model (310 MB) and a Q8_0 mmproj for images (555 MB). Homebrew llama.cpp v9750 rejects it at load with `unknown model architecture: 'gemma-embedding2'`.
When support lands, I'll build a v2 index alongside qmd's current v1 index (v1 and v2 vectors aren't compatible, so it has to be a full re-index), compare the two side by side for a few days, and then decide whether to switch.
The short is also on YouTube: [EmbeddingGemma 2 in one minute](https://youtube.com/shorts/N3uu9U5naa4).
Previous in this series: [From Markdown Search to a Knowledge Graph: How My AI's Memory Grew a Second Layer](/en/blog/from-markdown-search-to-knowledge-graph).
---
# Qwen3.8-Flash-Next 177B on One RTX 2080 Ti: Strata Runs Code at 70 tok/s
URL: https://ai-muninn.com/en/blog/strata-flashnext-one-2080ti
Date: 2026-10-06
Series: 改裝 2080 Ti 22G (Part 23)
import YouTubeEmbed from "@/components/YouTubeEmbed";
One modded RTX 2080 Ti 22GB plus 128 GB of RAM runs the 177B Qwen3.8-Flash-Next (IQ3_S) under Strata at **70.3 tok/s on code**, 52.9 on Chinese, 51.5 on English. Two cards do 91.4 on code; one card is 23% slower. On the GPU, Strata uses 21.6 GB of the card's 22 GB of VRAM for attention, the router, shared experts, the KV cache, and the most-used experts. System RAM holds a copy of every expert, and the CPU runs the experts that aren't on the GPU directly from system RAM; available RAM drops by 37–48 GB once Strata is up. It runs next to my 27B with a 1.3% slowdown and swaps with ComfyUI in about 5 minutes. Caveat: Strata defaults to xhigh thinking effort; send low.
## Why I tried this: the 27B is maxed out, and the 177B used to need the whole machine
My ai-lab box is an EPYC with 128 GB of RAM and three modded RTX 2080 Ti 22GB. Cards 0 and 1 run Qwen3.8-27B under FastLLM ([part 22](/en/blog/fastllm-dual-2080ti-nvfp4-self-quant)). Card 2 belongs to ComfyUI for image and video work, which comes in bursts and sits idle for days at a time.
The 27B is about as fast as I can make it, but it's still a 27B. I wanted the 177B Qwen3.8-Flash-Next. [Part 17](/en/blog/qwen4exp-177b-three-2080ti) ran the same 177B with llama.cpp across all three cards: 23.14 tok/s at 128K context (26.16 at 32K). That took the whole machine. The 27B and ComfyUI had to stop.
This part puts the 177B on the idle third card alone, using [Strata](https://github.com/Niko1221/Strata), and leaves the 27B running.
## One card runs code at 70.3 tok/s, 23% slower than two
Same prompts on one card (GPU2) and on two (GPU0+1). Method: streaming, thinking off, 650 max tokens, 3 runs each, median; decode speed comes from Strata's `/metrics`.
| | one card | two cards | change |
|---|---:|---:|---:|
| code / Chinese / English tok/s | **70.3** / 52.9 / 51.5 | 91.4 / 60.0 / 60.0 | −23% / −12% / −14% |
| 16K prompt: time to first token | 12.2 s | 10.6 s | |
| 16K prompt: prefill | 1,325 tok/s | 1,525 tok/s | |
| 16K prompt: decode | 49.8 tok/s | 66.1 tok/s | |
VRAM in use on the single card: 21.6 GB.
Code generation takes the biggest hit without the second card. My guess is that code hits a concentrated set of experts, so the second card's extra cache catches more of them. I didn't measure expert usage to confirm that.
Part 17's 77.56 tok/s doesn't belong in this comparison. That was n-gram speculative decoding on a file-edit task where the output is mostly copied from the input.
## How Strata fits 177B on one card: the GPU holds what every token uses, RAM holds the experts
Flash-Next is a mixture-of-experts model: 48 layers, 512 experts each. Each token runs through 10 routed experts plus 1 shared expert per layer, so most of the weights sit unused on any given token. Strata splits the model along that line.
To watch the weights move from disk into RAM and then into VRAM step by step, open the [interactive version](https://model.ai-muninn.com/en/launchers/strata/). It shows VRAM, RAM and the SSD as separate regions, uses moving dots to show data flow, and labels each connection with its bandwidth.
- **On the GPU:** the attention and DeltaNet mixers, the router, the shared experts, the output head, the MTP draft layer and the KV cache (with 128K context, only the most-read 32K stays here). Whatever VRAM is left becomes a cache of the most-used experts. The cache adapts as you chat.
- **In RAM:** all 24,576 routed experts (48 × 512), pinned. When a token needs an expert that isn't cached, the CPU computes it in place, in parallel with the GPU, instead of copying it over.
- **The n-gram table:** 28.8 GB. By default Strata reads it directly from SSD (`--ple-io direct`). I set `--ple-io ram`; I measured no speed difference.
- **MTP:** the model ships with its own multi-token prediction layer. It drafts a few tokens ahead and the main model checks them in one pass, so the output is identical to running without it.
## What you need: a 22 GB card, 64 GB of RAM at minimum, about 90 GB of disk
- **GPU:** I used a modded 2080 Ti 22GB, and Strata used 21.6 GB of it. Strata compiled cleanly for sm_75 (Turing).
- **RAM:** Strata's setup lists IQ3_S at 62 GB and says it "needs a 64 GB PC with little else running". On my box, available memory dropped by 47.6, 37.0 and 39.5 GiB across three loads, with the n-gram table in RAM. That's the whole machine's available memory, not Strata's own footprint.
- **Disk:** the two GGUF shards are 54.8 GB + 28.8 GB = 83.6 GB. Add the MTP weights setup fetches (6.5 GiB) and the pack (1.5 GiB), and `du` puts the whole directory at about 86 GiB. Leave 90 GB.
- **Toolchain:** Python 3.10+, g++ and nvcc. No sudo needed if those are already there. I built against CUDA 12.4.
The model is [ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-GGUF](https://huggingface.co/ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-GGUF), quant IQ3_S.
## Install: one setup.py run builds the CUDA kernels and fetches the weights
Clone the repo and pin the commit I used:
```bash
git clone https://github.com/Niko1221/Strata
cd Strata
git checkout 6f32ec07
```
Then create a venv in the repo and run setup. I kept every cache on the NVMe drive:
```bash
python3 -m venv .venv
export XDG_CONFIG_HOME=/mnt/nvme1t/strata/config
export PIP_CACHE_DIR=/mnt/nvme1t/strata/pip-cache
export TMPDIR=/mnt/nvme1t/strata/tmp
export HF_HOME=/mnt/nvme1t/strata/data/hf
.venv/bin/python setup.py --family qwen --model IQ3_S --gpu 0 --cuda 12 --build \
--context 32768 --kv int8 --vision no \
--data-dir /mnt/nvme1t/strata/data \
--port 8096 --host 127.0.0.1 --no-browser --no-start \
--low-ram off --yes
```
A few notes:
- `--build --cuda 12` compiles from source. `cuobjdump` on the result shows 58 sm_75 ELF sections, so the 2080 Ti gets native kernels.
- `--low-ram off` was needed because the 27B and ComfyUI were running during install, so setup saw too little free RAM.
- Setup fetches the MTP weights from Qwen's official repo and checks each tensor's SHA-256.
- I pre-downloaded the two shards with `curl -C -` (resumable) and checked their SHA-256 against Hugging Face.
- It's done when setup prints `All set.`
## Config, launch, first request: an OpenAI-compatible server on port 8096
My config file, `strata-iq3_s-gpu2.json`, sets these flags:
| flag | value | what it does |
|---|---|---|
| `--expert-cache` / `--prefill` | `auto` | expert cache size and prefill mode chosen by Strata |
| `--spec` / `--spec-min-p` | `4` / `0.5` | speculative drafting settings for the MTP layer |
| `--max-context` / `--kv` | `131072` / `int8` | 128K context, int8 KV cache |
| `--kv-resident` | `32768` | keeps the most-read 32K of KV on the GPU; the rest streams from RAM |
| `--ple-io` | `ram` | n-gram table in RAM instead of SSD reads |
It also sets `--mtp` to the MTP weights directory, `"parallel": 1` and the alias `shio`. Keep `parallel` at 1; the deep dive explains why.
To pin Strata to the third card, select it by UUID. Strata still sees it as GPU 0:
```bash
export CUDA_VISIBLE_DEVICES=
export STRATA_BF16_TC=1
.venv/bin/python serve/server.py --engine strata \
--config strata-iq3_s-gpu2.json \
--host 0.0.0.0 --port 8096 --gpu 0
```
Loading takes a few minutes. It's ready when `/v1/models` returns 200. Then:
```bash
curl -s http://localhost:8096/v1/chat/completions \
-H "Content-Type: application/json" \
-d '{
"model": "shio",
"messages": [{"role": "user", "content": "Write a Python function that merges two sorted lists."}],
"reasoning_effort": "low",
"stream": false
}'
```
Keep `"reasoning_effort": "low"`. Strata turns thinking on at effort xhigh by default, which on a 140-question set took 3.4× as long for a lower score. Details are in the deep dive.
## Running next to the 27B costs Strata 1.3% and the 27B 7.7%
The two models are on different GPUs, so the only shared resources are the CPU and memory bandwidth. I sent the same code prompt to both at once, 3 rounds.
| | alone | both at once | change |
|---|---:|---:|---:|
| Strata (one card) | 70.3 tok/s | 69.4 | −1.3% |
| 27B (two cards) | 243.1 tok/s | 224.4 | −7.7% |
I'm assuming the contention is CPU or memory bandwidth; I didn't isolate it. Also, the overlap is short: the 27B finishes in about 3 s and Strata takes 10–12 s, so they only compete during Strata's first ~3 s.
The 27B never restarted. A health check every 5 s returned 106/106 HTTP 200.
The 243.1 uses this article's method (streaming, thinking off, 650 tokens). Part 22's 151.7 used a different method; don't compare them.
## Sharing the card with ComfyUI: 5 minutes to switch to Shio, 12 seconds back
I call the Strata service on the third GPU Shio, after 汐 (tide). GPU2 runs Shio normally and switches to ComfyUI when I do video work.
I set `Conflicts=` between the two systemd user services, so starting one stops the other. A small script drives them:
```bash
~/bin/gpu2-mode shio # switch to Strata
~/bin/gpu2-mode comfy # switch to ComfyUI
~/bin/gpu2-mode status
```
The script has three guards:
- It refuses to switch to Shio while ComfyUI's queue has jobs.
- It waits for Shio to go idle before switching to ComfyUI.
- If the target side isn't ready within 10 minutes, it rolls back to the previous side.
Measured over 3 rounds:
| direction | ready | first result |
|---|---:|---:|
| ComfyUI → Shio | 281–334 s | first request 2.6–3.4 s after ready |
| Shio → ComfyUI | 12.4 s | first 512px image 30.5–31 s (cold model load); second 18.3–18.4 s |
From the command to the first ComfyUI image is about 43 s. Rounds 2 and 3 were faster than round 1, possibly from the OS page cache; I didn't isolate that. ComfyUI is still the boot default; Shio isn't enabled at boot.
---
## Deep dive: parallel, thinking effort, 16K numbers, dead ends and versions
You can skip this section; everything you need to run the setup is above. This is the data behind the settings.
### `parallel: 2` slows even a single request
Strata's batch path doesn't use MTP drafting, but its docs say a request running alone still takes the MTP path. I measured a slowdown anyway, even with one request, and haven't tracked down why. Setting `parallel` back to 1 fixes it.
| setting | requests | per request | total |
|---|---:|---:|---:|
| `parallel: 2` | 1 | 60.32 tok/s | 54.49 (over full batch wall time) |
| `parallel: 2` | 2 | 30.39 / 32.26 | 60.23 |
| `parallel: 1` | 1 | 67.2, 70.1 | |
Two concurrent requests together get less throughput than one request with `parallel: 1`. The ComfyUI switching test happened to run with `parallel: 2` and saw 44.4, 60.3 and 44.8 tok/s. Back on `parallel: 1`, two checks gave 67.2 and 70.1.
### Thinking defaults to xhigh; low scored higher in under a third of the time
Strata enables thinking at effort xhigh by default. I don't have a capability run on Shio itself, but I have the same 140-question set on the same model, Qwen3.8-Flash-Next, on a different machine and engine (GX10, vLLM, NVFP4):
| effort | score | time |
|---|---:|---:|
| low | 126 | 1,736 s |
| xhigh | 117 | 5,902 s |
Only the relative gap carries over.
Two ways to fix it:
1. Send `"reasoning_effort": "low"` on every request.
2. What I did: 3 lines in `serve/server.py`'s OpenAI entry point. If a request carries no effort at all, fill in `low`.
Strata's `/settings` page has a shared default, but it only applies when the request has no thinking parameters at all. Clients that send only an "enable thinking" flag skip it. My client, Pi, does exactly that, so the server patch was the only thing that worked for it.
### The 16K numbers were measured at 32K max context, one shot each
The 16K-prompt rows (TTFT, prefill, decode) ran with `--max-context 32768`, one shot per setting. Production uses 128K with `--kv-resident 32768`. I re-measured code on the production config: 70.1 tok/s, in line with the 70.3 from the main table.
### Dual-card speed tricks that didn't help
I tried several things on the two-card setup; the next post covers them in detail.
- `--ple-io ram` vs `direct`: no difference.
- `--peer-device` (use NVLink between the cards): about 10% slower.
- Using the third card as an expert helper for the two-card setup: code went from 91.4 to 48 tok/s (−47%).
The one flag that did help was `STRATA_BF16_TC=1`. On two cards it cut 16K TTFT from 12.6 s to 10.6 s. Single-card Shio uses that and nothing else from this list.
### Versions
- Strata engine 0.1.39, commit `6f32ec07`, built with `--build --cuda 12`
- CUDA 12.4, sm_75; `cuobjdump` shows 58 sm_75 ELF sections
- Model: ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-GGUF, IQ3_S, two shards (54.8 GB + 28.8 GB)
- MTP weights from Qwen's official repo, per-tensor SHA-256 checked
- Draft vocab: Strata's built-in CJK subset, 106,299 ids
- Env: `STRATA_BF16_TC=1`
### What I didn't measure
- The 140-question set on Shio itself.
---
**Also in this series:**
- [#22 NVFP4 Without FP4 Hardware: Qwen3.8-27B on Two RTX 2080 Tis at 151.7 tok/s](/en/blog/fastllm-dual-2080ti-nvfp4-self-quant)
- [#21 Dual RTX 2080 Ti FastLLM: 16% Faster Decoding and No More Head-of-Line Blocking](/en/blog/fastllm-dual-2080ti-concurrency-scheduler)
- [#17 A 177B MoE on Three Modded 2080 Tis: 23 tok/s at 128K, 77 on a File Edit](/en/blog/qwen4exp-177b-three-2080ti)
---
# [Claude Code] Build a Resource Dashboard Inside Claude Code With Six Prompts
URL: https://ai-muninn.com/en/blog/claude-code-mods-resource-dashboard
Date: 2026-10-04
Series: AI Workflow (Part 23)
import YouTubeEmbed from "@/components/YouTubeEmbed";
Claude Code mods (v2.1.287+) let you customize the terminal or desktop app you already work in, so you can see what's going on at a glance. I used them to build a pane that shows which machines have capacity and which subscriptions still have quota. Is it hard? No. Ask Claude Code for a simple version built around whatever you check most often, then nitpick it like a demanding boss until you're happy. With the prompts in this post, the first pane took 2 min 51 s. Caveat: mods run with Claude Code's permissions and no sandbox.
> **Update (2026-10-06):** I packaged this approach as an open-source repo, [cc-dash-kit](https://github.com/coolthor/cc-dash-kit). If you'd rather not paste six prompts, paste this into Claude Code and it installs the dashboard: `Install this Claude Code dashboard for me: https://github.com/coolthor/cc-dash-kit`. Then ask Claude to customize it for your setup.
## Claude kept dispatching work to machines that couldn't take it
A sign at the parking garage entrance says level 1 is full and level 2 has 3 spots. You skip level 1 and head straight down.
My setup had no sign like that. I run models on a few machines and pay for a few AI subscriptions. When I asked Claude to dispatch a job, it would sometimes write up the whole task, send it, and only then find out the quota was used up, the machine was busy, or the machine was down. Then it had to dispatch all over again. That's the software version of circling every level.
Claude Code mods, supported since v2.1.287 ([announcement](https://claude.com/blog/claude-code-mods)), fix this. A mod can show the numbers in a pane for me, and Claude can fetch the same numbers with a tool call. I started by asking Claude Code which things I kept checking over and over, and let it suggest what to build. I split the result into six prompts here so each step is easy to follow. Paste them in order, nitpick the looks a bit, and you end up with a pane like this:
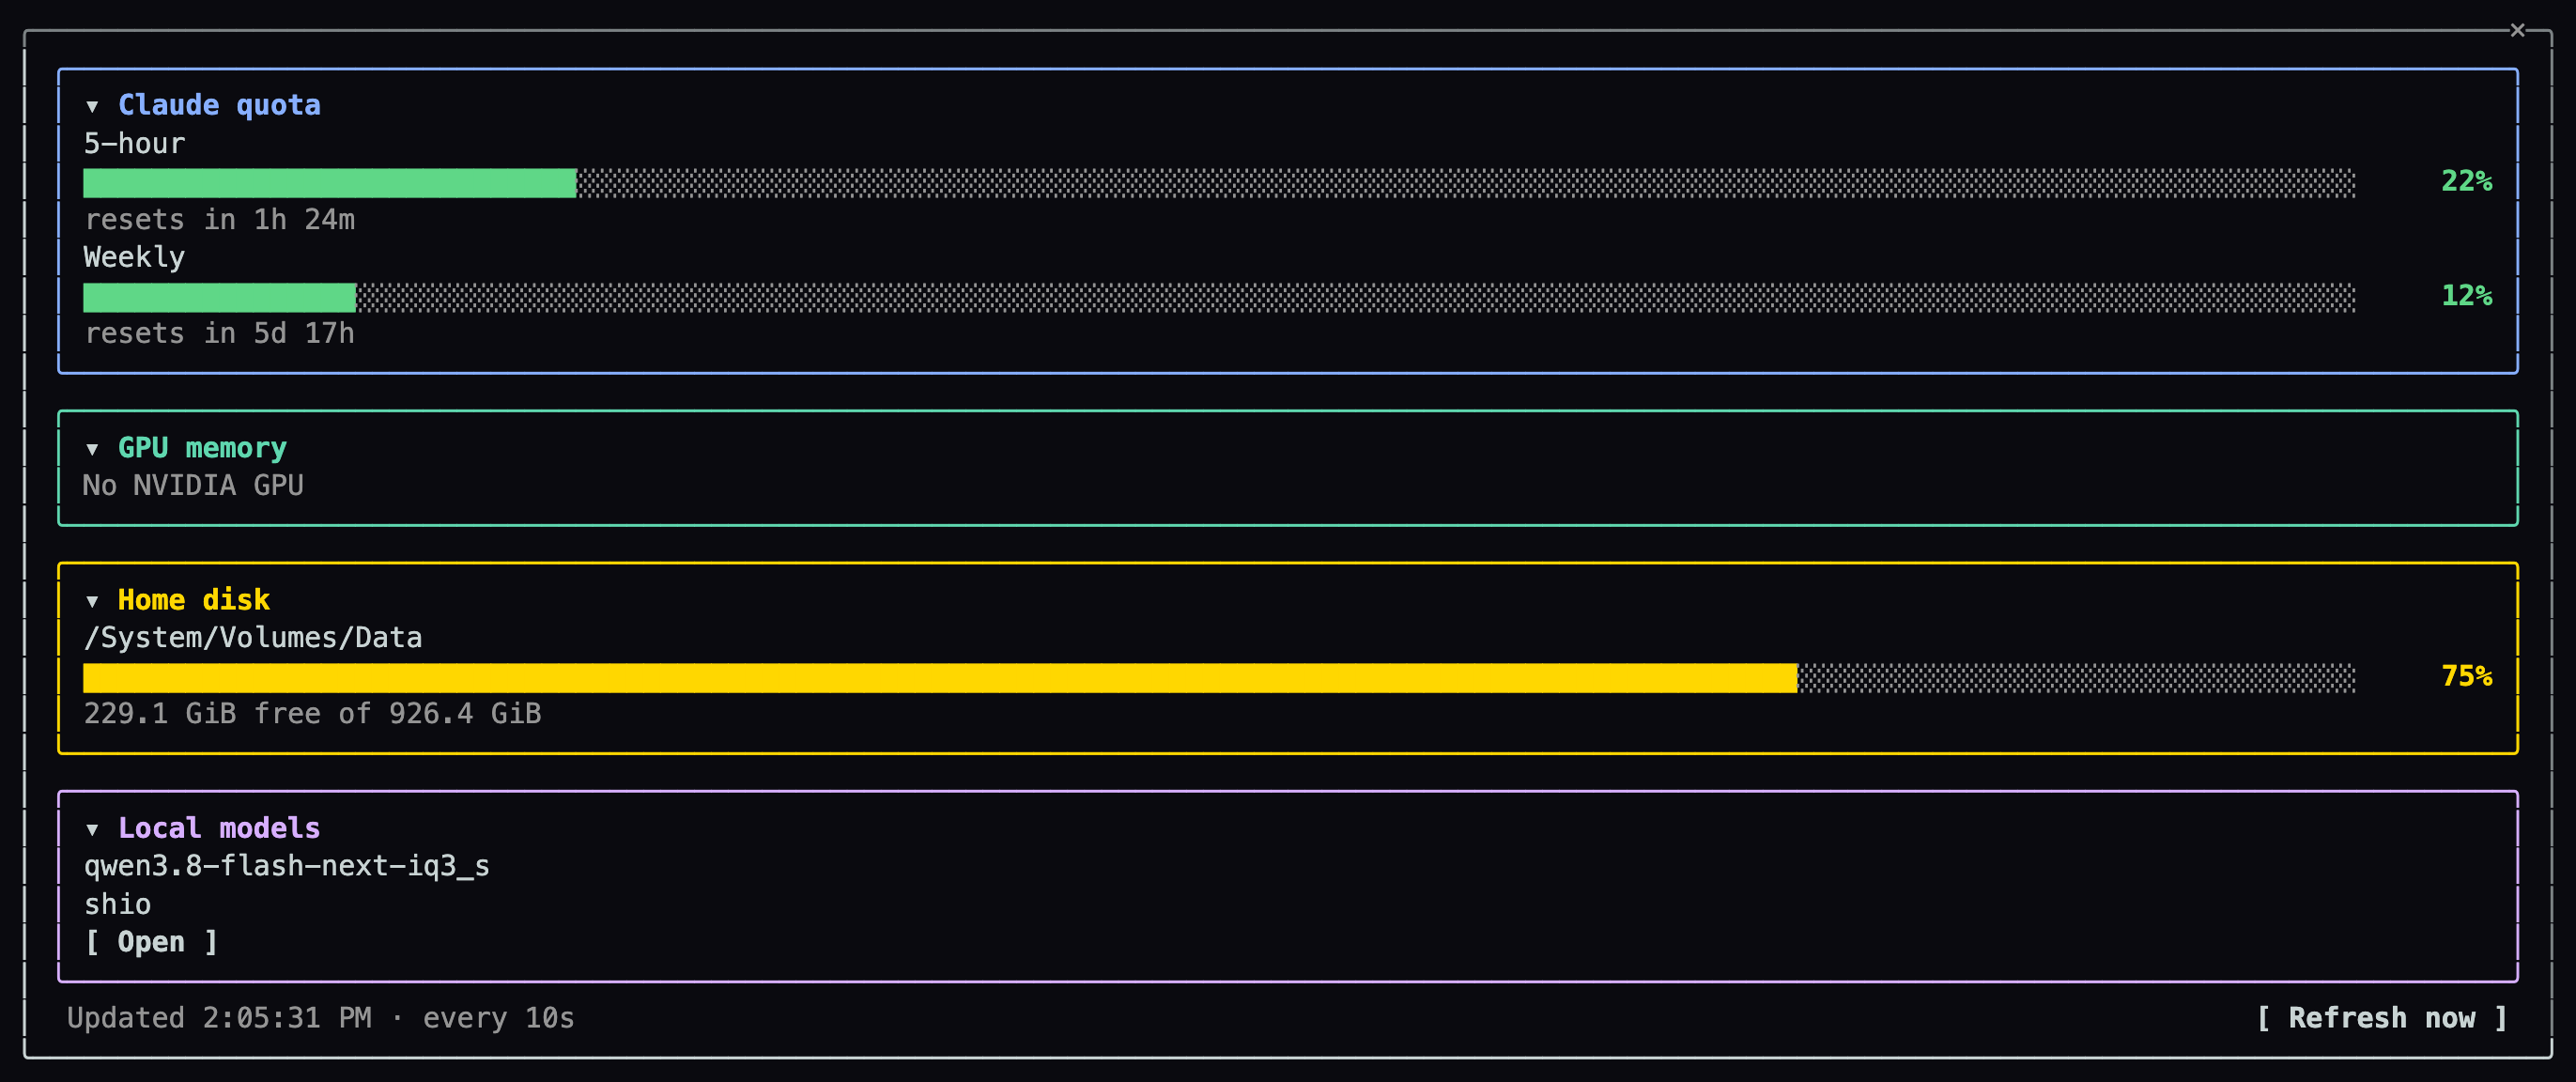
I'm not going to ask you to copy my code. It's wired to my machines and would be useless on yours. The prompts in this post get Claude to build the same kind of pane for your own machine. I ran each one in a fresh session (`claude -p`) to make sure every prompt stands on its own; you can just as well paste all six into one session.
## What a mod is, and why it has no sandbox
Think of a mod as an add-on for Claude Code: once it's loaded, your own panes and buttons show up right in the session. Claude writes all the code, so you don't need to know TypeScript. A mod can:
- open a pane with text, progress bars, and buttons
- give Claude a new tool it can call to look things up, the same way it runs commands
- look at each action Claude is about to take, and block it if needed
- add slash commands, such as `/my-dash`
Per the official docs, mods can also rewrite the prompts you send, intercept or retry tool calls, switch models per request, and change how Claude Code renders its own messages.
One caveat: a mod runs with the same permissions as Claude Code. There is no sandbox. It can read your environment variables and the entire conversation. It can also approve tools for you, burn through your subscription quota or run up charges on your API account, and start processes outside the Bash sandbox. Before installing someone else's mod, run `claude plugin validate` to see which events it hooks, which capabilities it calls, and which env vars it reads or writes. Then read the code: the official docs recommend installing mods only from authors and marketplaces you trust. The [docs](https://code.claude.com/docs/en/plugins/mods/overview) cover the full API.
## Before you start: version 2.1.287 or later and an empty folder
Check your version:
```bash
claude --version
```
Mine printed 2.1.289. Any version from 2.1.287 on works. If yours is older:
```bash
claude update
```
Then make an empty folder and start Claude Code in it:
```bash
mkdir ~/my-dash-work && cd ~/my-dash-work
claude
```
One note on the prompts: I wrote them in Chinese first. The English versions below are the ones I ran for this post. They're more detailed than they need to be, so that each step reproduces what I got. When you build your own, you don't have to copy them word for word. Say what you want and let Claude fill in the details; over-specifying tends to cause more mistakes, not fewer.
## Prompt 1: a GPU and disk pane in 2 min 51 s
```text
Build a Claude Code mod that opens a pane showing two things:
1. GPU memory usage. If the machine has an NVIDIA GPU, read it with nvidia-smi. Otherwise show "No NVIDIA GPU".
2. Free space on the disk that holds my home directory.
Draw a usage bar for each. Refresh every 10 seconds. Put the mod in ./my-dash/.
Run `claude plugin validate` and keep fixing until it passes.
When you're done, tell me how to load it.
```
Claude took 2 min 51 s and produced this:
```text
my-dash/
├── .claude-plugin/
│ └── plugin.json
├── hooks/
│ ├── hooks.json
│ └── register.tsx # the pane, the /my-dash command, 10 s refresh
├── types/
│ └── index.d.ts
└── tests/
└── dash.test.tsx
```
I didn't ask for tests. Claude wrote them anyway and tested them in both the terminal and the Desktop app. Claude Code's built-in mod-authoring instructions tell it to. When you change the mod later, run `claude plugin test`. It runs the mod's test files, which can fire real hooks and mount the pane on both surfaces; `validate` only checks statically. Neither verifies the visual layout, so open a live session for that.
Load the mod:
```bash
claude --plugin-dir ~/my-dash-work/my-dash
```
My MacBook has no NVIDIA GPU, so the pane showed "No NVIDIA GPU", plus about 235 GiB free of 926 GiB on the disk. If the pane doesn't open on its own, type `/my-dash`. Claude's summary says the pane auto-opens at launch only when the terminal is at least 144 columns wide.
## Prompt 2: a Claude quota card in 134 s
```text
Add a "Claude quota" card to the my-dash mod. Show 5-hour and weekly usage as percentages, plus the time until each resets. The mod can read the session's usage info.
Make every card title collapse or expand its card when clicked.
Run `claude plugin validate` until it passes.
```
The quota numbers come from the same usage data the status line uses. They show up only after you send your first message on a subscription account. Until then the card says "No quota reading yet", and on an API-key account it stays that way.
## Prompt 3: a local model card in 154 s
This one just asks Claude to connect to your local model server and refresh every 10 seconds.
```text
Add a "Local models" card to the my-dash mod. Every 10 seconds, poll http://localhost:8080/v1/models (an OpenAI-compatible API) and list the models it returns. If the server can't be reached, show "not running".
Put the URL in a constant at the top of the file.
Run `claude plugin validate` until it passes.
```
llama.cpp, vLLM, LM Studio, and Ollama all expose an OpenAI-compatible `/v1/models` endpoint, each on a different default port. Change the constant to match yours.
Claude only tested the card against a fake server. I had a model server on another machine forwarded to localhost:8080, and the mod picked up `qwen38-27b-ud` from it once loaded. It also handled cases I hadn't spelled out: a server that doesn't answer within 5 s counts as "not running", an error status shows up in red (for example "HTTP 500") so a broken server doesn't look like a stopped one, and an empty model list says "No models loaded".
## Prompt 4: a tool Claude can call in 131 s
The pane looks great now, and you can see every resource at a glance. Claude Code still can't. So the next prompt has Claude build a small tool it can call to see what's free before dispatching.
```text
Register a tool in the my-dash mod that Claude can call, named my_resources. It should return a very short summary of what's usable right now:
- Is the Claude quota OK?
- How much GPU and disk is left?
- Is the local model server up?
Run `claude plugin validate` until it passes.
Then tell me the tool's full name and how to make Claude check it before dispatching work.
```
Claude reports the tool's full name when it's done: `mcp__my-dash__my_resources`. That's the internal name Claude Code uses for the tool, always in the form `mcp____`, and it's the name you use when writing instructions for Claude. Here is a real call from a fresh session:
```text
Claude quota: OK (5-hour 52%, Weekly 7%)
GPU: none (no NVIDIA GPU on this machine)
Disk: 232.0 GiB free of 926.4 GiB
Local model server: UP (qwen38-27b-ud)
```
To make Claude use it, put one line in your project's `CLAUDE.md`, the instructions file Claude Code reads at the start of every session:
```text
Before dispatching work, call mcp__my-dash__my_resources; don't dispatch to anything it reports as unavailable.
```
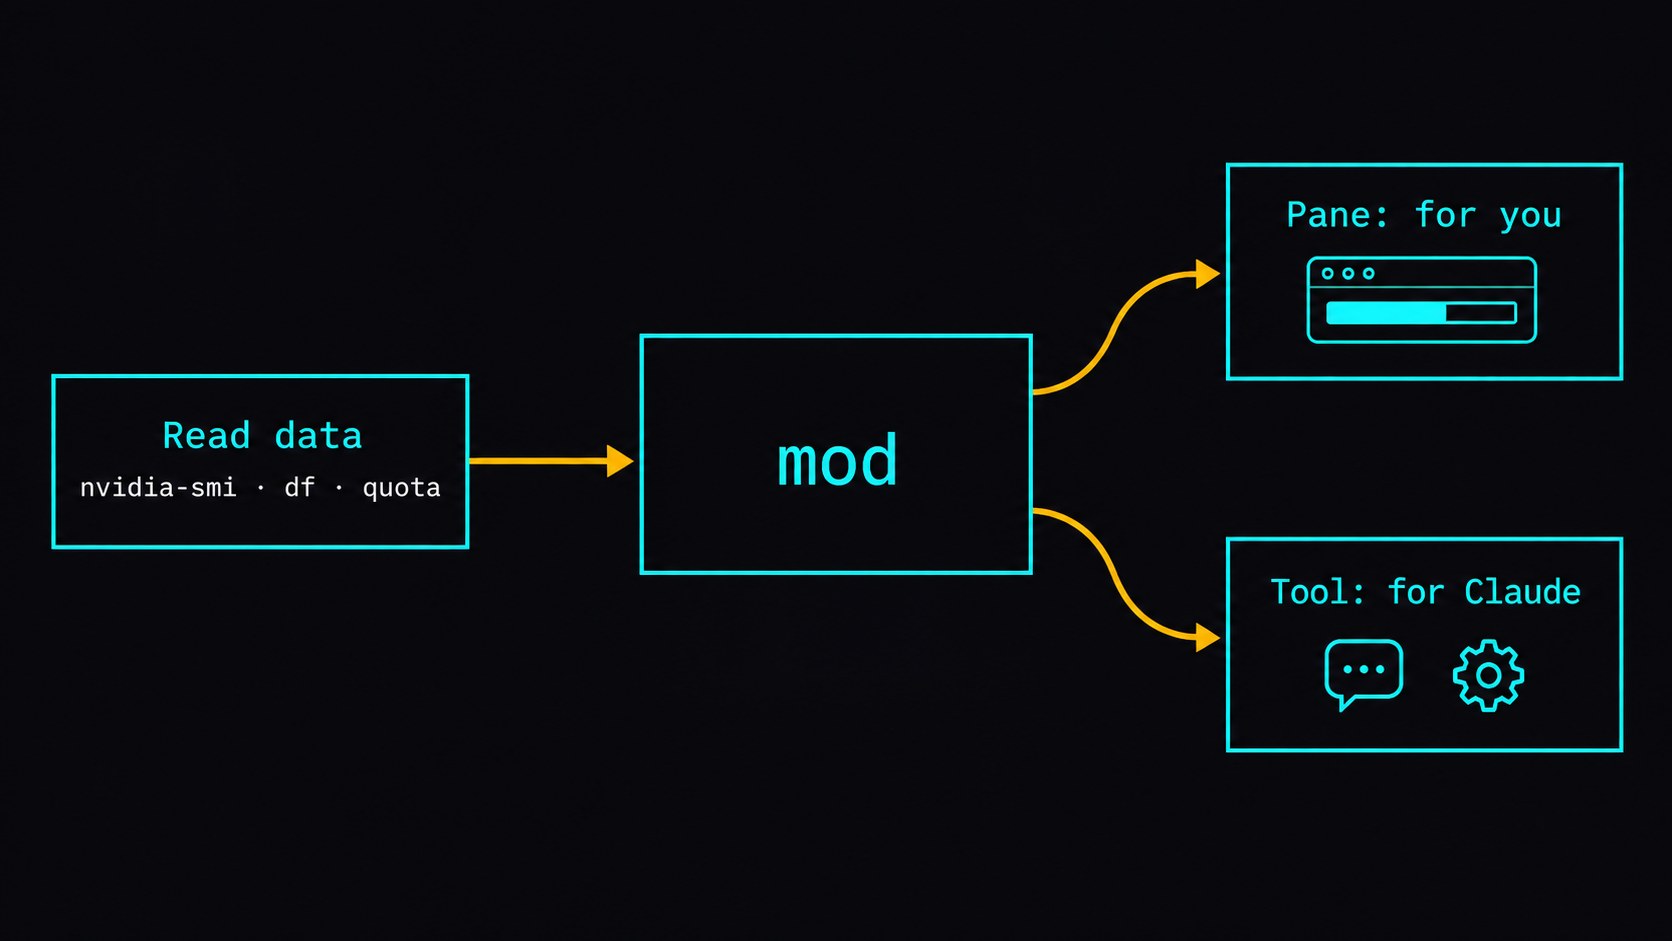
The tool only has to answer one question: can I dispatch here? No quota, don't dispatch. Machine busy, don't dispatch. Anything more detailed just burns tokens. My own tool started out stuffing every detail into Claude's context; I later cut it down to three short yes/no sections: quotas, local models, and the ComfyUI image server I also run.
## Prompt 5: a Pause dispatch button in 139 s
Why buttons at all? Mine do two jobs:
1. **Subscriptions**: show which model Claude dispatches to by default, and let me switch it by hand.
2. **Local services** (model servers, ComfyUI): when I'm using a machine to test a new model or tune settings, I need a flag that tells Claude to leave it alone.
This prompt builds the second one, plus a Refresh button:
```text
On the local-models card of the my-dash mod, add a "Pause dispatch" button. Clicking it creates a `paused` flag file under my-dash/ and shows "Paused" next to the card title; clicking again deletes the flag and goes back to normal. When the flag exists, the my_resources tool must report the local models as "paused, do not dispatch".
At the bottom of the pane, add a "Refresh now" button that re-reads all the data immediately.
Run `claude plugin validate` until it passes.
```
With the flag set, I asked Claude in a fresh session to call the tool, and the local-models line came back as paused, do not dispatch. A button runs an action on your machine, so instead of writing a flag it could just as well open a page or run a script.
## Prompt 6: SVG bars for the Desktop app in 172 s
The same mod renders in the Desktop app's Claude Code tab mostly unchanged. The one thing that breaks is text-based progress bars. In the terminal, every `█` takes exactly one cell. The Desktop app uses a proportional font, so the same row of characters comes out wider and covers the numbers next to it. I wrote this prompt after watching my own pane break that way.
```text
Make the my-dash mod look right in the Claude Desktop app. Desktop uses a proportional font, so text-character bars overflow and cover the numbers.
On Desktop, draw the bars as SVG. Leave the terminal version unchanged.
Run `claude plugin validate` until it passes.
```
Claude hit a snag here and fixed it on its own. It first checked whether the element table included `Svg`. In the test environment the terminal's table has one too, so the terminal tests broke. Claude switched to checking whether the surface is `terminal` instead. The official element table lists `Svg` as Desktop-only.
## Bonus prompt: make it look good in 224 s
After six prompts everything works, but every card is the same gray. This prompt is optional. Paste it if you want the pane from the top of this post:
```text
Make the my-dash pane look polished. Give each card a rounded border and its own title color: blue for quota, green for GPU, yellow for disk, purple for local models.
Color each usage bar by how full it is: green under 70%, yellow from 70 to 90%, red above 90%. Let the bars stretch with the pane width, and right-align the percentages.
Dim the last-updated line at the bottom.
Apply this in both the terminal and the Desktop app.
Run `claude plugin validate` until it passes.
```
The run took 224 s. `claude plugin validate` passed, and so did all 34 tests Claude wrote. In a 150-column terminal the bars stretched to fill each card with the percentages lined up on the right, as in the screenshot at the top of this post. I didn't check the Desktop version this time.
One change it made on its own: since Prompt 2 you collapse a card by clicking its title, but buttons can't have colored text. So Claude split the header: the collapse arrow became its own small button, with the colored title as plain text beside it. You now collapse a card by clicking the arrow.
If something looks off when you open it, describe what you see in plain words and paste that as the next prompt, for example: "The usage bars are too long and the last few cells wrap onto the next line. Keep each bar and its percentage on one line at any window width." When I ran the same test with Chinese prompts, the bars did wrap, and a follow-up like that fixed it in 81 s.
## Keep it loaded: one env var in settings.json
The easiest way is to tell Claude Code "make my-dash load automatically every time I start Claude Code" and let it edit the config for you. If you'd rather see what changes, or do it by hand, this is what goes into `~/.claude/settings.json`:
```json
{
"env": {
"CLAUDE_CODE_PLUGIN_DIRS": "/Users/you/my-dash-work/my-dash"
}
}
```
Separate several mods with colons. The Desktop app can't take `--plugin-dir`, so it relies on this env var too.
After a code change, an open terminal session picks it up as soon as you save. Desktop sessions don't watch the folder: open a new one, or add `"CLAUDE_CODE_PLUGIN_DIR_WATCH": "1"` to the same `env` block.
## Deep dive: what my own dashboard reads, and what broke while building it
You can skip this section; the guide above is complete without it. It covers the bugs I hit along the way.
### Seven things that broke
1. **CJK text misaligned.** I padded columns with `padEnd`, but a CJK character takes two cells. Fix: a fixed-width `Box` per column.
2. **`viewport.columns` is the width of the whole window, not the pane.** Fix: drop the explicit width and let flex fit the content. The pane then follows whatever width you drag it to. If you need the exact width, the docs recommend `e.props.bodyColumns`, the width of the pane's content area.
3. **`claude plugin validate` rejected three things.** Two unfiltered hooks on the same event (merge them into one). Functions that use `$` must be top-level. Atom state must be declared in the types file, or validate reports it as "is not declared".
4. **A shadowed `h` killed the whole pane.** In the machines card, `hosts.map(h => …)` shadowed the JSX `h`. Whenever a machine snapshot was present, the entire pane threw and rendered nothing. The tests passed because they never fed in a snapshot. I only found it in a real terminal.
5. **Character bars overflowed on Desktop.** Fix: choose by `e.surface`, and switch to SVG when the surface is not `terminal`.
6. **Three sessions edited one file.** One session made all card borders gray, a second kept editing on top of that, and the third switched them back to color. There is one `register.tsx` and the last save wins. Edit a mod from one session, and commit.
7. **Claude Code updated itself mid-build.** The mods API is marked early access, so an update can change it under you. Setting `autoUpdates: false` in `~/.claude.json` didn't stop an update from 2.1.288 to 2.1.289. Adding this to `settings.json` did:
```json
{
"env": {
"DISABLE_AUTOUPDATER": "1"
}
}
```
With that set, I update manually with `claude update`.
---
# Dual RTX 2080 Ti FastLLM: 16% Faster Decoding and No More Head-of-Line Blocking
URL: https://ai-muninn.com/en/blog/fastllm-dual-2080ti-concurrency-scheduler
Date: 2026-09-28
Series: 改裝 2080 Ti 22G (Part 21)
Same two modded 2080 Ti 22G, same Qwen3.8-27B FP8 + DFlash2 in FastLLM. Code goes from 100.3 to **116.1 tok/s**, math 118.6 → 135.5, prose 64.8 → 74.2. Two requests now run at once, 175.8 tok/s combined. A short request sent while a 54K-token prompt prefills gets its first token in **1.13 s** instead of 39.5 s (p95). How: latest upstream minus one commit that hurts draft acceptance, an NVFP4 draft, no `--tokens`, and a patch (PR #756) that yields between prefill chunks. Cost: per-request context drops from 262,144 to 222,080, and the patches aren't merged upstream yet, so you build it yourself.
## Same two cards: 16% faster, two requests at once, and no more 39-second waits
You're in a grocery store with one open checkout lane, holding a carton of milk, and the person ahead of you has a cart piled to the top. The cashier could ring you up in ten seconds between their items. They don't. You wait for the whole cart.
That was my model server. [Part 20](/en/blog/fastllm-dflash2-dual-2080ti) got Qwen3.8-27B FP8 running on two modded RTX 2080 Ti 22G with FastLLM and the DFlash2 draft model, tensor parallel 2, one request at a time. It was fast, but a single 54K-token prompt took about 40 seconds to prefill, and every other request sat behind it.
This part keeps the same cards and the same weights, and changes three things: a newer FastLLM with one commit reverted and a quantized draft (faster), one launch flag removed (two concurrent requests), and a scheduler patch (short requests get served during a long prefill). The first half is the recipe. The deep dive after the divider is the debugging record.
## What changed: code at 116.1 tok/s, 2 requests at once, 1.13 s instead of 39.5 s
Same machine, same benchmark script, measured before and after. The third row is the one that changes how the server feels in daily use.
| | previous build | this build |
|---|---:|---:|
| code / math / prose tok/s | 100.3 / 118.6 / 64.8 | 116.1 / 135.5 / 74.2 |
| concurrent requests | 1 | 2 (175.8 tok/s combined) |
| short request during a 54K-token prefill, first token (p95) | 39.5 s | 1.13 s |
| next request after cancelling a long one, first token (max) | 9.8 s | 0.54 s |
| per-request context limit | 262,144 | 222,080 |
On my 140-question capability set, the score went from 128 to 132 without thinking and from 125 to 127 with thinking at effort low. That comes with the caveats in the capability section below.
Method: real chat requests, temperature 0, 512 tokens per request, three prompts (code, math, prose), three runs each, median, timed on the client. The code prompt here asks for heavy comments and explanation, so its throughput comes out lower than on a pure-code prompt. With Part 20's three prompts, this build does 175.3 on code, 154.1 on math and 64.7 on prose. The latency rows come from a 33-minute stress test: 8 cycles, 112 requests, fixed seed.
## Change 1: newest FastLLM, one commit reverted, NVFP4 draft: code 100.3 → 116.6
The previous build was FastLLM at `14f849af` (2026-09-21). Upstream `a2bf07fd` (2026-09-25) is 87 commits newer. Dropped in as-is, it made math and prose faster and code about 15% slower.
Bisecting those 87 commits pointed at one: `d4b04876`, "修复小批量 RMSNorm 归约舍入差异" (fix rounding differences in the small-batch RMSNorm reduction). It changes the RMSNorm kernel for width 5120 and batch sizes 1 to 8. Both the main model and the DFlash2 draft have a hidden size of 5120. With that commit in, the draft's acceptance rate at position 3 drops from 60.9% to 43.5%. Fewer accepted guesses per step means fewer tokens per pass over the weights.
Reverting it restores code speed. The second step is quantizing the draft to NVFP4 with `FASTLLM_DRAFT_QUANT=nvfp4`, which upstream `7e0d6705` turned on by default. The draft is 5 layers and 3.6 GB, and it runs on every step, so smaller draft weights make the guessing phase shorter. The main model's weights aren't touched, and the main model still verifies every token, so answers don't change.
| build | code | math | prose |
|---|---:|---:|---:|
| previous (`14f849af`) | 100.3 | 118.6 | 64.8 |
| upstream `a2bf07fd`, draft unquantized | 84.8 | 126.9 | 68.1 |
| + revert `d4b04876` | 102.6 | 122.1 | 70.9 |
| + draft in NVFP4 | 116.6 | 135.8 | 74.7 |
`d4b04876` is upstream's consistency fix, and I don't think it computes anything wrong. I compared both kernels against an FP32 reference and they have the same error. I revert it only because, on this hardware with DFlash2, it lowers acceptance. On another GPU it may make no difference.
## Change 2: dropping --tokens makes --max_batch 2 real: 186 tok/s combined
Setting `--max_batch 2` alone still serves one request at a time. The only sign is one log line:
```
explicit-token safety max_batch limited 2 -> 1
```
Qwen3.8 is a hybrid model. Most of its layers use GDN, a linear-attention variant, and each request carries a sizable recurrent state on top of its KV cache. When you pass `--tokens` explicitly, FastLLM caps the budget for that state at 25% of the KV space. On these cards that fits one request, so FastLLM silently drops concurrency to 1. The 25% is hard-coded; there's no flag for it.
Remove `--tokens` and FastLLM sizes the KV pages itself. Concurrency works. Compare the "two at once" column:
| flags | actual concurrency | single request (code) | two at once | context per request |
|---|---:|---:|---:|---:|
| `--max_batch 2 --tokens 262144` | 1 (clamped) | 116.9 | ~117 (taking turns) | 262,144 |
| `--max_batch 2`, no `--tokens` | 2 | 116.7 | 186 combined | 222,080 |
Single-stream speed doesn't change, and combined throughput goes up about 60%. The cost is context: two requests share one KV pool, so each one gets 222,080 tokens instead of 262,144.
## Change 3: yielding between prefill chunks: a short request waits 1.18 s instead of 37.4 s
Two concurrent slots don't help if one of them is prefilling a long prompt. A 54K-token prompt takes about 40 s to prefill, and a short request sent during that time waited about 39 s.
With Qwen3.8 plus DFlash, FastLLM uses a dedicated scheduler loop. Once it picks the long request, it runs every prefill chunk in one inner loop and never looks at the queue. `--chunked_prefill_size` only sets how big each chunk is. I tried three chunk sizes and three related environment variables, and the short request always waited 37 to 41 s.
The fix: after each chunk, release the model's forward lock for a moment so a helper scheduler thread can serve queued short requests, then continue the prefill. It's behind a switch, `FASTLLM_COOPERATIVE_LONG_PREFILL=1`. With the variable unset, behavior is identical to upstream.
I fixed cancellation along the way. Upstream, cancelling a long request only marks it aborted. The prefill loop never checks the flag, so the GPU finishes the whole prompt and the next request waits 9.8 s. The loop now checks between chunks, and the next request is served in 0.5 s. Chunks that were already prefilled stay in the prefix cache, so resending the same prompt hits them.
All numbers below were measured while a 54K-token prompt was prefilling:
| | before | after |
|---|---:|---:|
| one short request inserted: first token / done (single run) | 37.4 s / 37.8 s | 1.18 s / 3.8 s |
| two short requests at once: first token | 38.1 / 38.6 s | 1.3 / 2.7 s |
| one short request, stress-test p95 first token | 39.5 s | 1.13 s |
| cancel, then next request's first token (stress max) | 9.8 s | 0.54 s |
| the long request's own prefill (stress p95) | 42.2 s | 42.7 s (+1%) |
A single short request finishes in 3.8 s. Two at once both start within 3 s, but they share the GPU with the prefill and generate slowly, 1 to 2 tokens/s, until the long prompt finishes. A third request waits for one of them, because the limit is 2.
The patches are two upstream PRs: [#755](https://github.com/ztxz16/fastllm/pull/755) aborts prefill on cancel (small, and useful to anyone running FastLLM), and [#756](https://github.com/ztxz16/fastllm/pull/756) is the scheduler change, stacked on #755. Neither is merged yet, so you have to build FastLLM yourself.
## Building it: a2bf07fd, one revert, two PR merges
The environment is the same as Part 20: two modded 2080 Ti 22G, an NCCL build with sm_75 (my self-built 2.31.2), CUDA 12.4 (`nvcc`), GCC 13 and a Python 3.14 venv. The model is [orcarouter/Qwen3.8-27B-Uncensored-FP8](https://huggingface.co/orcarouter/Qwen3.8-27B-Uncensored-FP8) and the draft is [z-lab/Qwen3.8-27B-DFlash2](https://huggingface.co/z-lab/Qwen3.8-27B-DFlash2).
Get the source. I checked that these merges apply cleanly on `a2bf07fd` and that the result compiles.
```bash
git clone https://github.com/ztxz16/fastllm && cd fastllm
git checkout -b dual-2080ti a2bf07fd
git revert --no-edit d4b04876 # the commit that lowers DFlash2 acceptance
git fetch origin pull/749/head:pr749 pull/756/head:pr756
git merge --no-edit pr749 # custom AllReduce registration cache grows without bound
git merge --no-edit pr756 # already contains #755
```
[#749](https://github.com/ztxz16/fastllm/pull/749) is a fix I sent upstream in September. DFlash2 on two GPUs allocates a pointer table on every step and never frees it, so long conversations eventually fill GPU0.
Build and install:
```bash
mkdir build-fastllm && cd build-fastllm
cmake .. -DUSE_CUDA=ON -DUSE_NUMAS=OFF -DCUDA_ARCH=75 -DCMAKE_CUDA_ARCHITECTURES=75 \
-DCMAKE_CUDA_COMPILER=/usr/bin/nvcc \
-DCMAKE_CUDA_FLAGS="-D_AMXTILEINTRIN_H_INCLUDED -D_AMXINT8INTRIN_H_INCLUDED -D_AMXBF16INTRIN_H_INCLUDED -D_AMXCOMPLEXINTRIN_H_INCLUDED"
make -j24 fastllm_tools
cd tools && ~/venvs/ftllm-dual/bin/pip install --no-deps --force-reinstall .
```
The `-D_AMX...` flags work around a CUDA 12.4 + GCC 13 problem; without them the AMX headers fail to compile. The result is the same `ftllm` package with the same `ftllm server` command.
## Launching it: --tokens removed, two env vars added, 222,080 tokens per session
```bash
export LD_PRELOAD=/home/coolthor/nccl-install/lib/libnccl.so.2 # NCCL with sm_75
export CUDA_VISIBLE_DEVICES=0,1
export FASTLLM_CUDA_GRAPH=0 # still required for DFlash2 on sm_75
export FASTLLM_DRAFT_QUANT=nvfp4 # default already; explicit for clarity
export FASTLLM_COOPERATIVE_LONG_PREFILL=1 # the PR #756 switch
~/venvs/ftllm-dual/bin/ftllm server \
-p /mnt/nvme1t/models/qwen38-27b-uncensored-fp8 --model_name qwen38-27b-ud \
--tp 2 --max_batch 2 --chunked_prefill_size 4096 \
--gpu_mem_ratio 0.95 --kv_cache_dtype fp4 \
--speculative_algorithm dflash \
--speculative_draft_model_path /mnt/nvme1t/models/dflash2-qwen38-zlab \
--speculative_num_draft_tokens 8 \
--prefix_cache true \
--chat_template /mnt/nvme1t/models/qwen-fastllm-low/chat_template.jinja \
--host 0.0.0.0 --port 8082
```
Compared with Part 20: `--tokens 262144` is gone, `--max_batch` is 2, `--chunked_prefill_size 4096` is new, and there are two new environment variables. The chat template is the one from Part 20, with reasoning effort defaulting to low.
After it starts, check the log. There should be no `max_batch limited` line, and there should be this one:
```
Model context window: 222080 tokens per session
```
## Four gotchas that silently cost speed or concurrency
1. **`--max_batch 2` with `--tokens` clamps to 1**, with only a log line to tell you. Drop `--tokens`.
2. **Upstream latest drops code from 102 to 85 tok/s on this hardware.** Revert `d4b04876`.
3. **CUDA Graph stays off.** Once the draft is NVFP4, the new version no longer crashes on the first request with the graph on, but it runs 11% slower. Keep `FASTLLM_CUDA_GRAPH=0`.
4. **`--chunked_prefill_size` does not let short requests in.** You need the #756 build and `FASTLLM_COOPERATIVE_LONG_PREFILL=1`.
## Capability: 132 of 140 without thinking, 127 with it
Same 140 questions as Part 20: GSM8K 50, MATH-500 30, MuSR 20, HumanEval+ 40. Focus on the total column.
| | GSM8K | MATH-500 | MuSR | HumanEval+ | total |
|---|---:|---:|---:|---:|---:|
| previous, no thinking | 49 | 29 | 15 | 35 | 128 |
| this build, no thinking | 50 | 30 | 16 | 36 | 132 |
| previous, thinking + effort low | 50 | 30 | 9 | 36 | 125 |
| this build, thinking + effort low | 49 | 30 | 12 | 36 | 127 |
The main model's weights didn't change, so I read this as "no worse"; the gains are within noise. These runs used the build before the scheduler patch went in. After adding it, a 20-question smoke test came back 20/20.
## So, can it go faster?
So far I've only touched code and scheduling. The main model's weights are still FP8, and generating each token still reads 29 GB. The 2080 Ti has no FP4 hardware, so does squeezing the main model down to 4 bits help at all? [Next part](/en/blog/fastllm-dual-2080ti-nvfp4-self-quant).
---
## Deep dive: bisecting 87 commits, why chunking never yields, and two regressions the stress test caught
You can skip this section without losing anything you need to run the setup. It's the full record: the bisect, the source reading behind the scheduler patch, and the stress-test failures that shaped the final version.
### Bisecting the code-speed regression down to d4b04876
At each bisect step I built an unmodified upstream revision, started it on a separate port, and ran the code prompt 3 times for a median. At or above 96 tok/s counted as good, at or below 89 as bad. Each step took about 10 minutes.
The endpoints matched my patched builds (100.3 and 84.8), so the regression had nothing to do with my patches.
| commit | note | code tok/s | verdict |
|---|---|---:|---|
| `14f849af` | previous base | 100.2 | good |
| `809d34b6` | SM75 decode tuning | 101.9 | good |
| `00276210` | DFlash draft buffers, CUDA Graph | 101.9 | good |
| `b2283cc7` | | 102.2 | good |
| `2dd79d9d` | | 102.2 | good |
| `90fc11e4` | removed DFlash experiment switches | 102.2 | good |
| `d4b04876` | RMSNorm reduction | 84.7 | bad |
| `6023b070` | | 84.7 | bad |
| `a2bf07fd` | current upstream | 84.7 | bad |
### Acceptance drops, but the kernel isn't wrong
Draft acceptance for the first three positions, before and after `d4b04876`: 87.2 / 74.4 / 60.9% became 83.9 / 61.2 / 43.5%. Reverting only that commit on `a2bf07fd` gives code 102.3, math 121.4, prose 70.3.
To check whether the new kernel is less accurate, I fed both kernels synthetic 8×5120 FP16 inputs at magnitudes 0.01, 0.5, 1, 10 and 100 and compared them against an FP32 reference. Both have a max absolute error of about 0.00195. At most 2 of 40,960 values differ between them, by at most 0.000488. I can't call that a bug, and I can't yet explain why it moves acceptance this much.
### The logprobs patch has zero effect on speed
My own build also carries [#752](https://github.com/ztxz16/fastllm/pull/752), which adds OpenAI-style logprobs to the API. I measured with and without it: 100.3 / 100.3 on the old base, 84.8 / 84.7 on the new one. When requests don't ask for logprobs, it costs nothing.
### CUDA Graph: the "deadlock" message is a symptom
With `FASTLLM_CUDA_GRAPH=1`, the new version crashed on the first request with `Resource deadlock avoided`. That reads like a lock problem. The real error comes earlier in the log: the first decode during graph replay reports `cudaErrorIllegalAddress (700)`. On the way out, the MTP thread calls `pthread_join` on itself, which is what produces the deadlock message. The thing to look for is the first CUDA error, not the lock.
With the draft in NVFP4, graph mode no longer crashes, but it measured code 105.9, math 120.2, prose 61.1, about 11% slower.
### Draft tokens and the SM75 switches: defaults win
4 and 6 draft tokens were both slower than 8. Anything above 8 is rejected by this draft checkpoint, whose block size is 8.
The README lists three switches relevant to SM75: `FASTLLM_DFLASH_ATTENTION`, `FASTLLM_TP_NATIVE_GREEDY` and the SM75 decode tuning. Turning each one off changed speed by less than 2%, so I kept the defaults.
### Concurrency took three tries
| config | single (code) | two at once | short request during long prefill |
|---|---:|---|---|
| `--max_batch 2 --tokens 262144` | 116.9 | ~58 each, taking turns | waits; log shows the clamp line |
| `--max_batch 2`, no `--tokens` | 116.7 | 93 each, 186 combined | still waits |
| + `--chunked_prefill_size 4096` | 116.2 | 186.6 combined | still waits (38.6 s) |
### Where it blocks in the source
For the Qwen3.5 model family with DFlash, FastLLM uses `Qwen35MTPLoop`. Once it picks the long request, it runs all the chunks inside the inner loop around lines 24327–24489 of `src/models/qwen3_5.cpp`, and releases the forward lock only near line 24715 (line numbers are at `a2bf07fd`). The short requests have already arrived and are registered as pending. The scheduler just never looks at them until the whole prefill is done.
### What I tried before patching: chunk sizes and env vars
Before patching, I tried every knob that looked related. Short-request first token and long-request prefill time:
| setting | short request first token | long prefill |
|---|---:|---:|
| baseline, chunk 4096 | 37.4 s | 40.2 s |
| `FASTLLM_ACTIVE_PREFILL_TOKEN_LIMIT=1024` | 37.7 s | 40.5 s |
| `FASTLLM_IDLE_PREFILL_BATCH_WAIT_US` / `QUIET_US` tweaks | 37.8–39.6 s | 40.7–42.4 s |
| chunk 1024 | 40.7 s | 43.6 s |
| chunk 2048 | 38.0 s | 40.9 s |
| chunk 8192 | 38.2 s | 41.1 s |
The source explains why none of them helped: `ACTIVE_PREFILL_TOKEN_LIMIT` only applies in the generic scheduler loop, and the `IDLE_PREFILL_*` variables are only read in a branch that isn't enabled in this configuration.
### Regression 1: faster short requests broke concurrent throughput
The first prototype got the short request's first token down to 1.26 s. Then a 75-minute A/B stress test (same seed, 18 cycles, 252 requests per arm) showed two concurrent generations dropping from 175.5 tok/s combined to 73.3, with one stream stuck around 41 tok/s in every cycle.
The cause was the test order. In the sequence, "two concurrent generations" runs right after "cancel a long request", and cancel didn't abort the prefill. In the original build, the short request after the cancel waited 9.8 s, by which point the cancelled prefill had finished on its own. The prototype served that request in 0.5 s while the main thread was still prefilling the cancelled request. So when the two concurrent generations started, one of them fought the zombie prefill for the GPU and the other waited.
That's where the cancel fix (#755) came from. Same test, three builds:
| metric | original | prototype | fixed |
|---|---:|---:|---:|
| short-insert first token, p95 | 39.7 s | 1.19 s | 1.18 s |
| next request after cancel, median | 9.8 s | 0.54 s | 0.54 s |
| two concurrent generations, combined | 175.5 | 73.3 | 175.7 |
| long prefill, p95 | 42.4 s | 43.1 s | 42.9 s |
| errors / wrong answers | 0 / 0 | 0 / 0 | 0 / 0 |
### Regression 2: only one short request got in
The fixed version let in only one short request, not two. The helper thread counted the paused long request as one of its own slots (same file, around lines 23570–23579), so `--max_batch 2` left it one slot. Skipping the paused request in that count moved two short requests' first tokens from 1.3 / 36.7 s to 1.3 / 2.7 s. The log now prints `Decode alive = 2` between every prefill chunk. Across three restarts, the second request came in at 2.58–2.66 s.
### Final 18-cycle regression run
Short-insert p95 1.20 s, post-cancel 0.65 s, two concurrent generations 170.5 tok/s combined, long prefill p95 +2.0%, 0 errors.
Peak VRAM was about 200 MiB higher than the fixed version. I ran the same binary with the switch off for 9 cycles, and it climbed at the same slope. So the increase comes from the newer upstream base, not the scheduler.
### Three rounds of code review before submitting
I ran the patch through Codex code review three times before opening the PRs.
Round 1 found a hang. The idle helper waited indefinitely, while the main thread signalled stop without holding the lock. The signal could land between "checked the flag" and "started waiting", and then `join()` waits forever. The same round found three more issues: after cancel deletes a context, the token-fetch functions re-lock but keep using the old pointer; the helper used the wrong long/short threshold (4096 instead of 2048); and nothing cleaned up if thread creation failed.
Round 2 caught problems in those fixes: the change made the main loop's idle wait wake every 10 ms too, and a thread-creation failure made the scheduler exit. Round 3 passed.
Targeted tests after the fixes: the helper stopped cleanly 50 of 50 times; cancelling while another request streams ran 30 rounds, 90 requests, without a problem; and requests of 2,049–4,096 tokens inserted during a long prefill are not taken over by the helper for their own prefill.
### Version pin
- Upstream base `a2bf07fd` (2026-09-25), with `d4b04876` reverted
- Merged: [#749](https://github.com/ztxz16/fastllm/pull/749), [#755](https://github.com/ztxz16/fastllm/pull/755), [#756](https://github.com/ztxz16/fastllm/pull/756)
- My own build also has [#751](https://github.com/ztxz16/fastllm/pull/751) (a multimodal prefix-cache fix) and [#752](https://github.com/ztxz16/fastllm/pull/752) (logprobs). #751 conflicts with `basellm.cpp` on `a2bf07fd` and has to be resolved by hand. It only matters when an image comes at the end of a long conversation.
- CUDA 12.4, GCC 13.4, sm_75, NCCL 2.31.2 self-built
### Limitations and next steps
- #755 and #756 aren't merged and may need rebasing.
- Every number here is from two 2080 Tis, TP=2, with DFlash2. The effect of `d4b04876` and the gain from the NVFP4 draft may be different on other GPUs.
- Two short requests inserted at once still generate slowly (1–2 tok/s) until the long prompt finishes. Fixing that would mean batching short-request decode with long-prompt prefill in the same step, which is a different change.
---
**Also in this series:**
- [#20 Two modded RTX 2080 Tis hit 153.8 tok/s on Qwen3.8-27B with FastLLM + DFlash2](/en/blog/fastllm-dflash2-dual-2080ti)
- [#19 Ternary Bonsai 2 27B on one 2080 Ti, where DFlash2 barely helps](/en/blog/ternary-bonsai-2-27b-one-2080ti)
- [#16 Fixing NCCL's stub-library error on two 2080 Tis](/en/blog/nccl-2080ti-stub-library-fix)
- [#14 Two modded 2080 Tis running Qwen3.8-27B with llama.cpp tensor parallel](/en/blog/qwen38-dual-2080ti-tensor-parallel)
---
# NVFP4 Without FP4 Hardware: Qwen3.8-27B on Two RTX 2080 Tis at 151.7 tok/s
URL: https://ai-muninn.com/en/blog/fastllm-dual-2080ti-nvfp4-self-quant
Date: 2026-09-28
Series: 改裝 2080 Ti 22G (Part 22)
I converted Qwen3.8-27B from BF16 to NVFP4 myself and serve it on two modded 2080 Ti 22G with FastLLM + DFlash2. Code went from **116.1 to 151.7 tok/s**, math 135.5 → 178.8, prose 74.2 → 101.9, and the server now takes 4 requests at once (297 tok/s combined). The 2080 Ti has no FP4 hardware. It still wins because generation is bound by reading weights, and NVFP4 cuts that read from 29 GB to 20 GB per token. orcarouter's official NVFP4 is slower than FP8 here. Cost: a 54K-token prompt prefills 25% slower. 140-question score: 131/128 vs 132/127.
## Same books, smaller editions: the model got faster by getting lighter
Movers bill by the trip, not by how many books you own. Put the same books in paperback and each box holds more pages, so the move takes fewer trips.
Text generation works the same way. Every token the model produces reads the whole set of weights out of VRAM once. With FP8 weights, Qwen3.8-27B reads 29 GB per token. With NVFP4 it reads 20 GB.
[Part 21](/en/blog/fastllm-dual-2080ti-concurrency-scheduler) left this machine running a self-built FastLLM with an FP8 model, two concurrent requests, and a scheduler that lets short requests cut in. The 2080 Ti is Turing and has no FP4 hardware, so I expected NVFP4 to be pointless on it. This part switches the main model to an NVFP4 checkpoint I converted myself from BF16, moves the KV cache to fp8, and raises concurrency to 4. Code went from 116.1 to 151.7 tok/s.
## Self-made NVFP4 on two 2080 Tis: code 116.1 → 151.7 tok/s, 4 requests at once
Same two cards (TP=2), the same self-built FastLLM as part 21, the same benchmark script. Method: real chat requests, temperature 0, 512 output tokens, code / math / prose prompts, 3 runs each, median. Read the first row for speed and the last for whether anything broke.
| | FP8 (part 21) | self-made NVFP4 |
|---|---:|---:|
| code / math / prose tok/s | 116.1 / 135.5 / 74.2 | **151.7 / 178.8 / 101.9** |
| concurrent requests | 2 | 4 (297 tok/s combined) |
| main model size | 29 GB | 20 GB |
| 54K-token prompt prefill | 40.5 s | 50.6 s |
| 140 questions (no thinking / thinking+low) | 132 / 127 | 131 / 128 |
With two requests at once, each stream went from about 88 to 107.8 tok/s. The per-request context limit went up from 222,080 to 257,920 tokens. When a short request arrives during a long prompt's prefill, its first token now takes 0.52 s instead of 1.18 s, and it finishes in 5.5 s (was 3.8 s). The 140 questions ran on the same NVFP4 model before the KV and concurrency changes.
Three changes produced this:
1. **Main model → NVFP4**, converted myself from BF16, following a format that had already proven fast on this card.
2. **KV cache fp4 → fp8.** The smaller weights freed enough VRAM, and fp8 KV is faster under concurrency.
3. **`--max_batch` 2 → 4.**
## Why NVFP4 helps without FP4 hardware: 29 GB → 20 GB read per token
Turing tensor cores do FP16, INT8 and INT4. They don't do FP4. FastLLM stores NVFP4 weights as they are, 4-bit in VRAM, and unpacks them to FP16 inside the kernel before the tensor cores touch them. The upstream README lists NVFP4 decode kernels tuned for SM75 (the 2080 Ti) for several matrices of width 5120, which is Qwen3.8-27B's hidden size.
So NVFP4 saves bytes read, not compute. That's the right thing to save here: generation is bottlenecked on reading weights, and the compute units sit mostly idle. Without speculative decoding, code went from 32.9 tok/s (FP8, 29 GB) to 45.1 tok/s (NVFP4, 20 GB), +37%.
DFlash2, the draft model from part 20, guesses several tokens ahead and lets the main model verify 8 positions per read of its weights. That multiplies whatever the base read speed is, so the gain carries over at a similar ratio: 116.1 → 151.7 on code.
## Three NVFP4 checkpoints, more than 2× apart: 65.3, 136.0 and 149.9 tok/s on code
"NVFP4" on a model card doesn't tell you which layers are NVFP4. I tried three checkpoints under the same FastLLM and the same launch flags (KV fp4, `--max_batch 2`). Look at the code column and the last column together.
| checkpoint | what's NVFP4 | code / math / prose | no-spec code | 140 q |
|---|---|---:|---:|---:|
| FP8 (part 21) | none; linear layers FP8 | 116.6 / 135.8 / 74.6 | 32.9 | 132 / 127 |
| [orcarouter official NVFP4](https://huggingface.co/orcarouter/Qwen3.8-27B-Uncensored-NVFP4) | some MLP, rest FP8 | 65.3 / 77.9 / 43.6 | 32.4 | not tested |
| [lyf Heretic-ARA NVFP4](https://huggingface.co/lyf/Qwen3.8-27B-Heretic-ARA-NVFP4-MTP-VL) | all linear layers | 136.0 / 185.5 / 102.1 | 45.3 | 124 / 129 |
| self-made orcarouter NVFP4 | all linear layers | 149.9 / 178.0 / 104.3 | 45.1 | 131 / 128 |
**orcarouter's official NVFP4** comes from the same publisher as the uncensored FP8 I was already running, but it's mixed precision: the config lists 168 NVFP4 targets (MLP) and 232 FP8 targets. Without speculation it runs 32.4, about the same as FP8. With DFlash2 it drops to 65.3 on code, slower than the FP8 checkpoint. The draft isn't the problem: its acceptance is actually higher than with FP8. My guess, not separately verified: the per-channel FP8 weights take a slower path when the main model verifies 9 tokens at once.
**lyf's checkpoint** was converted with NVIDIA ModelOpt, every linear layer in NVFP4, and it's fast. But it's built on a different uncensored base (Heretic ARA), and its 140-question score without thinking drops to 124, mostly on MuSR and HumanEval+.
**The self-made one** takes orcarouter's BF16 original and converts it into lyf's format. It uses the same base model as my FP8 build, nearly matches lyf on speed, and scores about the same as FP8.
It's also a bit faster than lyf on code. Draft acceptance at positions 1–3 is 88.8 / 73.4 / 55.0%, against lyf's 82.8 / 64.3 / 52.4%. My guess: orcarouter's uncensoring is lighter, so the output stays closer to stock Qwen3.8, which is what the DFlash2 draft was trained on.
## Convert BF16 to NVFP4 yourself: one numpy script, no GPU, no calibration
The converted weights are on Hugging Face: [coolthor/Qwen3.8-27B-Uncensored-NVFP4-FastLLM](https://huggingface.co/coolthor/Qwen3.8-27B-Uncensored-NVFP4-FastLLM). To convert them yourself, you need three things:
- The BF16 original, [orcarouter/Qwen3.8-27B-Uncensored](https://huggingface.co/orcarouter/Qwen3.8-27B-Uncensored), about 56 GB. It's gated: accept the terms on Hugging Face first.
- The json and yaml files from lyf's repo, without the weights. The converter copies its tensor naming, shard layout and `quantization_config`.
- The converter, [/tools/qwen38-nvfp4-convert.py](/tools/qwen38-nvfp4-convert.py). It only needs numpy.
```bash
hf download orcarouter/Qwen3.8-27B-Uncensored --local-dir /mnt/nvme1t/models/orcarouter-qwen38-uncensored-bf16
hf download lyf/Qwen3.8-27B-Heretic-ARA-NVFP4-MTP-VL --include "*.json" "recipe.yaml" --local-dir ./nvfp4-ref
curl -O https://ai-muninn.com/tools/qwen38-nvfp4-convert.py
python3 qwen38-nvfp4-convert.py \
/mnt/nvme1t/models/orcarouter-qwen38-uncensored-bf16 \
/mnt/nvme1t/models/orcarouter-qwen38-uncensored-nvfp4-self \
--reference ./nvfp4-ref
```
The output is 20 GB in three shards. What the script does:
- **Every linear layer → NVFP4.** Values are packed as 4-bit E2M1, with one FP8 E4M3 scale per 16 values and one FP32 global scale per tensor.
- **Three groups share one global scale:** attention q/k/v, the four GDN input projections (`in_proj_qkv` / `z` / `a` / `b`), and MLP gate/up. I only found this by comparing against lyf's weights. Computing each tensor's scale separately gives the right format with mismatched values.
- **Kept in BF16:** `lm_head`, `embed_tokens`, the vision tower, conv1d, and MTP.
- **No calibration.** ModelOpt also calibrates activation scales (`input_global_scale`) for W4A4. FastLLM on a 2080 Ti uses FP16 activations and never reads that field, so the script writes 1.0.
To check it, I decoded lyf's NVFP4 back to BF16 and re-quantized it with the script. For one attention layer, one GDN layer and one MLP layer, the packed weights, block scales and global scales were all bit-identical to lyf's. All 2,687 tensors in the output match lyf's in name, dtype, shape and shard.
## Launch with KV fp8 and `--max_batch 4`, same FastLLM build
No rebuild. This is the production launch:
```bash
export LD_PRELOAD=/home/coolthor/nccl-install/lib/libnccl.so.2
export CUDA_VISIBLE_DEVICES=0,1
export FASTLLM_CUDA_GRAPH=0
export FASTLLM_DRAFT_QUANT=nvfp4
export FASTLLM_COOPERATIVE_LONG_PREFILL=1
~/venvs/ftllm-dual/bin/ftllm server \
-p /mnt/nvme1t/models/orcarouter-qwen38-uncensored-nvfp4-self --model_name qwen38-27b-ud \
--tp 2 --max_batch 4 --chunked_prefill_size 4096 \
--gpu_mem_ratio 0.95 --kv_cache_dtype fp8_e4m3 \
--speculative_algorithm dflash \
--speculative_draft_model_path /mnt/nvme1t/models/dflash2-qwen38-zlab \
--speculative_num_draft_tokens 8 \
--prefix_cache true \
--chat_template /mnt/nvme1t/models/qwen-fastllm-low/chat_template.jinja \
--host 0.0.0.0 --port 8082
```
Leave out `--tokens`; with it, FastLLM clamps concurrency to 1 (part 21 explains why).
## KV fp8 and 4 streams: 293 tok/s combined, single stream still ~150
The weights got 9 GB smaller, which frees about 3 GB per card for the KV cache. I compared fp4 and fp8 KV at `--max_batch 2`, then raised concurrency with fp8. The single-stream column barely moves; watch the total.
| KV / streams | single code / math / prose | per stream | total | KV pool (tokens) |
|---|---:|---:|---:|---:|
| fp4 / 2 | 149.8 / 178.3 / 104.0 | 99.9 | 199.8 | 564,480 |
| fp8 / 2 | 151.0 / 178.3 / 101.5 | 108.3 | 216.6 | 321,152 |
| fp8 / 3 | 150.5 / 178.2 / 101.4 | 81.0 | 243.1 | 302,976 |
| fp8 / 4 | 150.6 / 178.3 / 101.5 | 73.4 | 293.4 | 257,920 |
fp8 KV is faster than fp4 once there's concurrency: two streams went from 99.9 to 108.3 each. My read is that fp4 KV has to be unpacked on every read, and that shows up when there's more KV to read.
The KV pool shrank from 564K to 258K tokens. The per-request limit, 257,920, is still above the FP8 build's 222,080.
After switching production over, I re-measured on the live service: single stream 151.7 / 178.8 / 101.9, two at once 107.8 each, four at once 74.3 each.
## The cost: a 54K-token prompt prefills in 50.6 s instead of 40.5 s
Long prompts prefill 25% slower. Prefill processes thousands of tokens at once, so it's bound by compute rather than weight reads, and unpacking NVFP4 before the math is pure extra work when compute is the limit. Repeated prefixes still hit the prefix cache: sending the same 8K prefix a second time takes 1.8 s.
So this build suits mostly-short prompts with several concurrent users, like agents messaging each other. If you mostly feed it new documents of tens of thousands of tokens, the FP8 build is faster.
## Capability: 131 / 128 on 140 questions, against 132 / 127 for FP8
Same 140 questions as before: GSM8K 50, MATH-500 30, MuSR 20, HumanEval+ 40. Compare the FP8 and self-made rows.
| | GSM8K | MATH-500 | MuSR | HumanEval+ | total |
|---|---:|---:|---:|---:|---:|
| FP8, no thinking | 50 | 30 | 16 | 36 | 132 |
| self NVFP4, no thinking | 50 | 29 | 17 | 35 | 131 |
| FP8, thinking + low | 49 | 30 | 12 | 36 | 127 |
| self NVFP4, thinking + low | 50 | 30 | 12 | 36 | 128 |
On the same base model, going from FP8 to NVFP4 moved the score by one question in each mode, which is within noise. lyf's checkpoint scored 124 without thinking and 129 with thinking at low effort (full rows in the deep dive). Its −8 without thinking can't be split between quantization and the change of base model.
---
## Deep dive: the shared global scale, bit-exact checks, the DFlash re-sweep and two 4-bit dead ends
You can skip this section without losing anything you need to run the setup. It holds the full data behind each claim above.
### The shared global scale: 128 groups, and `in_proj_a` is the one that bites
The first version of the converter computed a global scale per tensor. The format and shapes were right, but the values didn't match lyf's. ModelOpt shares one global scale across a group of tensors, taken from the group's max absolute value:
- attention q/k/v: 16 layers → 16 groups
- GDN `in_proj_qkv` / `z` / `a` / `b`: 48 layers → 48 groups
- MLP gate/up: 64 layers → 64 groups
That's 128 groups. `in_proj_a` is the easiest to miss. Its own max is small, so computing its scale alone misses the larger values in the other three projections. Switching to per-group scales made the output bit-exact.
### Bit-exact check against lyf's ModelOpt output
Method: decode lyf's NVFP4 weights to BF16, keeping FP4 negative zero, then re-quantize with the script and compare byte for byte.
| layer | packed weights | block scales | global scale |
|---|---:|---:|---:|
| Attention, layer 11 `self_attn.q_proj` | 31,457,280 / 31,457,280 bytes | 3,932,160 / 3,932,160 | 4 / 4 |
| GDN, layer 0 `linear_attn.out_proj` | 15,728,640 / 15,728,640 | 1,966,080 / 1,966,080 | 4 / 4 |
| MLP, layer 0 `mlp.gate_proj` | 44,564,480 / 44,564,480 | 5,570,560 / 5,570,560 | 4 / 4 |
For `in_proj_qkv`, re-estimating the global scale from the decoded BF16 can be off by 1 ULP, while the packed weights and block scales stay bit-identical. The decoded values can't fully recover the original BF16 extremes, so this is expected. I also re-quantized from the original BF16 for `in_proj_a`, `q_proj` and `gate_proj` in the final output: all three tensor kinds were bit-identical.
### DFlash re-sweep on lyf's checkpoint: 8 draft tokens with NVFP4 draft quantization is still best
A faster main model could shift the best draft settings, so I re-swept on lyf's checkpoint.
| draft tokens / draft quant | code / math / prose | acceptance, positions 1–3 |
|---|---:|---:|
| 8 / nvfp4 | 136.0 / 185.6 / 102.5 | 80.8 / 59.1 / 44.7% |
| 8 / nvfp4_head | 118.6 / 174.4 / 94.8 | 84.5 / 63.2 / 46.8% |
| 8 / off | 123.8 / 162.6 / 92.5 | 83.6 / 65.6 / 50.4% |
| 6 / nvfp4 | 129.6 / 156.4 / 97.2 | 82.7 / 64.8 / 48.5% |
| 4 / nvfp4 | 113.2 / 124.7 / 97.3 | 85.4 / 68.1 / 51.2% |
Quantizing less of the draft raises acceptance but slows the draft down more than that gains. `nvfp4_head` (only the draft's output head quantized) is slower than no quantization at all; I didn't investigate why. Fewer draft tokens raise per-position acceptance but produce fewer tokens per step, and math takes the biggest hit. The checkpoint rejects values above 8.
### KV and concurrency detail: acceptance, prefill and short-request latency per setting
| KV / streams | acceptance, positions 1–3 | 54K prompt prefill | short-request first token |
|---|---:|---:|---:|
| fp4 / 2 | 81.9 / 63.1 / 47.8% | 49.9 s | 0.53 s |
| fp8 / 2 | 79.3 / 61.4 / 50.1% | 50.5 s | 0.47 s |
| fp8 / 3 | 80.3 / 62.8 / 51.7% | 50.6 s | 0.51 s |
| fp8 / 4 | 80.3 / 62.9 / 52.5% | 50.6 s | 0.53 s |
All four settings answered the 54K request correctly. The per-request limit stays at 262,144 for fp8/2 and fp8/3 and drops to 257,920 at fp8/4.
### orcarouter's official NVFP4: loads fine, runs NVFP4 kernels, and is still slow
`config.json` has two quantization groups: 168 NVFP4 W4A4 targets (the MLP of the first 56 layers) and 232 FP8 W8A8 targets (attention q/k/v/o, GDN `in_proj_qkv` / `in_proj_z` / `out_proj`, and the last 8 layers' MLP); `lm_head` stays BF16. It loads without errors, the log shows NVFP4 prefill and decode kernels, it answers 17*23 = 391, and an image test comes back correct. It's just slow.
| checkpoint | code / math / prose | no-spec code | EN acceptance, positions 1–3 | KV pool (tokens) |
|---|---:|---:|---:|---:|
| FP8 | 116.6 / 135.8 / 74.6 | 32.9 | 82.7 / 67.3 / 52.1% | 222,080 |
| official NVFP4 | 65.3 / 77.9 / 43.6 | 32.4 | 86.3 / 68.3 / 55.5% | 447,104 |
| self NVFP4 | 149.9 / 178.0 / 104.3 | 45.1 | 88.8 / 73.4 / 55.0% | 564,480 |
Acceptance is higher than FP8 and no-spec speed matches FP8. It only falls behind when verifying several tokens at once.
### Two 4-bit dead ends with FastLLM's own INT4
I also tried FastLLM's native INT4 format (`int4g`, groups of 128).
**TP=2 has no INT4 matmul kernel.** The model loads fine, 12 GB per card. On the first request, GPU utilization sits at 0% while CPU runs at 110%, and 16 tokens hadn't finished after 120 s. `FastllmCudaMatMulFloatInt4Group` exists only in the single-GPU `cudadevice.cpp`, not in `multicudadevice.cpp`, so tensor parallel silently falls back to CPU. The hung process ignores SIGTERM and needs `kill -9`.
**Single-card INT4 is slow.** Without speculation it runs 20.2 tok/s, which, at roughly 15 GB of weights on one card, works out to about 300 GB/s, half the 2080 Ti's bandwidth, so the unpacking is too expensive. Single card plus DFlash2 crashes with `Resource deadlock avoided`.
### `--dtype fp8_e4m3` doesn't convert a BF16 checkpoint
Passing `--dtype fp8_e4m3` with a BF16 checkpoint doesn't produce FP8. FastLLM silently loads FP16 instead. For FP8 or NVFP4, convert offline first.
### Pinned versions
- FastLLM: upstream `a2bf07fd` + revert of `d4b04876` + PR #749 + PR #756 (same as part 21)
- Main model: orcarouter/Qwen3.8-27B-Uncensored BF16 → self-made NVFP4, `total_size` 20,558,935,392 bytes
- Draft: z-lab/Qwen3.8-27B-DFlash2, quantized to NVFP4 at runtime (`FASTLLM_DRAFT_QUANT=nvfp4`)
- CUDA 12.4, sm_75, self-built NCCL 2.31.2
### Limitations and next steps
- KV fp8 and 4 streams were set after the 140-question runs. I haven't re-run capability with them.
- The converter is only verified on Qwen3.8-27B's architecture.
- The 25% slower long-prompt prefill has no fix. It would take work on FastLLM's NVFP4 prefill kernel.
---
**Also in this series:**
- [#21 FastLLM on two 2080 Tis: two concurrent requests and a scheduler that lets short requests in](/en/blog/fastllm-dual-2080ti-concurrency-scheduler)
- [#20 Two modded RTX 2080 Tis hit 153.8 tok/s on Qwen3.8-27B with FastLLM + DFlash2](/en/blog/fastllm-dflash2-dual-2080ti)
- [#16 Fixing NCCL's stub-library error on two 2080 Tis](/en/blog/nccl-2080ti-stub-library-fix)
---
# [DGX Spark] Qwen3.8-Flash-Next on two DGX Sparks: 51.9 to 72.0 tok/s, and a draft vocabulary built from my own text
URL: https://ai-muninn.com/en/blog/qwen38-flash-next-two-sparks-checkpoint
Date: 2026-09-28
Series: DGX Spark (Part 49)
Qwen3.8-Flash-Next NVFP4 on two DGX Sparks (TP=2) went from **51.9 to 72.0 tok/s** on the 40 prompts from Part 46; the harness score rose from 0.843 to 0.876. The biggest gain came from adding my own frequently used Chinese to the MTP draft vocabulary. The stock list was built from English and code, so 82% of the Chinese tokens I sampled could never be proposed. After adding 5,606 tokens from my own text, a prompt on a topic I work on daily got 60% faster (acceptance 0.11 → 0.98 tokens per step) and everyday topics outside that corpus got 23–27% faster, from a one-line mount change. Turn-two TTFT on a 9.5k prefix fell from 3.30 s to 0.23 s. Caveat: the KV pool is 69% smaller, from a memory setting lowered after an OOM.
## Preface
If you weigh yourself, you use the same scale every time, first thing in the morning, before coffee. A new scale at a different hour tells you nothing about whether you changed.
This is Part 49 of the DGX Spark series and a checkpoint against [Part 46](/en/blog/qwen38-flash-next-tp2-two-dgx-sparks), published 2026-09-12. Sixteen days later I re-ran the same harness and the same probe on the same two machines. The first half of this post is what changed and how to reproduce it. The second half is debugging notes.
## 51.9 → 72.0 tok/s on the same 40 prompts, score up from 0.843 to 0.876
The setup: Qwen3.8-Flash-Next NVFP4 on two NVIDIA DGX Spark (GB10) boxes, vLLM with tensor parallel TP=2 plus expert parallel, using the MiaAI dual-Spark derivative vLLM image. Every number is a median of 3 runs.
The first row is the headline; the probe rows break the gain down by content type.
| Metric | Part 46 (Sep 12) | Now (Sep 28) | Change |
|---|---|---|---|
| 40-prompt harness, median decode | 51.9 tok/s | 72.0 tok/s | +38.7% |
| Harness auto-score | 0.843 | 0.876 | +0.033 |
| Probe: code | 61.79 tok/s | 86.82 tok/s | +40.5% |
| Probe: English prose | 37.87 tok/s | 44.99 tok/s | +18.8% |
| Probe: Traditional Chinese prose | 33.16 tok/s | 45.89 tok/s | +38.4% |
The individual harness runs were 56.6 / 51.7 / 51.9 in Part 46 and 77.9 / 71.2 / 72.0 now. Both sets varied by about 9% run to run. All 8 harness categories got faster: coding went from 58.1 to 82.9, and prose, the slowest category, from 38.0 to 48.6.
The auto-score comes from a grader that executes the generated Python for coding prompts. The prose category score moved from 0.4 to 0.6 and the rest stayed mostly flat (per-run: 0.855 / 0.880 / 0.876). This is not a full quality evaluation. It does show that nothing got worse.
## Five changes in 16 days, and one of them made Chinese slower
Five changes landed between the two measurements:
1. **Sep 22: switched to the MiaAI dual-Spark vLLM build.** The old stack had zero prefix-cache hits across requests.
2. **Sep 22: adaptive MTP with 4 draft slots and a 47,149-token draft vocabulary.** MiaAI had measured a speedup with it, and code did benefit.
3. **Sep 24: `gpu-memory-utilization` from 0.835 to 0.68.** An earlyoom cascade took the service down for 17 minutes. At 0.78 the head node's available memory still dropped to 1.8 GiB.
4. **Sep 28: prefix-cache alignment fix, plus GDN weights read as FP8.**
5. **Sep 28: Chinese tokens added to the draft vocabulary.**
The intermediate rounds used a different probe at different times, so they only show a trend. For Chinese the trend was down: the Chinese probe fell from 33.16 tok/s at Part 46 to 27.6 on the evening of Sep 27, and nobody noticed. The cause was change 2, the Sep 22 draft vocabulary.
## Chinese was slow because 82% of its tokens were not on the draft list
MTP (multi-token prediction: a small head built into the model guesses the next few tokens each step) works like this. The draft head proposes up to 4 tokens. The target model reads its weights once, verifies every proposed position in that single pass, and keeps the guesses that match. Machines that are bound by memory bandwidth gain the most, because a weight read costs the same whether it verifies one position or five.
The MiaAI recipe makes each draft step cheaper by shrinking the draft head's proposal set. The tokenizer has 248,077 ids; the recipe limits proposals to a 47,149-token list in `draft_vocab_en_code_47k.txt`. As the name says, that list was built from English and code.
I measured accepted draft tokens per step by language:
| Content | Accepted tokens per step | First-slot hit rate |
|---|---|---|
| Code | 3.154 | 97.4% |
| English | 1.226 | 59.4% |
| Chinese | 0.114 | 11.4% |
On four Chinese paragraphs (Traditional and Simplified: a technical explanation, operating steps, a product reply, a tutorial), 82.26% of the tokens were not on the list. The draft head cannot propose a token it is not allowed to see, so for Chinese the target model was back to emitting about one token per step, while still paying for the draft.
## Build the draft vocabulary from your own text: two commands and one bind mount
The fix uses a tool that already ships in the MiaAI repo: [`files/build_draft_vocab.py`](https://github.com/MiaAI-Lab/Qwen3.8-Flash-Next-Dual-DGX-Sparks/blob/main/files/build_draft_vocab.py). It reads a corpus, counts tokens, and writes an id list. I built a Chinese list and took the union with the existing one, so no English or code token is lost.
The corpus is the point: use text you actually work with. Mine was Chinese documentation already on the machine, three model-written Chinese passages on topics I routinely ask about, and Simplified Chinese versions of all of it: 174,490 tokens. If your server keeps logs, real prompts and responses will match your workload even better. Run the script inside the serving container so it uses the same tokenizer the server does.
```bash
docker cp zh_corpus_both.txt vllm_qwen38fn_miaai:/tmp/
docker cp build_draft_vocab.py vllm_qwen38fn_miaai:/tmp/
docker exec vllm_qwen38fn_miaai python3 /tmp/build_draft_vocab.py /tmp/zh_corpus_both.txt --out /tmp/zh_candidates_both.txt --size 65536
```
Then merge the new candidates into the existing list:
```bash
docker exec vllm_qwen38fn_miaai python3 -c "a={int(x) for x in open('/etc/vllm-draft-vocab.txt')}; b={int(x) for x in open('/tmp/zh_candidates_both.txt')}; open('/tmp/draft_vocab_en_code_zh_both.txt','w').writelines(f'{x}\n' for x in sorted(a|b)); print(len(a), len(b), len(b-a), len(a|b))"
```
Output:
```
47149 9749 5606 52755
```
The old list had 47,149 ids and the Chinese candidates had 9,749, of which 5,606 were new. The merged list has 52,755 ids.
The launcher change is one bind-mount line. The two environment variables were already there:
```bash
-v /home/coolthor/qwen38fn-tuning/hunt-20260927/zhvocab-compile/draft_vocab_en_code_zh_both.txt:/etc/vllm-draft-vocab.txt:ro
-e VLLM_MTP_DRAFT_VOCAB=/etc/vllm-draft-vocab.txt
-e VLLM_MTP_DRAFT_VOCAB_BALANCE=1
```
`VLLM_MTP_DRAFT_VOCAB_BALANCE=1` splits the list evenly across the two TP ranks. It comes from MiaAI's unmerged [PR #45](https://github.com/MiaAI-Lab/Qwen3.8-Flash-Next-Dual-DGX-Sparks/pull/45), which is the overlay I run. The main branch does not have it, so drop that line if you are on main. An odd total is fine: both hosts log `balanced=True`.
Output doesn't change. Per the tool's own docs, a token missing from the list just gets rejected as a draft; it never becomes a wrong token. I checked three prompts at temperature 0 and the output was byte-identical before and after.
## Chinese decode: +60% on a prompt from my usual topics, +23–27% on everyday ones
This was the biggest gain of the round, from one bind-mount line, with byte-identical output on three test prompts. How much faster depends on how close the prompt is to the corpus. All at temperature 0, 400 tokens, median of 3, old list versus new list:
| Prompt | Old list | New list | Change |
|---|---|---|---|
| Chinese probe (bandwidth and tensor parallelism) | 27.64 tok/s | 44.31 tok/s | +60% |
| Traditional Chinese: home-style chicken recipe | 30.0 tok/s | 36.9 tok/s | +23% |
| Traditional Chinese: planning a mountain sunrise trip | 29.8 tok/s | 37.3 tok/s | +25% |
| Simplified Chinese: choosing a phone for an elderly parent | 31.7 tok/s | 40.3 tok/s | +27% |
On the probe, acceptance went from 0.114 to 0.978 tokens per step. On the three new prompts it went from 0.13–0.22 to 0.36–0.64.
The probe asks about bandwidth and tensor parallelism, which is what I work on every day and the same kind of text the list was built from. The other three are everyday topics that are not in the corpus; I wrote them after building the list, and they still rose 23–27% with acceptance up 2.6–3x. Across these four prompts, the closer the list is to what you actually run, the bigger the gain.
English and code held steady. English acceptance went from 1.226 to 1.103 per step, but English speed was flat (44.74 to 44.98 tok/s). Code went from 83.27 to 82.32, within run-to-run spread.
## Turn two of a conversation: TTFT from 3.30 s to 0.23 s
Coding agents resend the whole conversation on every turn, so turn two should be almost free if the prefix cache works. On this build it was not. I measured turn two as the same prefix plus one follow-up:
| Prefix length | Before: turn-2 TTFT / tokens hit | After: turn-2 TTFT / tokens hit |
|---|---|---|
| 9.5k tokens | 3.30 s / 0 | 0.23 s / 9,464 |
| 30k tokens | 4.73 s / 16,960 | 0.25 s / 29,992 |
Before the fix, turn two of the 9.5k conversation was as slow as turn one.
The cause is the hybrid architecture. Some of the layers are GDN, a Mamba-style recurrent layer. A recurrent layer can only resume from a position where its state was saved. The cache block is 848 tokens, and the state is saved only when a prefill chunk stops exactly on a block boundary. The scheduler aligned chunk stops to a configured value of 8, so the last segment of the prompt never ended on a reusable boundary, and turn two recomputed it.
The fix has two parts:
1. Align chunk stops to 848.
2. Borrow the wider tail-lookup margin from upstream [vLLM PR #57180](https://github.com/vllm-project/vllm/pull/57180) (unmerged at the time of writing), and subtract the 3 tokens that MTP re-fills when the tail is registered. The subtraction is my own finding; it is not in the PR.
The change touches the scheduler and two cache-manager files, mounted into the container as overlays. There is no config flag for it.
## The costs: a 69% smaller KV pool and FP8 GDN weights
**KV pool.** It went from 2,128,927 to 665,924 tokens (−69%). The speedups did not cause this. The Sep 24 change of `gpu-memory-utilization` from 0.835 to 0.68 did. On a DGX Spark the CPU and GPU share memory, so that headroom is shared with the host. At 262K tokens per request the pool holds 2.54 requests. The request queue stayed at zero.
**FP8 GDN weights.** The GDN weights are converted to FP8 (E4M3) at runtime. They are read on every step, so halving the bytes read made code, Chinese and English each 5–7% faster. This does change the target model's numerics. Code output was byte-identical. Chinese and English responses were worded differently, with the same meaning. Chinese style, tool calling and a 28k-token needle retrieval all passed, and the harness score held. If you need byte-stable output, this change can be removed on its own without touching the others.
## Deep dive: debugging notes
You can skip this section; everything above works without it. It is here for people reproducing the setup and for AI assistants reading the page on their behalf.
### Decode runs at 80–87% of memory bandwidth
Conclusion: decode is close to the bandwidth wall, so reducing bytes read is the lever.
How I measured: PyTorch profiler on an isolated code prompt. One MTP step takes 51 ms. The GPU is busy 95–96% of the time: dense GEMM 60–62%, MoE GEMM 22%, NCCL 8–10%.
Effective bandwidth is weight bytes divided by kernel time, using per-GPU weight sizes at TP=2. The GB10 spec is 273 GB/s.
| Kernel | Shape (BF16) | Bytes | Time | Effective bandwidth |
|---|---|---|---|---|
| GDN QKVZ | 8192×2560 | 41.9 MB | 191 μs | 219 GB/s (80%) |
| lm_head | 124160×2560 | 635.7 MB | 2,677 μs | 237 GB/s (87%) |
That is why GDN went to FP8: it reads half the bytes. An E4M3 FP8 microbenchmark at M=5, including input quantization, went from 179 to 97 μs.
### +15% GPU clock, no change in decode
The worker had been capped at 2,200 MHz because of a GB10 defect that hard-powers-off the box under sustained load ([Part 48](/en/blog/gx10-thermal-hard-poweroff)). I removed the cap for this test. Clock under load went from 2,177 to 2,502 MHz (+15%). Code decode over 5 runs: 81.3 versus 82.0 tok/s.
Takeaway: the workload is bandwidth-bound, not compute-bound; the cap costs nothing on decode.
### Custom skinny GEMMs saved less than 1% of a step
MTP verification multiplies only 1–5 rows at a time, so I tried custom kernels for that shape:
| GEMM | Stock | Custom |
|---|---|---|
| GDN | 176.4 μs | 165.8 μs (−6.0%) |
| HC | 28.3 μs | 27.8 μs |
| Output | 71.5 μs | 65.0 μs |
Takeaway: combined, these are under 1% of a 51 ms step. None shipped.
### Prefill: host-side gaps dominate, and NCCL uses 29% of the link
Conclusion: prefill is limited by host-side code and all-reduce latency, not by link bandwidth.
How I measured: a 12.5k-token prefill. The head node's forward pass takes 5.578 s; GPU kernels account for 3.278 s of it. Gaps longer than 10 ms:
- QSA indexer host code: about 0.99 s
- `aten::mul`: 0.48 s
- MoE shared path: 0.37 s
- one `cudaMalloc`: 172 ms
NCCL in the same trace: 71 BF16 all-reduces of shape (12520, 2560) at 64.1 MB each, plus one 32 MB int8 all-reduce, about 4.58 GB total. The head node spent 683.6 ms in them, which is 6.70 GB/s, or 53.6 Gb/s: 29% of the 185 Gb/s link I measured in Part 46.
A standalone 64.1 MB all-reduce between the two machines takes 6.18 ms, about 83 Gb/s. So the link is not saturated; the time goes to latency and scheduling. `NCCL_PROTO=Simple` was slower at both 64 MB and 25.6 KB, so I rejected it.
### Rejected changes
Conclusion: none of these helped at this configuration.
| Change | Result |
|---|---|
| `max_num_batched_tokens` 32,768 | Server does not start: at GMU 0.68 the KV pool cannot hold a 262K request |
| `max_num_batched_tokens` 24,576 | 12.5k cold TTFT 23% slower |
| MiaAI #66 `disable_eagle_block_drop` | No-op on the Qwen path (no eagle group); cache hits unchanged |
| `mamba_cache_mode=all` | No change; the non-aligned path falls back to block-size hash granularity |
| torch.compile mode 3 | Not run: MiaAI PR #45 records a 103-minute compile on two GB10s that never finished (RPC timeout) |
| IRQs pinned to big cores, chunk 8192, GDN FlashInfer prefill | Rejected Sep 24; FlashInfer prefill made a four-request run 8.8% slower |
### Measurement noise nearly blocked the vocab change
Conclusion: a fixed 3% gate misfires when the metric's own noise exceeds 3%.
The first A/B of the new vocabulary tripped my rule "no other metric regresses by more than 3%": 12.5k cold TTFT was 3.67% slower. I went back to the old configuration and ran the same measurement again: 6.35 / 4.14 / 6.10 s. Cold TTFT swings about 50% on its own. The draft vocabulary only affects which tokens MTP proposes during decode; prefill never touches it.
The gate was meant to ask "did this make anything worse". Written as "nothing else moves more than 3%", it fires every time on a metric noisier than 3%. After checking which code path the change touches and accounting for the noise, I shipped the vocabulary.
### A reboot would have brought back the old stack (fixed Sep 28)
The worker had the old stack's `qwen38fn-tp2-worker.service` enabled, while the one actually in use, `qwen38fn-miaai-worker.service`, was disabled. The two units declare `Conflicts=` on each other, so enabling the wrong one swaps the whole stack on boot. On publish day I ran `systemctl enable qwen38fn-miaai-worker` and `systemctl disable qwen38fn-tp2-worker`; a cold reboot of both hosts has not been tested yet.
If you copy this setup, enable the service you actually run and disable the old one.
### Methodology
Harness (same 40 prompts as Part 46, thinking off, concurrency 1, run on the GX10 because coding prompts execute code):
```bash
cd ~/src/tonyd2wild-nvfp4/single-spark-vllm-tp1 && python3 tools/bench_categories.py http://127.0.0.1:8000 qwen38-flash-next --thinking off --concurrency 1 --tag runN
```
Probe (temperature 0):
```bash
python3 ~/patches/decode_probe3.py qwen38-flash-next 0
```
Rules:
- Each run started only when `vllm:num_requests_running` was 0.
- Accepted tokens per step = the change in `spec_decode_num_drafts_total` and `spec_decode_num_accepted_tokens_total` across a run, kept only if `request_success_total` rose by exactly 1.
- Turn-two hits = the increment of `prefix_cache_hits_total`.
- 3 runs per configuration, median reported.
---
Also in this series: [Part 46: Qwen3.8-Flash-Next TP=2 on two DGX Sparks, 51.9 tok/s](/en/blog/qwen38-flash-next-tp2-two-dgx-sparks) · [Part 45: single-node NVFP4 recipe, 41.7 tok/s](/en/blog/qwen38-flash-next-nvfp4-dgx-spark-vllm-recipe)
---
# Two Modded RTX 2080 Tis Hit 153.8 tok/s on Qwen3.8-27B With FastLLM + DFlash2
URL: https://ai-muninn.com/en/blog/fastllm-dflash2-dual-2080ti
Date: 2026-09-21
Series: 改裝 2080 Ti 22G (Part 20)
FastLLM plus the DFlash2 draft model runs Qwen3.8-27B FP8 on two modded 2080 Ti 22G at **153.8 tok/s** on code and 134.9 on math. My previous llama.cpp setup ran at about 66. FastLLM alone does 33.7; the whole gain is the draft. It works because decode here is memory-bound: one read of the weights checks all 7 drafted tokens. 262K context fits with an fp4 KV cache. The cost: prose drops to 53.1, and my 140-question eval scores 128 against 131.
## Preface
A delivery van costs about the same to run whether it carries one parcel or twenty. The driver and the fuel are paid per trip, so the cheapest parcel is the one that rides in a full van.
Generating text with a 27B model has the same economics. Every token the model produces requires reading all of its weights out of VRAM. Speculative decoding fills the trip: a small draft model guesses several tokens ahead, the big model checks all of those positions in one pass over its weights, and every correct guess is kept.
Someone on Bilibili, the Chinese video site, used this to push two modded 2080 Ti 22G cards past 150 tok/s. [Part 14](/en/blog/qwen38-dual-2080ti-tensor-parallel) put the same model on the same two cards with llama.cpp, and after later tuning it ran at 66 tok/s as this machine's main model server. This part rebuilds the Bilibili recipe, FastLLM plus the DFlash2 draft model, and gets 153.8 tok/s on code. It has replaced the llama.cpp setup as the main model server.
## FastLLM and DFlash2: a C++ server and a 3.6 GB draft that guesses 7 tokens per step
[FastLLM](https://github.com/ztxz16/fastllm) is a C++ inference framework. It installs from pip as `ftllm`, and `ftllm server` exposes an OpenAI-compatible API. The 2080 Ti is Turing (sm_75) and has no FP8 hardware. FastLLM stores FP8 weights as FP8 and converts them to FP16 inside the kernel for the math, Marlin-style W8A16. On this card, FP8 saves bytes read, not compute.
[DFlash2](https://huggingface.co/z-lab/Qwen3.8-27B-DFlash2) is a draft model from z-lab built for Qwen3.8-27B: 5 layers, 3.6 GB. It's a block-diffusion drafter. Instead of guessing one token at a time, it predicts a whole block of tokens in one pass, and a selector picks one coherent path through that block for the main model to verify. With `--speculative_num_draft_tokens 8` it drafts 7 tokens per step.
## FastLLM alone runs 33.7 tok/s; DFlash2 takes it to 152.3
Measured separately:
- FastLLM with no speculation: **33.7 tok/s**. That's half of the 66 from llama.cpp Q8_0 + MTP (MTP is Qwen3.8's built-in draft head).
- FastLLM plus DFlash2: **152.3 tok/s**, on the official FP8 weights with a code prompt.
The 4.5× comes entirely from the draft.
## 156 tok/s on code, 134.9 on math, 53.1 on prose
Method: real chat requests, temperature 0, up to 512 output tokens, three prompt types (code, math, prose), 3 runs each, median, timed by wall clock on the client. Both cards run with tensor parallel 2 (TP=2). The last row is the config that went into production.
| config (two 2080 Ti, TP=2) | code | math | prose |
|---|---:|---:|---:|
| no speculation (official FP8) | 33.7 | 33.3 | 33.2 |
| built-in MTP 8 (uncensored FP8) | 62.1 | 53.3 | 24.0 |
| DFlash2, 262K (uncensored FP8) | 156.0 | 134.9 | 53.1 |
That last row runs a 262K context with an fp4 KV cache. The official and uncensored weights run at about the same speed; the full comparison is in the deep dive. Before going live I also dropped `--cuda_embedding` (trap 3 explains why) and re-measured code: 153.8 tok/s, against 154.1 with the flag on. That's noise. The 153.8 in the TL;DR is the go-live measurement.
The old llama.cpp setup (Q8_0 + MTP, two cards) ran at 66 tok/s. That 66 is the median decode speed from a 140-question capability eval, with temperature 1.0 and thinking on. It's a different harness from the three prompts above, so treat it as a reference point. A Bilibili commenter with the same hardware ran one identical API test on both (a snake-game prompt, 256 tokens): llama.cpp 58, FastLLM + DFlash about 100–110., pointing the same way.
So "past 100 tok/s" only holds for code and math. Prose got slower than the old setup.
## Why speculation pays here: decode already uses 79% of 1,232 GB/s
Each generated token reads every weight once, so decode tok/s × weight size gives the bytes read from VRAM per second. Two 2080 Tis have 1,232 GB/s of combined theoretical bandwidth.
| config | weights | decode | bytes/s | % of peak |
|---|---:|---:|---:|---:|
| FastLLM FP8, no speculation | 29 GB | 33.7 | 977 GB/s | 79% |
| FastLLM FP8 + DFlash2 | 29 GB | 152.3 | 4,417 GB/s | 358% |
Without speculation, the model already uses 79% of the bandwidth. Decode is memory-bound, and the compute units sit mostly idle. The 358% in the second row isn't overclocking. It shows the weights are no longer read once per token: one read verifies several positions, so the real traffic is under a third of the naive number. Speculation spends idle compute to avoid repeated weight reads.
That only works when the main model is memory-bound. [Part 19](/en/blog/ternary-bonsai-2-27b-one-2080ti) is the counter-example. Ternary Bonsai 2's ternary weights are only 7.2 GB and use 46% of the card's bandwidth, and the limit there is the arithmetic of unpacking them. A DFlash2-family draft on that model beats built-in MTP by only 3–8%, and gets slower the more it drafts.
## What you need: two 22 GB 2080 Tis, ftllm 0.1.8.2, a 29 GB model and a 3.6 GB draft
- **Two modded 2080 Ti 22G.** Mine are connected with NVLink (NV2). The Bilibili reproductions all had NVLink too. FastLLM's own 5090 benchmark ran over PCIe, so NVLink isn't strictly required, but I haven't tested 2080 Tis without it.
- **A Python 3.14 venv with `ftllm` 0.1.8.2.**
- **Main model: [orcarouter/Qwen3.8-27B-Uncensored-FP8](https://huggingface.co/orcarouter/Qwen3.8-27B-Uncensored-FP8)**, about 29 GB on disk, uncensored. The official `Qwen/Qwen3.8-27B-FP8` also works at about the same speed.
- **Draft: [z-lab/Qwen3.8-27B-DFlash2](https://huggingface.co/z-lab/Qwen3.8-27B-DFlash2)**, 3.6 GB.
- **An NCCL build that includes sm_75.** I used the 2.31.2 I compiled in [part 16](/en/blog/nccl-2080ti-stub-library-fix).
## How to install and launch FastLLM with DFlash2 on two 2080 Tis
Create the venv and download both models:
```bash
python3.14 -m venv ~/venvs/ftllm
~/venvs/ftllm/bin/pip install ftllm==0.1.8.2
hf download orcarouter/Qwen3.8-27B-Uncensored-FP8 --local-dir /mnt/nvme1t/models/qwen38-27b-uncensored-fp8
hf download z-lab/Qwen3.8-27B-DFlash2 --local-dir /mnt/nvme1t/models/dflash2-qwen38-zlab
```
The chat template is the community-fixed one from [part 13](/en/blog/chat-template-kv-mtp-free-speedup), [froggeric/Qwen-Fixed-Chat-Templates](https://huggingface.co/froggeric/Qwen-Fixed-Chat-Templates). I used v22.3 (the URL below is pinned to that commit; `main` is now v22.5, where this `sed` pattern doesn't match) with one change: the default reasoning effort goes from `medium` to `low`. The deep dive explains why.
```bash
mkdir -p /mnt/nvme1t/models/qwen-fastllm-low
wget -O /mnt/nvme1t/models/qwen-fastllm-low/chat_template.jinja \
https://huggingface.co/froggeric/Qwen-Fixed-Chat-Templates/resolve/492315ea6d7343bcfb32598d6a898c34e0d69ed8/chat_template.jinja
sed -i "s/is not none else 'medium' %}/is not none else 'low' %}/" \
/mnt/nvme1t/models/qwen-fastllm-low/chat_template.jinja
```
This is the exact launch line running in production:
```bash
export LD_PRELOAD=/home/coolthor/nccl-install/lib/libnccl.so.2 # NCCL with sm_75
export CUDA_VISIBLE_DEVICES=0,1
export FASTLLM_CUDA_GRAPH=0 # must be 0 with DFlash2
~/venvs/ftllm/bin/ftllm server \
-p /mnt/nvme1t/models/qwen38-27b-uncensored-fp8 --model_name qwen38-27b-ud \
--tp 2 --max_batch 1 --tokens 262144 --gpu_mem_ratio 0.95 --kv_cache_dtype fp4 \
--speculative_algorithm dflash \
--speculative_draft_model_path /mnt/nvme1t/models/dflash2-qwen38-zlab \
--speculative_num_draft_tokens 8 \
--prefix_cache true \
--chat_template /mnt/nvme1t/models/qwen-fastllm-low/chat_template.jinja \
--host 0.0.0.0 --port 8082
```
`--model_name` reuses the model name the old service exposed, so no client had to change a line.
## Four things that break when you copy the Bilibili recipe onto 2080 Tis
The deep dive has the full error output for each.
1. **NCCL without sm_75.** Speculative decoding on two cards fails with `ncclAllReduce failed: unhandled cuda error`; I hit it with MTP. FastLLM actually loads Ubuntu's NCCL 2.22.3, and the one pip pulls in lacks sm_75 too. The `LD_PRELOAD` line in the launch block fixes it.
2. **DFlash2 with CUDA Graph always crashes**, with `cudaErrorIllegalAddress`. It needs `FASTLLM_CUDA_GRAPH=0`. FastLLM's docs say the opposite, that on sm_75 you turn it on with 1. That advice only applies without speculation.
3. **262K needs three settings together.** `--kv_cache_dtype fp4`, because with fp8 KV the draft weights don't fit. No `--cuda_embedding`: upstream recommends it, but it parks 2.4 GB on GPU0. And `--gpu_mem_ratio 0.95`: 0.97 crashes on long prompts, and 0.90 is worse.
4. **Requests that turn thinking on get the reasoning inside `content`.** Because the launch passes `--chat_template`, FastLLM disables Qwen's reasoning split. With `enable_thinking: true`, the whole reasoning plus a stray `` lands in `content`, and `reasoning_content` is empty. Clients that send `enable_thinking: false` get a clean answer. Clients that want thinking have to strip everything before `` themselves.
## Prefix cache: an 8,747-token shared prefix drops from 8.2 s to about 1 s
Agent and RAG requests often open with the same long block (a system prompt, tool docs, the same document) and differ only at the end. I tested an 8,747-token shared prefix over 6 rounds, each with a different ending. The middle column shows the cache at work.
| | first round | median after | cached per round |
|---|---:|---:|---:|
| `--prefix_cache true` | 8.2 s | 1.0–1.2 s | 8,192 tokens |
The go-live acceptance check used a 14K prefix: 14.2 s cold, 2.0 s warm, 14,336 tokens cached. The prefix cache keeps working with DFlash2 on.
## 262K context really fits: a needle at 199,787 tokens came back correct
I buried one sentence, "The secret access code for building 7 is MAPLE-4416.", in the middle of a long document and asked for the code. Four of the six lengths are in the table. Prefill slows as the prompt grows.
| actual prompt tokens | prefill | time | needle |
|---:|---:|---:|---|
| 22,647 | 1,109 tok/s | 20 s | found |
| 91,478 | 855 tok/s | 107 s | found |
| 140,022 | 734 tok/s | 191 s | found |
| 199,787 | 652 tok/s | 306 s | found |
All six lengths passed with zero restarts. Prefill slows steadily as the prompt grows, with no cliff.
Don't mix up two numbers here. 262,144 is the total KV pool. The limit for a single prompt comes from this log line, `AddPrefill Pages limit: 1638 pages (80% of 2048)`, which works out to about 209K tokens.
Vision still works. This FP8 checkpoint includes the vision tower, so there's no separate mmproj file. I sent a 448×448 image with three shapes, and the reply was "red circle top left / blue square top right / green triangle bottom center". Shapes, colors and positions were all correct.
## The catch: prose about 20% slower, and 3 fewer questions right out of 140
Prose runs at 53.1 tok/s against 66 for the old llama.cpp setup.
Both setups got the same 140 questions: GSM8K 50, MATH-500 30, MuSR 20, HumanEval+ 40. Look at the total, then MuSR:
| | GSM8K | MATH-500 | MuSR | HumanEval+ | total |
|---|---:|---:|---:|---:|---:|
| FastLLM, thinking off | 49 | 29 | 15 | 35 | 128 |
| FastLLM, thinking on + effort low | 50 | 30 | 9 | 36 | 125 |
| llama.cpp Q8_0, thinking on | 50 | 30 | 13 | 38 | 131 |
128 is the production config with requests that carry no extra parameters, so the model doesn't think. The llama.cpp setup had thinking on. On FastLLM, thinking on and off differ almost entirely in MuSR, 15 against 9; every other benchmark differs by one question. In the thinking-off run, no question hit the 8,192-token limit. In the thinking-on run, one did. My own services already send `enable_thinking: false`, so 128 is what they actually get.
My own requests to this box aren't that hard. Three questions for more than 2× code speed was an easy trade. The old llama.cpp setup is still installed intact, and two `systemctl` commands switch back.
---
## Deep dive: the Bilibili sources, the four traps, reasoning effort, and every config measured
You can skip this section. Everything above is enough to run the setup; what follows is the full data, the verbatim errors and the source reading behind each claim.
### Where the recipe came from: two Bilibili videos, two different frameworks
Two videos pointed me here, and they use different frameworks.
- [BV13vbK6yEhp](https://www.bilibili.com/video/BV13vbK6yEhp/) (uploader _黄歪歪, 2026-09-07) is the FastLLM route: `pip install ftllm`, FP8 weights, DFlash2. Its title says 150+ TPS, and a commenter relays the video's claim of an FP8 average above 100 tok/s.
- [BV1Ader61ETR](https://www.bilibili.com/video/BV1Ader61ETR/) (uploader SPOTLITE, 2026-09-18) has a pinned comment pointing to [weicj/vLLM-2080Ti-Definitive](https://github.com/weicj/vLLM-2080Ti-Definitive), an sm_75 fork of vLLM. It has nothing to do with FastLLM, and it needs CUDA 13, PyTorch 2.13 and Python 3.12. I didn't take that route.
Bilibili has no subtitles on these videos, so I couldn't verify what's on screen. Everything here comes from the video descriptions, the comments and the official repos.
A commenter under the first video, 听我贤扯, reproduced it on the same dual-22G + NVLink setup: 33.0 tok/s for FP8 without speculation, and 191.8 for FP8 + DFlash B8 on a fixed synthetic output stream. My 33.7 without speculation matches that 33.0, so the environments are comparable. The gap between 191.8 and my 152.3 is methodology: a fixed synthetic stream against real chat requests.
### Trap 1: ncclAllReduce failed because the NCCL that FastLLM loads has no sm_75
The first run with built-in MTP failed with:
```
Error: ncclAllReduce failed on device 0: unhandled cuda error
Error: ncclAllReduce failed on device 1: unhandled cuda error
```
Decode came in at 19.9 tok/s, slower than no speculation, and then the server died. TP=2 without speculation had run fine, which puts the problem in an AllReduce that only the speculative path reaches.
The machine had three copies of libnccl:
- Ubuntu's package, 2.22.3
- `nvidia-nccl-cu12` 2.31.2, pulled in by pip along with ftllm
- the 2.31.2 I compiled myself in [part 16](/en/blog/nccl-2080ti-stub-library-fix)
`ldd` on FastLLM's `libfastllm_tools.so` shows it loads the system 2.22.3. To see which GPU architectures each build contains:
```bash
cuobjdump --list-elf | grep -oE 'sm_[0-9]+' | sort -u
```
Only the self-built one has sm_75. Pointing `LD_PRELOAD` at it fixes the error, with no FastLLM rebuild.
The error never mentions architecture, which is what makes this one hard to trace. On a 2080 Ti I treat any third-party NCCL build as broken until that command says otherwise.
### Trap 2: DFlash2 crashes with cudaErrorIllegalAddress unless CUDA Graph is off
With `FASTLLM_CUDA_GRAPH=1` and DFlash2, the first request after loading crashes with `cudaErrorIllegalAddress`. It crashed that way more than a dozen times in a row, and the server died each time.
What didn't help: other ways of writing `--tp 2`, `--dtype float16`, `--atype float16`. BF16 isn't the cause either. The log shows the BF16 weights are already converted to FP16:
```
[Qwen3.5 DFlash2] converted 18 BF16 linear weights to FP16 for the pre-Ampere mixed GEMM path
```
`FASTLLM_CUDA_GRAPH=0` worked on the first try, and decode went from 33.7 to 152.3 tok/s.
FastLLM's docs say sm_75 and older default to CUDA Graph off, and that you turn it on with `FASTLLM_CUDA_GRAPH=1`. My no-speculation run used 1 and got 33.7. With DFlash2, following that advice breaks the server. Built-in MTP runs either way: 61.5 tok/s on code with the graph on, 62.1 with it off, which is noise.
### Trap 3: fitting 262K with fp4 KV, no --cuda_embedding and gpu_mem_ratio 0.95
My first attempt used an fp8 KV cache. At 262K it ran out of memory while loading the draft weights:
| KV type | 262,144 | 196,608 |
|---|---|---|
| fp8_e4m3 + DFlash2 | OOM (loading `dflash.layers.4.mlp.gateup_proj`) | loads |
| fp8_e4m3 + built-in MTP | loads | |
The KV pool itself allocates fine (`KV Cache Token limit: 262144 tokens, totalPages=2048`). It's the draft that doesn't fit.
Switching the KV cache to fp4 gets out of that bind. Qwen3.8-27B has only 16 full-attention layers out of 64, and the log's `tokenGrowingLayers=16` agrees. KV per token is 16 layers × 2 × 4 heads × 256 dims = 32,768 elements. At 262K that's 8 GiB in fp8 (4 per card) or 4 GiB in fp4 (2 per card), so fp4 saves 2 GiB on each card. Speed barely changes:
| config | code | math | prose | peak VRAM (GPU0 / GPU1) |
|---|---:|---:|---:|---:|
| 192K + fp8 KV | 161.3 | 134.7 | 55.4 | 21,956 / 21,272 MiB |
| 262K + fp4 KV | 156.0 | 134.9 | 53.1 | 21,652 / 20,540 MiB |
At that point, though, 262K was only on paper. FastLLM's AutoWarmup log:
```
GPU 0: availForKV=1.41 GB
GPU 1: availForKV=2.49 GB
KV Cache Token limit: 262144 (totalPages=2048, pageLen=128), localKVPerPage=1.18 MB
```
The pool needs 2,048 pages × 1.18 MB = 2.36 GB per card. GPU0 can only give 1.41 GB, so it's overcommitted by about 1 GB. Pages are allocated lazily, so short prompts work fine. Actually filling the pool would crash GPU0; the real capacity was about 156K. GPU0 is the tighter card because the DFlash2 draft runs only on the first card, a known FastLLM limitation.
**Dropping `--cuda_embedding` fixes it.** With the flag on, the embedding table (vocab 248,320 × hidden 5,120) sits on GPU0 in FP16, about 2.4 GB.
| | `--cuda_embedding` on | off |
|---|---:|---:|
| GPU0 availForKV | 1.41 GB | 3.96 GB |
| GPU1 availForKV | 2.49 GB | 5.04 GB |
Both cards now have at least 1.6 GB of headroom over the 2.36 GB the pool needs. Code runs at 153.8 against 154.1. FastLLM's report recommends `--cuda_embedding` with DFlash2; on these two cards, that doesn't hold.
**`--gpu_mem_ratio` is 0.95.** At 0.97, long prompts crash:
```
CUDA error when allocating 12 MB on device 0! gpuFree: 2 MB / 22000 MB
cublas error in ChunkGatedDeltaRule batched matmul
```
That's 2 MB left on the card. At 0.95 the same 8,747-token test passes 6 of 6.
Going lower for more headroom is the obvious next move. 0.90 is worse. It raises the reserve for transient allocations from 1.15 GB to 2.31 GB, and `availForKV` drops to 0.26 GB. The ratio sets the model's share of the card, not the transient reserve.
### Trap 4: MuSR runs into the token limit, and a flag that did nothing
My first run used the model's built-in template. By question 93, all 13 MuSR questions it had reached ended with `finish_reason=length`: empty content, up to 36,628 characters of reasoning. On one of those questions, the llama.cpp setup answers correctly in 1,259 tokens. Same model, so the problem is on the serving side. The fix came in two layers.
**Layer 1, the template.** The model's built-in `chat_template.jinja` (9 KB) does have reasoning-effort control, but it defaults to xhigh, so a request that doesn't set effort gets the longest thinking. I switched to froggeric's v22.3 (26 KB), which defaults to medium. GSM8K went from 49 to 50. MuSR was still 1/20, with 19 of 20 hitting the limit.
**Layer 2, froggeric's `medium` injects nothing.** Only xhigh and low add instruction text; the medium branch is empty. With no brevity constraint, the model wrote until it hit 8,192 tokens without emitting ``. The reasoning shows it had already found the answer. The end was a loop of "Need final. Ensure final includes boxed. Let's compose final answer:".
Same question, sent with `chat_template_kwargs: {"enable_thinking": true, "reasoning_effort": "low"}`, against medium:
| effort | output tokens | finish | has `` | result |
|---|---:|---|---|---|
| medium | 8,192 | length | no | no answer |
| low | 1,929 | stop | yes | correct |
Over all 140 questions, limit hits went from 23 to 1, MuSR from 1/20 to 9/20, and the score from 110/133 (the medium run only completed 133 questions) to 125/140.
I also tried adding my own line to the medium branch: "Keep your thinking under about 2000 words". MuSR rose to 12/20, but MATH-500 and HumanEval+ each dropped a little, and limit hits went from 1 to 5. The total was still 125. Effort is a global knob, and a gain on one benchmark didn't add to the total. I dropped it.
**`--think` changed nothing.** I once believed `--think true` kept the model from closing its reasoning. After I switched it to false, a spot check had MuSR jump from 9/20 to 16/20, and I wrote "use `--think false`" into my notes as a setting. Reading the source showed the attribution was wrong:
- `--think` defaults to `"false"` (`ftllm/util.py`). Writing `--think false` is the same as leaving it out, so I removed it from the unit file.
- All it does is prepend `\n` to the text returned to the client (`openai_server/fastllm_completion.py`: `result = "" if emit_reasoning_content else ("\n" if think else "")`). It never goes back into the model's input, so it can't change what the model answers.
- The 16/20 spot check sent no `chat_template_kwargs`, so the model answered in non-thinking mode. The 9/20 group had thinking on with effort low. The request changed, not the flag. I later ran all 140 questions the same way, with no parameters: 128/140, MuSR 15/20.
**The `` in `content` comes from `--chat_template`.** Passing a custom template sets `force_chat_template` to true (`llm.py`), and Qwen reasoning splitting is disabled when the template is forced (`_is_qwen3_5_reasoning_response`). So thinking-on requests get the reasoning plus a `` inside `content`, while thinking-off requests come back clean. My own two services, a multi-model aggregator and a RAG server, send `enable_thinking: false` and get clean answers. The Pi agent runs with thinking on, and that's where the stray `` shows up.
### Draft tokens: 8 is the sweet spot, 12 won't start
Same method as the main table.
| `--speculative_num_draft_tokens` | actual drafts per step | code | math | prose |
|---:|---:|---:|---:|---:|
| 4 | 3 | 90.2 | 85.0 | 52.3 |
| 8 | 7 | 156.0 | 134.9 | 53.1 |
| 12 | — | server won't start | | |
The value includes the anchor token, so N drafts N−1. 8 matches the block size of 8 on the DFlash2 model card, which is 7 draft tokens per verification.
### Every config, measured the same way
Temperature 0, 512 tokens, median of 3, in tok/s.
| config | code | math | prose |
|---|---:|---:|---:|
| official FP8, no speculation | 33.7 | 33.3 | 33.2 |
| uncensored FP8, no speculation | 32.9 | 32.6 | 32.4 |
| official FP8 + MTP 8 | 59.0 | 51.3 | 23.2 |
| uncensored FP8 + MTP 8 (graph=1) | 61.5 | 51.2 | 23.2 |
| uncensored FP8 + MTP 8 (graph=0) | 62.1 | 53.3 | 24.0 |
| official FP8 + DFlash2 | 152.3 | 136.8 | 57.6 |
| uncensored FP8 + DFlash2, 192K fp8 KV | 161.3 | 134.7 | 55.4 |
| uncensored FP8 + DFlash2, 262K fp4 KV | 156.0 | 134.9 | 53.1 |
The uncensored weights aren't slower. Built-in MTP on prose runs at 24, slower than no speculation, and DFlash2 on prose reaches only about 55.
### Version pinning: a verify.sh that checks 10 fingerprints before every start
This setup works because of version-specific behavior: `--chat_template` disabling the reasoning split, DFlash2 needing CUDA Graph off, NCCL loaded through `LD_PRELOAD`, and 262K needing `--cuda_embedding` off. Any `pip install -U` could break it without an error.
What I pinned:
- `requirements.lock` (76 packages) and 76 wheels, including `ftllm-0.1.8.2` itself
- a tarball of the whole venv
- the unit file, the chat template and the self-built NCCL
- a `verify.sh` hooked in as the systemd `ExecStartPre`. Before every start it checks 10 fingerprints: ftllm version, Python, the `libfastllm_tools.so` hash, the unit file, the template, NCCL, and the configs and weight sizes of the model and the draft. If anything changed, it refuses to start and names what changed.
I checked the restore path too. The `.so` hash inside the tarball matches the running one, and rebuilding with `pip install --no-index` from the local wheels produces a byte-identical `.so`. Even if PyPI pulls 0.1.8.2, the same build can be recreated.
### Still unmeasured
- DFlash2 acceptance rate. FastLLM's usage fields don't report draft stats.
- The NVFP4 route. The Bilibili commenter measured NVFP4 + DFlash B8 at 246.9 tok/s on a fixed output stream. I didn't download those weights.
- The GPU0/GPU1 asymmetry, with DFlash2 running only on GPU0. It isn't a bottleneck now. I'll come back to it if I push context further.
---
**Also in this series:**
- [#19 Ternary Bonsai 2 27B on one 2080 Ti, where DFlash2 barely helps](/en/blog/ternary-bonsai-2-27b-one-2080ti)
- [#16 Fixing NCCL's stub-library error on two 2080 Tis](/en/blog/nccl-2080ti-stub-library-fix)
- [#14 Two modded 2080 Tis running Qwen3.8-27B with llama.cpp tensor parallel](/en/blog/qwen38-dual-2080ti-tensor-parallel)
- [#13 A broken chat template and a starving MTP head on the 2080 Ti](/en/blog/chat-template-kv-mtp-free-speedup)
---
# Ternary Bonsai 2 on One RTX 2080 Ti: Qwen3.8-27B in 7.2 GB Scores 130 of 140
URL: https://ai-muninn.com/en/blog/ternary-bonsai-2-27b-one-2080ti
Date: 2026-09-21
Series: 改裝 2080 Ti 22G (Part 19)
Ternary Bonsai 2 27B is PrismML's version of Qwen3.8-27B with nearly every weight set to −1, 0 or +1. On one modded 22 GB 2080 Ti, through PrismML's llama.cpp fork, it scored **130/140** on my eval set. Qwen3.8-27B Q8_0 + MTP on two cards scored **131**. The price is speed: 36.85 tok/s on one card against 66.04 on two. Set `--reasoning-effort medium`; the default, xhigh, scores 116. The smallest file decodes slowest, because decode here is limited by unpacking weights and Hadamard math, not by memory bandwidth. Caveat: I scored the 7.2 GB PQ2_0 file, not the 5.9 GB PTQ1_0 in the headline.
## Preface
A vacuum storage bag shrinks a duvet to a quarter of its size. You pay for it later: every time you want the duvet, you open the bag and wait for it to puff back up.
[Part 14](/en/blog/qwen38-dual-2080ti-tensor-parallel) ran Qwen3.8-27B as Q8_0 across two modded 2080 Tis, with its built-in MTP draft head. After tuning it decoded at 66 tok/s and became this machine's main serving setup. This part takes the same model compressed to ternary weights, fits it on one card, and asks how much of the model survives. On my 140-question set, one question separates them: 130 vs 131.
## What Ternary Bonsai 2 is: Qwen3.8-27B with nearly every weight at −1, 0 or +1
Ternary Bonsai 2 27B is a model from PrismML, derived from Qwen3.8-27B. Nearly every weight is −1, 0 or +1, and each group of 128 weights shares one FP16 scale. Three possible values carry log2(3) ≈ 1.58 bits of information per weight. Averaged over the whole model, it comes to 1.72 bits per weight. The linear-attention state path and the norm weights, about 0.1% of the language model, stay at higher precision; the 1.72 already counts them.
The weights are stored in a rotated basis. The rotation is a Hadamard transform: a fixed orthogonal matrix made of +1s and −1s, applied here in blocks of 1024. Because the weights were rotated, the runtime has to apply the matching transform to each layer's input activations before the multiply. Stock llama.cpp has no such step, so it rejects the two Bonsai formats, PQ2_0 and PTQ1_0, as unknown types. The model card also warns that stock llama.cpp loads Q2_0 files without complaint and outputs garbage. The rotation matters again in the speed section.
The same ternary weights ship in two packings. The 5.9 GB in PrismML's headline is PTQ1_0.
| packing | how each trit is stored | bits/weight | file |
|---|---|---:|---:|
| PTQ1_0 | packed densely | 1.75 | 5.95 GB |
| PQ2_0 | one per 2-bit slot | 2.13 | 7.21 GB |
A trit is one ternary digit. PQ2_0 wastes part of each 2-bit slot, and in exchange its trits are cheaper to unpack.
## PrismML's claim: 98.2% of FP16 in 5.9 GB, where IQ2_XXS keeps 84.1%
These numbers come from the [model card](https://huggingface.co/prism-ml/Ternary-Bonsai-2-27B-gguf), not from my runs: H100, EvalScope with vLLM, thinking mode, averaged over 14 benchmarks. Compare the last column for IQ2_XXS and Bonsai 2, which sit in the same ~2-bit class.
| variant | size | 14-benchmark average | vs FP16 |
|---|---:|---:|---:|
| Qwen3.8-27B FP16 | 54 GB | 86.32 | 100% |
| UD-Q4_K_XL | 17.6 GB | 85.18 | 98.7% |
| IQ2_XXS | 9.4 GB | 72.59 | 84.1% |
| Bonsai 2 27B | 5.9 GB | 84.78 | 98.2% |
At about 2 bits, the conventional quant keeps 84.1%. Bonsai 2 keeps 98.2%, half a percentage point below the 17.6 GB UD-Q4_K_XL.
## 130 vs 131 out of 140: one card against the two-card Q8_0 setup
My eval set is 140 questions: 50 from GSM8K, 30 from MATH-500, 20 from MuSR and 40 from HumanEval+, drawn with a fixed seed. Both setups got the same questions and the same scoring. Thinking was on. Sampling followed Qwen's recommendation: temperature 1.0, top_p 0.95, top_k 20. Each question got an 8,192-token output cap, and requests ran one at a time.
Compare the scores against the card counts:
| setup | cards | weights | score /140 | median decode |
|---|---:|---:|---:|---:|
| Bonsai 2 PQ2_0, reasoning effort medium | 1 | 7.2 GB | 130 | 36.85 tok/s |
| Bonsai 2 PQ2_0, effort xhigh (fork default) | 1 | 7.2 GB | 116 | 35.38 tok/s |
| Qwen3.8-27B Q8_0 (abliterated) + MTP, llama.cpp | 2 | 29 GB | 131 | 66.04 tok/s |
Per benchmark, medium-effort Bonsai vs the Q8_0 setup: MATH-500 30/30 on both, MuSR 15/20 against 13/20 with Bonsai ahead, HumanEval+ 36/40 against 38/40, GSM8K 49/50 against 50/50.
130/131 is 99.2% of the Q8_0 setup. That is a different yardstick from PrismML's 98.2%. Theirs compares against FP16 on 14 benchmarks on an H100. Mine compares against Q8_0 on 4 benchmarks and 140 questions.
Two caveats:
- I ran the 140 questions on the 7.2 GB PQ2_0, not the 5.9 GB PTQ1_0 in the headline. The ternary weights are the same, so capability should match, but on PTQ1_0 I only measured speed.
- This compares two setups, not two quantizations. The Q8_0 side also runs MTP across two cards, so the gap isn't purely quantization.
The speed column needs the same warning: the two numbers come from different hardware. I picked Q8_0 as the baseline because it's close to lossless, which makes it the right yardstick for how much an extreme quant gives up. At 29 GB it doesn't fit on one 22 GB card, so it runs across two. Bonsai's 36.85 tok/s is one card; Q8_0's 66.04 tok/s is two.
## Why the smallest file decodes slowest: Bonsai uses 46% of the card's bandwidth, Q4_K uses 78%
These are llama-bench runs on the same fork and one 2080 Ti. tg128 is decode speed over 128 generated tokens; that's the column to watch.
| weights | file | pp512 | tg128 | total VRAM |
|---|---:|---:|---:|---:|
| PTQ1_0 | 5.95 GB | 435 tok/s | 32.71 tok/s | 6,670 MiB |
| PQ2_0 | 7.21 GB | 691 tok/s | 39.12 tok/s | 7,818 MiB |
| Q4_K (same base model) | 15.66 GiB | 634 tok/s | 28.68 tok/s | 16,330 MiB |
The VRAM readings include 346 MiB that ComfyUI was holding on that card.
The smallest packing is the slowest. PQ2_0 is 1.2 GB bigger than PTQ1_0 and decodes 19.6% faster. Against Q4_K, PQ2_0 decodes 36% faster in less than half the VRAM.
To see why, compute how much of the card's memory bandwidth decode actually uses. Each generated token reads every weight once, so decode tok/s × weight file size is the number of bytes read from VRAM per second. Divide that by the 2080 Ti's theoretical 616 GB/s (352-bit bus × 14 Gbps):
- Q4_K: 16.8 GB (15.66 GiB) × 28.68 = 482 GB/s, 78% of peak
- PQ2_0: 7.21 GB × 39.12 = 282 GB/s, 46%
- PTQ1_0: 5.95 GB × 32.71 = 195 GB/s, 32%
Q4_K runs close to the memory limit, so a smaller file means faster decode. Bonsai isn't limited by memory. Every token requires unpacking the trits and applying the Hadamard transform to the inputs, and that is arithmetic, not data movement. PTQ1_0 moves 17% less data than PQ2_0, but its denser packing costs more to unpack.
The model card says the same thing. PTQ1_0 is faster on Ada-generation cards and the L4, where decode is short on memory bandwidth. It loses to PQ2_0 on H100, A100 and Blackwell, where batch-1 decode is limited by instruction throughput and launch overhead. The 2080 Ti lands in the second group. [Part 12](/en/blog/why-4bit-isnt-faster-on-2080ti) found that on this card, low-bit quantization saves VRAM but not necessarily time.
## What you need: one 2080 Ti, PrismML's llama.cpp fork, and a 7.21 GB file
- **One modded 2080 Ti 22G.** The short-context peak is under 8 GB. By that math a stock 11 GB 2080 Ti should fit, but I didn't test one.
- **PrismML's llama.cpp fork**, [PrismML-Eng/llama.cpp](https://github.com/PrismML-Eng/llama.cpp), branch `prism`. I used commit `01041db` with CUDA 12.4. The build flag that matters is `CMAKE_CUDA_ARCHITECTURES=75`: the PQ2_0 and PTQ1_0 kernels compile for sm_75, the 2080 Ti's compute capability.
- **The weights:** `Ternary-Bonsai-2-27B-PQ2_0.gguf`, 7.21 GB, from [prism-ml/Ternary-Bonsai-2-27B-gguf](https://huggingface.co/prism-ml/Ternary-Bonsai-2-27B-gguf). On this card, pick PQ2_0 over PTQ1_0 for the bandwidth reasons above.
## How to build and run it: clone, compile for sm_75, download, serve
Clone the fork and build the server and llama-bench for Turing:
```bash
git clone --branch prism https://github.com/PrismML-Eng/llama.cpp prismml-llama.cpp
cd prismml-llama.cpp
cmake -B build-cuda75 -DGGML_CUDA=ON -DCMAKE_CUDA_ARCHITECTURES=75 -DCMAKE_BUILD_TYPE=Release
cmake --build build-cuda75 -j 20 --target llama-server llama-bench
./build-cuda75/bin/llama-server --version # the fork's llama-bench has no --version; check the server instead
```
Download the PQ2_0 weights:
```bash
hf download prism-ml/Ternary-Bonsai-2-27B-gguf Ternary-Bonsai-2-27B-PQ2_0.gguf --local-dir ~/models/bonsai2
```
Start the server:
```bash
./build-cuda75/bin/llama-server \
-m ~/models/bonsai2/Ternary-Bonsai-2-27B-PQ2_0.gguf \
-ngl 99 -c 16384 -np 1 -fa on --jinja \
--reasoning-effort medium \
--host 0.0.0.0 --port 8080
```
This is the exact line that produced 130/140. I sent sampling parameters with each request: temperature 1.0, top_p 0.95, top_k 20, min_p 0. The model card says the GGUF metadata carries the same defaults.
## Two blockers: stock llama.cpp, and an xhigh default that scores 116
**Stock llama.cpp won't load PQ2_0 or PTQ1_0.** It has no Hadamard runtime. Use the fork.
**Reasoning effort defaults to xhigh.** At that setting, 21 of 140 questions spent all 8192 tokens without answering, and the score was 116. With `--reasoning-effort medium`, one question hit the limit and the score was 130. The model card says `low` isn't supported and behaves close to xhigh, so use medium.
Not a blocker, but a time sink: a second card doesn't help. Tensor parallel (`-sm tensor`) hits an assertion at load, and layer split (`-sm layer`) adds only 6–7%. The deep dive explains why.
## MTP adds 15% on code and 43% on math, with a community graft and a 15-line patch
MTP is Qwen3.8's built-in draft head. It guesses a few tokens ahead, the main model verifies them in one pass, and every correct guess comes free.
The official Bonsai 2 has no MTP head. Its GGUF lacks the original model's `nextn` tensors, and PrismML's download script says there is no draft model. A community build grafts MTP back: [BoldingBuilds' abliterated (uncensored) PQ2_0-MTP](https://huggingface.co/BoldingBuilds/Ternary-Bonsai-2-27B-Abliterated-PQ2_0-MTP-GGUF).
Same card, temperature 0, median of 3 runs per workload:
| config | code (tok/s) | math (tok/s) | prose (tok/s) |
|---|---:|---:|---:|
| no speculation | 38.9 | 38.2 | 37.8 |
| MTP n=2 | 44.8 | 54.6 | 47.3 |
| MTP n=3 | 40.3 | 53.1 | 41.8 |
n=2 is the fastest: +15% on code, +43% on math, +25% on prose. Drafting more tokens slows it down. The flags are `--spec-type draft-mtp --spec-draft-n-max 2`. The fork needs a 15-line patch before it will run the MTP graph; the patch is in the deep dive.
This build scores 128/140 at medium effort, two below the original and within noise (MATH-500 −3, MuSR +1). It's an uncensored (abliterated) build.
## 262K context on one 22 GB card: q8_0 KV cache, 17,312 MiB at load
Qwen3.8-27B has 64 layers. Of those, 48 use linear attention, which keeps a fixed-size state instead of a growing KV cache. Only the 16 full-attention layers store KV. That is what lets 262K tokens fit on one card:
```bash
./build-cuda75/bin/llama-server -m -ngl 99 \
-c 262144 -ctk q8_0 -ctv q8_0 -np 1 -fa on --jinja \
--spec-type draft-mtp --spec-draft-n-max 2
```
Load peak is 17,312 MiB. Below is a real 150K-token prompt on the abliterated PQ2_0-MTP.
| | prefill | decode | peak VRAM |
|---|---:|---:|---:|
| no speculation | 315.5 tok/s | 13.1 tok/s | 17,336 MiB |
| MTP n=2 | 297.3 tok/s | 21.1 tok/s | 19,432 MiB |
Reading 150K tokens takes about 8 minutes. An fp16 KV cache would need roughly 24 GB by my estimate, so q8_0 KV is mandatory here. Long context is where MTP pays off most: decode goes up 61%.
---
## Deep dive: reasoning effort, the bandwidth math, DFlash2, and why -sm tensor asserts
You can skip this section. Everything above is enough to run the model; what follows is the full data, the verbatim errors and the commands behind each claim.
### 116 → 122 → 130: the fix was reasoning effort, not a bigger token budget
The first full run used the fork's default effort, xhigh, and scored 116/140. Of 24 failures, 21 ended with `finish_reason=length`: 15 on MuSR, 4 on HumanEval+, 2 on MATH-500. All 15 MuSR failures were still thinking when they hit the limit.
A bigger budget is the obvious fix, and it's what I tried first. I reran those 21 questions at 16384 tokens:
| bench | rerun | rescued | still truncated at 16K | wrong |
|---|---:|---:|---:|---:|
| MATH-500 | 2 | 2 | 0 | 0 |
| HumanEval+ | 4 | 2 | 2 | 0 |
| MuSR | 15 | 2 | 9 | 4 |
That brings the composite to 122/140. Doubling the budget rescued 6 of 21. The truncated reasoning wasn't looping: the last 5,000 characters had no repeated fragments. It was overthinking. On a two-choice murder-mystery question, it was checking the first letters of paragraphs for a hidden acrostic.
The model card recommends medium effort. A full 140-question rerun at medium scored 130/140, and truncations dropped from 21 to 1:
| bench | N | xhigh/8192 | medium/8192 | Q8_0 setup |
|---|---:|---:|---:|---:|
| GSM8K | 50 | 49 | 49 | 50 |
| MATH-500 | 30 | 28 | 30 | 30 |
| MuSR | 20 | 5 | 15 | 13 |
| HumanEval+ | 40 | 34 | 36 | 38 |
| total | 140 | 116 | 130 | 131 |
| group | truncated | median output tokens | p90 output tokens | median decode (tok/s) |
|---|---:|---:|---:|---:|
| xhigh/8192 | 21 | 447 | 8192 | 35.38 |
| medium/8192 | 1 | 512 | 2326 | 36.85 |
| Q8_0 setup | 0 | 522 | 2437 | 66.04 |
The medians are nearly equal. The p90 is what separates them: at xhigh, 10% of answers run into the wall.
**How I checked the flag actually applied.** The server log has no line for `--reasoning-effort`, and `/props` has no field for it. The fingerprint I used is the prompt token count. On the same question, gsm8k/895, xhigh gave `prompt_n=135` and medium gave `prompt_n=93`. The flag feeds the chat template, and nothing else in the run changes how the prompt is rendered, so the missing 42 tokens can only come from it. Reasoning length on that question came out at 286, 209 and 270 characters across three groups. At temperature 1.0 that is sampling noise, not evidence.
**Head-to-head, medium vs the Q8_0 setup:**
- both right: 126
- only Bonsai right: 4 (musr/34, musr/212, musr/0, HumanEval/76)
- only Q8_0 right: 5 (gsm8k/1059, musr/20, HumanEval/145, HumanEval/97, HumanEval/151)
- both wrong: 5
**Scoring.** GSM8K takes the number after the last `Answer:`. MATH-500 takes the last complete `\boxed{}` and judges it with math_verify 0.9.0. MuSR takes the last option letter. HumanEval+ runs evalplus 0.3.1; both the base and plus tests must pass, with a 20 s outer timeout per problem. The sampling seed is `random.Random(20260920)`. `finish_reason=length` counts as wrong, with no reruns.
### Bandwidth usage: how I computed it, and a prefill number I got wrong
The method: each generated token reads all weights once, so decode tok/s × weight file size is the bytes read from VRAM per second. Divide by 616 GB/s (352-bit × 14 Gbps).
| weights | file | tg128 (tok/s) | bytes read | of 616 GB/s |
|---|---:|---:|---:|---:|
| Q4_K | 16.8 GB (15.66 GiB) | 28.68 | 482 GB/s | 78% |
| PQ2_0 | 7.21 GB | 39.12 | 282 GB/s | 46% |
| PTQ1_0 | 5.95 GB | 32.71 | 195 GB/s | 32% |
Two more independent signals point the same way.
**Speculation gets slower as it drafts more.** DFlash2 (a separate draft model, covered in the next section) on Bonsai at n=3, 5 and 8 gave 46.3, 42.5 and 34.7 tok/s on code. In August I ran Qwen3.8-27B's own DFlash2 draft on a regular Q4 with the same sweep, and it climbed from 53.77 at n=2 to 59.73 at n=5 before leveling off. Speculation pays by verifying several tokens per read of the weights. When weight reads aren't the bottleneck, verifying n tokens just costs about n times the arithmetic.
**A regular 4-bit quant on this card is still memory-bound.** In August, same base model, same machine, pure decode: Q4 at 37.79 tok/s against Q8 at 27.80, +36%. There, smaller is faster.
**A measurement mistake I made.** I first tried prefill speed ÷ decode speed as a diagnostic and measured Bonsai's prefill at 21.2 tok/s, slower than its decode. I nearly wrote that up as proof. The probe sent the same 4,060-token prompt three times and took the median. Runs 2 and 3 hit the prompt cache and had only a few tokens left to process, so fixed overhead dragged their tok/s down, and the median landed on a cached run.
The counter-evidence was already there. Server startup plus all three requests finished within 20 s; a true 21.2 tok/s would need 191 s for one request. llama-bench measured pp512 at 691. The 150K-token prompt prefilled at 315.
If you measure prefill, use a different prompt on every run, or turn the cache off. And the ratio can't diagnose decode anyway. Prefill processes a large batch at once and is compute-heavy by nature. Bonsai's correct pp512 ÷ tg128 is 17.7×, which that diagnostic would read as memory-bound, the opposite of the other three signals.
### DFlash2 on Bonsai 2 runs, but beats built-in MTP by only 3–8%
ProCreations published a DFlash2 draft model made for Bonsai 2, [ProCreations/Ternary-Bonsai-2-27B-DFlash2](https://huggingface.co/ProCreations/Ternary-Bonsai-2-27B-DFlash2), a 2.06 GB Q8_0 GGUF. The PrismML fork can't load it:
```
done_getting_tensors: wrong number of tensors; expected 81, got 58
```
The draft is the newer generation of DFlash2, with conv and selector modules. The fork's architecture table has no entries for DFLASH_ATTN_CONV_BASE/PROJ, DFLASH_FFN_CONV_BASE/PROJ or DFLASH_SELECTOR_HIDDEN/NEXT/PREV. I had also built the two upstream llama.cpp DFlash2 PRs; they fail earlier, on the target model, because upstream has no PQ2_0 support.
What works is the runtime source shipped in the ProCreations repo, `runtime/prism-dflash2-source.tar.gz`, already patched. Build it with:
```bash
cmake -S /llama -B /llama/build -G "Unix Makefiles" \
-DGGML_CUDA=ON -DCMAKE_CUDA_ARCHITECTURES=75 -DCMAKE_BUILD_TYPE=Release \
-DLLAMA_CURL=OFF -DLLAMA_BUILD_TESTS=OFF -DLLAMA_BUILD_EXAMPLES=OFF
cmake --build /llama/build -j 12 --target llama-server llama-quantize
```
The repo lists CUDA 13.3, but `find_package(CUDAToolkit)` doesn't pin a version, and 12.4 builds fine. Without ninja installed, use the Unix Makefiles generator.
Same binary, same card, temperature 0, `-c 16384`, median of 3 per workload, on the abliterated version. All five rows ran on this binary, so its MTP n=2 row is a separate measurement from the MTP table in the first half.
| config | code (tok/s) | math (tok/s) | prose (tok/s) | acceptance | peak VRAM |
|---|---:|---:|---:|---:|---:|
| MTP n=2 | 42.8 | 50.4 | 45.4 | 60.9% | 9.3 GB |
| DFlash2 n=3 | 46.3 | 52.4 | 46.8 | 63.3% | 11.5 GB |
| DFlash2 n=5 | 42.5 | 50.2 | 44.1 | 50.3% | 11.8 GB |
| DFlash2 n=8 | 34.7 | 46.9 | 36.8 | 39.9% | 12.3 GB |
| original (not abliterated), DFlash2 n=5 | 47.3 | 49.0 | 40.9 | 50.7% | 11.8 GB |
The best DFlash2 setting, n=3, is only 3–8% ahead of built-in MTP. It costs 2.2 GB more VRAM and an extra draft file. Abliteration barely moves acceptance: 50.3% against 50.7% at n=5. Not worth it.
The same family of draft on the 29 GB FP8 model across two cards is a different story, because there the weights really are memory-bound. That is [part 20](/en/blog/fastllm-dflash2-dual-2080ti).
### Why -sm tensor asserts on two cards: 2560 ÷ 1024 = 2.5
With two cards and `-sm tensor`, the first error is:
```
llama_params_fit is not implemented for SPLIT_MODE_TENSOR
```
With `--fit off`, the real one appears:
```
ggml-backend-meta.cpp:1086: GGML_ASSERT(split_state.ne[j] % div == 0) failed
```
I first suspected the hybrid attention. But part 14's Q8_0 has the identical architecture to Bonsai 2's MTP version (both `qwen35`, 866 tensors, identical SSM parameters), and it splits fine. The only difference is Bonsai's extra GGUF metadata:
```
prism.hadamard.block_size = 1024
prism.hadamard.transform = normalized-sylvester-walsh-hadamard
prism.hadamard.axis = input-last-dimension
prism.hadamard.weight_names = 401 weights
```
The Hadamard transform acts on the input's last dimension in blocks of 1024. The hidden width is 5120. Split across two cards, that's 2560 per card, and 2560 ÷ 1024 = 2.5, so one block gets cut in half. `split_state` is tensor parallel's own bookkeeping, and it requires each card's slice to be divisible by the block size. This blocks MTP and DFlash2 alike; it doesn't depend on the speculation method.
`-sm layer` runs. It's a pipeline: one card computes the first half of the layers, the other computes the second half, and only one card works at a time. DFlash2 n=3 gave 49.0 / 55.4 / 50.1 tok/s and MTP n=2 gave 46.0 / 53.7 / 48.6 (code / math / prose), 6–7% over one card. The second card adds capacity, not compute.
### The 15-line MTP patch for commit 01041db
At commit 01041db, the fork's main graph un-rotates the embeddings right after the lookup. The MTP graph has its own embedding lookup and skips that step, so `llama_verify_hadamard_graph` rejects the context. The patch goes in `src/models/qwen35.cpp`:
```cpp
#include "llama-impl.h" // llama_mul_mat_hadamard
// in graph_mtp, right after tok_embd = ggml_get_rows(...):
// a Hadamard-latent embedding table stores rotated rows; restore the
// primal basis right after the lookup: h = s * (H z). The main graph does
// this in llm_graph_context::build_inp_embd(); this graph has its own lookup
// and must do the same or llama_verify_hadamard_graph rejects the context.
if (hadamard_inverses) {
const auto it = hadamard_inverses->find(tok_embd_w);
if (it != hadamard_inverses->end()) {
tok_embd = llama_mul_mat_hadamard(ctx0, tok_embd, it->second.rot);
if (it->second.signs) {
tok_embd = ggml_mul(ctx0, tok_embd, it->second.signs);
}
}
}
```
After patching, `--version` still reports commit 01041db99. Keep your own record of which binary is patched.
### Bonsai v1's dspark draft: 1.57× on arithmetic, 0.90× on Chinese
Bonsai 2 has no draft model. The previous Ternary-Bonsai-27B (v1) has one: a dspark drafter from the DFlash family, merged into upstream llama.cpp on 2026-07-28. It ships as bf16 at 7.29 GB. I dropped the shared tensors and quantized it to Q4_0, which brought it to 632 MB. Same server, same card, temperature 0, median of 3:
| prompt | no spec (tok/s) | dspark (tok/s) | speedup | acceptance |
|---|---:|---:|---:|---:|
| EN quicksort | 41.8 | 53.3 | 1.28× | 0.57 |
| zh-TW 300-character explanation | 41.2 | 36.9 | 0.90× | 0.31 |
| EN car-chase arithmetic | 40.7 | 63.9 | 1.57× | 0.74 |
The official claim is "lossless 1.34×". My three-prompt average is 1.25×, and the Chinese prompt got slower (0.90×).
At temperature 0, the reasoning with and without speculation diverged around token 600, because batch verification's numerics flip an argmax. In llama.cpp's implementation, "lossless" does not mean byte-identical.
The draft-free `ngram-simple` made zero proposals on all three real prompts, for 1.00×. Reasoning prose has no repeated spans for it to grab.
### Not tested yet
- A 140-question eval on the 5.95 GB PTQ1_0. It should match PQ2_0; I haven't measured it.
- A stock 11 GB 2080 Ti.
- Vision (mmproj).
- In an early smoke test, a zh-TW answer leaked one simplified-Chinese character, and the reasoning was entirely in simplified Chinese. I can't pin that on quantization without running the same prompt on unquantized Qwen3.8-27B, which I haven't done.
---
**Also in this series:**
- [#14 Two modded 2080 Tis running Qwen3.8-27B with llama.cpp tensor parallel](/en/blog/qwen38-dual-2080ti-tensor-parallel)
- [#12 Why isn't your 4-bit quant faster on a 2080 Ti?](/en/blog/why-4bit-isnt-faster-on-2080ti)
- [#20 FastLLM + DFlash2 on two 2080 Tis](/en/blog/fastllm-dflash2-dual-2080ti)
---
# [LLM Deep Dive] A quantization lab: what quantization is, how it works, where the error comes from
URL: https://ai-muninn.com/en/blog/quantization-lab
Date: 2026-09-20
Series: LLM Deep Dive (Part 6)
[A quantization lab](https://model.ai-muninn.com/en/quantization/): pick INT8, FP8, INT4 or FP4, pick one of four weights, and watch it go through scale, encode, store, reconstruct. Two findings. With `-15.875` in the group, one INT4 step spans 2.2679, so `0.375` and `-0.875` both round to **0** — two of four weights gone. And the weight that sets the scale comes back as **-15.874999523162842**: `15.875 / 7` is not representable in FP32, so the ruler is quantized too. How real quantizers fight outliers is Part 1's subject, not this one.
## Introduction
Quantization fits on one line, and the [ONNX QuantizeLinear spec](https://onnx.ai/onnx/operators/onnx__QuantizeLinear.html) writes it out: divide the value by a scale, round to the nearest representable level, clamp. Dequantization multiplies back. The spec carries a `zero_point` offset as well; everything here is symmetric, so that term is 0 and never shows up. Nothing in there is hard to read.
Naming *where* the error enters is harder. Rounding is the obvious answer, and it is incomplete. The part that gets skipped is the scale — where it comes from, and what it costs.
So I built something clickable: [model.ai-muninn.com/en/quantization/](https://model.ai-muninn.com/en/quantization/). Pick a format, follow one weight through four steps, read the error at the end. What follows is what the lab shows: what quantization is, how it runs, and the three places the error comes from — two of which I had not understood before building it.
## What quantization is: fewer bits holding the same numbers
Model weights are floating point. In BF16 each one takes 16 bits. Quantization stores the same numbers in fewer bits — 4 bits each at INT4.
The lab does that accounting in groups of 64 weights:
| | Storage |
| --- | ---: |
| 64 BF16 weights | 128 bytes |
| 64 INT4 weights | 32 bytes |
| + 1 shared scale (FP32) | 4 bytes |
| **Total** | **36 bytes** |
A 71.9% saving. The lab's cube is the same arithmetic in 3D: change format and its 64 blocks re-encode into a smaller volume.
The cost sits in the bit count. Four bits give you 16 combinations, and the symmetric range used here spans -7 to 7 — 15 levels, trading -8 away for symmetry around zero. A weight that used to be any float now has to land on one of those 15. **Anything that does not land on one gets moved to the nearest.**
## How to use it: pick a format, follow one weight, see where it breaks
The page opens on BF16 and nothing happens. That is deliberate. BF16 is the format the weights are already in, so there is no scale to compute and nothing to encode.
Click INT8, FP8, INT4 or FP4 and a four-step lesson appears:
1. **Compute the group's scale.** The group's maximum absolute value divided by what the format can hold.
2. **Convert the weight into something the format can hold.** An integer code, or the nearest level the format's bit layout allows.
3. **Show what is actually stored.** Not the number you typed — the code, plus the one scale the group shares.
4. **Reconstruct and compare.** Multiply the stored code back by the scale, put the result next to the original, and read the difference.
**Error source one is that rounding**: a weight that does not land on a level gets moved to the nearest one. Everyone knows that one. The next two sections are the other two, and I had not thought about either before building this.
Four number buttons — `0.375`, `-0.875`, `4.25`, `-15.875` — switch which weight is traced. All 64 teaching weights share one scale, which is what makes the buttons worth pressing: you are not changing the setup between clicks, only which weight you follow through it.
First run: INT4, trace `0.375`.
## Error source two: how coarse a step is, decided by the group's largest value
The teaching group holds four values: `-15.875`, `-0.875`, `0.375` and `4.25`. The first is an order of magnitude above the rest.
INT4 has seven steps each way, so the scale is the group's maximum absolute value over that limit:
```
scale = 15.875 / 7 = 2.2679
```
One step spans 2.2679. Run `0.375` through it:
```
0.375 / 2.2679 = 0.165 -> rounds to 0
```
`-0.875` does the same. Two of the four values are gone.
Take `-15.875` out of the group and nothing about `0.375` changes. The group max becomes 4.25, the scale becomes 0.6071, and `0.375` reconstructs as 0.6071 — still wrong, but no longer zero. What changed was not the weight. It was which group it shares.
Outliers are the subject of Part 1. [What quantization algorithms actually do](/en/blog/llm-deep-dive-quantization-algorithms) covers why they are the enemy, and how K-quant super-blocks and TurboQuant's rotation each handle them. I am not re-deriving that here. What the lab adds is that you can click it and watch the weight go.
## Error source three: the scale is an approximation too
A weight sitting exactly on a tick should reconstruct perfectly. And the group's maximum should be the safest value in the set: it defines the scale, and its code is exactly the format limit.
Pick INT4 and trace `-15.875`. It reconstructs as `-15.874999523162842`, off by `4.77e-7`.
The rounding step is not where that came from. `-15.875 / 2.267857... = -7`, exactly, with nothing to round. The error is in the ruler. `15.875 / 7` cannot be represented in FP32, so the scale that actually gets stored is `2.267857074737549`. Multiply the code `-7` by that number and you cannot land on `-15.875`, because the number you are multiplying by is not `15.875 / 7`.
The same weight shows the same `4.77e-7` under FP8 and FP4.
The magnitude is too small to matter for anything. What it corrects is the mental model: rounding is not the only source of error. The ruler used to reconstruct has itself been quantized.
## What "reconstruct" actually means at inference
Step 4 is called reconstruction, which invites a fair question. If every use of the model restores the weights to BF16, don't the savings come straight back?
No.
With weight-only quantization the weights do get converted back to floating point for the multiply. What does not happen is a full BF16 copy of the model being built first. Dequantization is fused into the matmul kernel and runs tile by tile, so the complete BF16 weight tensor never exists in memory at once. The capacity and bandwidth savings hold at inference time.
This path shows up in the performance posts on this site without being explained as a concept. The line `NVFP4 weights → Marlin dequant → BF16 → BF16 GEMM` in [the NVFP4 Triton patch post](/en/blog/dgx-spark-nvfp4-fp8-triton-patch) is exactly it: dequant is a stop inside the kernel, not a pass that unpacks the whole model.
So step 4 in the lab is an instrument. You need the original and the restored value side by side or there is no error to measure at all. It is not a cost paid per token.
(The page quantizes weights only. Activations stay floating point, and quantizing those too is a separate topic for another time.)
## What you can cite, and what is only illustrative
Citable, because they are computed:
- the scale
- the reconstructed values
- the error
- the bytes
The byte math is in the table at the top, and the shared scale is already counted in it.
Illustrative only, not to be quoted as measurement:
- box sizes do not track tensor dimensions
- cache cell counts are not measured
- animation speed is unrelated to real speed
- the colored routing lines come from a fixed seed
Where a number is not verified the lab prints "not verified" rather than 0, because a 0 reads like a measurement someone took.
## Deep dive: why these numbers can be trusted
Skip this section if you only want to use the lab.
`node verify.cjs` runs 53 checks, and they test data consistency rather than looks:
- every finite FP4 E2M1 encoding must match
- FP8 E4M3FN subnormal and NaN encodings must match
- ties-to-even must hold on both sides of zero
- the scale must use its stored FP32 value, not the theoretical one, when picking integer codes
That last check is where the `4.77e-7` above comes from. Let the tests accept the theoretical scale and the error disappears from the page — and what disappeared would be something real.
One coincidence in the teaching group is worth knowing before you read the INT8 tab. INT8 shows exactly zero error on all four values, because 15.875 / 127 = 0.125 exactly and all four values are multiples of 0.125. The lab labels this as deliberately chosen teaching data. It must not be read as INT8 being lossless.
## Where to click first
Open [the lab](https://model.ai-muninn.com/en/quantization/), pick INT4, and trace `0.375`. Watch it become 0 at Step 2.
Then trace `-15.875`, the weight that sets the scale for all 64. Its integer code is -7, the INT4 limit, and it still comes back as -15.874999523162842.
---
# [LLM Deep Dive] What actually happens inside one transformer layer — four real models, four data flows
URL: https://ai-muninn.com/en/blog/model-anatomy-explorer
Date: 2026-09-16
Series: LLM Deep Dive (Part 5)
[model.ai-muninn.com](https://model.ai-muninn.com/en/) draws four open models as a cube you pull apart: pick a model, expand it into its decoder layers, click a layer, click a region. Two things it makes hard to ignore. Qwen3-30B-A3B carries **48 x 128 = 6,144 expert FFNs**, all resident inside its 61.06 GB BF16 total, with 8 used per token. DeepSeek-V4.1-Flash has 40 layers and only **4 of them** — 3, 9, 15, 21 — produce the shared compressed KV that 34 layers read. Caveat: parameter and layer counts come from pinned configs, but box sizes, cache cells and routing lines are drawn for teaching, not measured.
## Introduction
I can recognise a bicycle from across the street. Ask me to draw one from memory and the chain ends up somewhere no chain can go. Transformer layers are like that. Everyone has seen the block diagram. Very few people can draw where the residual actually reconnects.
So I built a site that draws it: [model.ai-muninn.com](https://model.ai-muninn.com/en/). Four open models, no login, bilingual. This article is about what it shows and how to read a model with it.
## How to use it: pick a model, expand the layers, click a region
The model picker sits top left. Four models, each with its layer count on the card:
| Model | Layers | Type |
|---|---:|---|
| Qwen3-30B-A3B | 48 | MoE |
| Qwen3-8B | 36 | Dense |
| Qwen3.8-Flash-Next | 48 | hybrid attention |
| DeepSeek-V4.1-Flash | 40 | 20 causal encoder + 20 decoder |
Then three clicks:
1. **Click the cube.** It pulls apart into a stack of slices. The slice count is the decoder layer count, so Qwen3-8B gives you 36 slices and DeepSeek-V4.1-Flash gives you 40.
2. **Click again to enter one layer.** Inside, the layer is broken into its functional regions rather than one box labelled "decoder layer".
3. **Click any region.** The right panel streams an explanation of what that region does, its parameter count, and the BF16 equivalent in GB.
A layer stepper sits next to the model, so you can hold one region in view and walk forward through the stack watching it change.
Start with Qwen3-30B-A3B and walk one layer end to end. It is the model where the count that surprises people is largest.
## One layer is six steps, not three
Most diagrams show three things: Attention, FFN, an arrow. The tool draws six, because six is what executes:
```
Input -> Norm 1 -> Attention -> +① -> Norm 2 -> MoE/FFN -> +② -> next layer
```
The two nodes usually left out are `+①` and `+②`, and they are not the same operation run twice. `+①` adds Attention's output back onto the copy of the data saved *before* Norm 1. `+②` adds the MoE output back onto the copy saved *before* Norm 2. Those two saved copies hold different data, because Attention and `+①` both ran between them.
The figure makes the offset visible: the two faint bypass lines leave the main path at different points. Click either `+` node on the site and the panel names which copy that node adds back.
## Two Norms per layer, 97 weight sets in a 48-layer model
Norm 1 and Norm 2 are two separate clickable boxes, and each reports its own parameter count: 2,048 each in Qwen3-30B-A3B, 4,096 each in the dense Qwen3-8B. They are two independent sets of RMSNorm weights, and they receive different data because Attention and the first residual add sit between them.
Both are instantiated per layer. Across 48 layers that is 96 sets of RMSNorm weights, not one normalization recipe reused. The Final Norm outside the layer stack is a third role with its own count, which brings the model to 97 weight sets.
## 48 x 128 = 6,144 expert FFNs, 8 of them per token
Open Qwen3-30B-A3B, step into a layer, click the Experts region. That layer holds 128 experts and routes top-8 per token. Across 48 layers: 48 x 128 = 6,144 expert FFNs, all resident in the file. The model totals 30,532,122,624 parameters, 61.06 GB in BF16, and on any given token most of that 61 GB is experts the Router did not select.
Two things about that region before you cite it. The large grid in the UI does not map one cell to one expert, and the 8 colored markers on it are a routing sample for that layer rather than a trace. The parameter accounting is real: the number printed on the Experts region is the weight total for that layer's 128 experts, derived from [the published config](https://huggingface.co/Qwen/Qwen3-30B-A3B/blob/main/config.json).
Experts are not pre-assigned by subject. There is no math expert and no translation expert. Each one is trained, and the Router scores them against the intermediate data arriving on this pass.
## Weighted merge, then +②: two nodes, 0 trainable parameters
The tool keeps these apart, in this order. The weighted merge multiplies each of the 8 expert outputs by the proportion the Router assigned it and sums them into one new intermediate representation. `+②` then adds that onto the copy saved before Norm 2.
Collapse them into one node and the question "where do the proportions come from" has nowhere left to live. They are this pass's data from the Router, not weights owned by the merge node. Both nodes report 0 trainable parameters, and 0 parameters is not free: the multiply runs, the add runs, and the intermediate has to be stored.
## DeepSeek-V4.1-Flash: 4 of 40 layers produce the shared KV
The backbone is 40 layers, 20 causal encoder plus 20 decoder. Step through them with the Attention region open and the same region keeps changing shape, because those 40 layers split four ways by where their KV and their index come from.
Read this part carefully, because the name invites the wrong reading: **every backbone layer still builds its own local-window KV. That is not shared.** The four layer types differ in how they handle the *shared compressed KV*.
| Kind | Layers | Shared compressed KV | Index |
|---|---:|---|---|
| SWA | 2 | none, local window only | none |
| Full | 4 | produces it | builds its own |
| Reindex | 4 | takes another layer's | recomputes its own |
| Reuse | 30 | takes another layer's | takes another layer's |
Only 4 of 40 layers produce the shared compressed KV, at one-based positions 3, 9, 15 and 21. Thirty-four layers read it — 30 take the index along with it, 4 recompute their own — and the 2 SWA layers never touch it.
The Reindex layers sit at 25, 29, 33 and 37. They take the shared compressed KV and recompute their own index, which means KV and index have separate lifetimes in this model. Step to one of those layers and the KV-building part drops out of the diagram, leaving only the index recompute.
You cannot tell which behavior a layer uses from the config field names alone. It comes out of `Attention.__init__`, `_compress_kv`, `_compress_topk_idxs` and `Indexer` in `inference/model.py` at the pinned revision. `_compress_topk_idxs` is the function that decides recompute versus reuse.
## Qwen3.8-Flash-Next: 36 Gated DeltaNet layers and 12 QSA
48 layers, and not one attention type repeated 48 times. The pattern is 3 Gated DeltaNet layers then 1 QSA layer, repeated 12 times: layers 1, 2, 3 are GDN, layer 4 is QSA, layers 5, 6, 7 are GDN, layer 8 is QSA, and so on to 36 GDN plus 12 QSA.
Step forward a few layers with the Attention region open and the diagram swaps. GDN runs old state, update, new state, readout, and the new state carries forward to the next token. QSA uses an indexer to pick a small subset of historical KV and reads only those.
## What you can cite, and what is only illustrative
Citable, because it is derived from pinned official configs:
- parameter counts
- layer counts
- expert counts and top-k
- the BF16 equivalent size
The two original Qwen3 models are the strongest case here: their published totals reconstruct exactly from per-layer parameters times layer count, plus Embedding, plus Final Norm, plus Output.
Illustrative only, and not to be quoted as measurement:
- box sizes do not track tensor dimensions or parameter ratios
- cache cell counts are not measured
- animation speed is unrelated to real speed
- the routing lines are a fixed-seed teaching illustration
One item deserves its own line. Which 8 of 128 experts the Router actually picked can never be drawn accurately. A config gives you how many exist and how many are chosen; which ones depends on live intermediate data, and only an inference trace tells you that.
Where a number is not verified the site prints "not verified" instead of 0, because a 0 reads like a measurement someone took.
## Deep dive: why these numbers can be trusted
Skip this section if you only want to use the site.
Every model is read at a pinned revision, not at `main`:
- Qwen3.8-Flash-Next config: `de4b8e4d43b917e7706784d8bb445c9af86a3540`
- DeepSeek-V4.1-Flash config: `dba1be0a40aa45a94ad051997016db3960a90277`
Each lives in its own HuggingFace repo. The Flash-Next implementation is pinned to Transformers commit `bd15bc95a89e728bbc1224084eb3b5829428c353` — that is a commit, not the `v4.51.3` tag, and the two are different objects. The two original Qwen3 models use their official configs plus [the `qwen3_moe` implementation at the `v4.51.3` tag](https://github.com/huggingface/transformers/blob/v4.51.3/src/transformers/models/qwen3_moe/modeling_qwen3_moe.py).
The reason for pinning is mundane. Configs change upstream. Reading `main` would silently redraw the diagram with nobody noticing.
`node verify.cjs` runs 35 checks, and they test data consistency rather than looks:
- the two original models' parameter totals must reconstruct exactly
- every visible region must have an explanation in every locale
- layer navigation must advance exactly one layer, and only the last layer may reach Output
- the merge and residual nodes must never be counted into any weight subtotal — their parameter field is 0, and the test stops that 0 being added into any subtotal
What is not done: the newer two models' full parameter counts are unknown or partial. Lookup, vision and MTP branch tensors are not individually verified, so the UI shows the official approximate figure or "not verified" rather than passing a known subtotal off as an exact total. And the BF16 equivalent is parameter count times 2 bytes in decimal GB — not a quantized download size, and not runtime memory, since it excludes KV cache, activations and workspace.
The site itself was written by Codex (`gpt-6-astra`), 27 commits in one day, v1 through v16.
## Where to click first
Open [model.ai-muninn.com](https://model.ai-muninn.com/en/), pick Qwen3-30B-A3B, and walk one layer end to end — Norm 1, Attention, `+①`, Norm 2, Experts, weighted merge, `+②` — watching that `+①` and `+②` add back two different copies.
Then switch to DeepSeek-V4.1-Flash and step to layers 3, 9, 15 and 21. Those are the only four of the 40 that produce the shared compressed KV.
---
# [DGX Spark] Two hard power-offs, reproduced on purpose — the fix, and why we turned it off again
URL: https://ai-muninn.com/en/blog/gx10-thermal-hard-poweroff
Date: 2026-09-14
Series: DGX Spark (Part 48)
My GX10 — an ASUS Ascent box on the same GB10 part as a DGX Spark — cut power twice in one day, both times on the second back-to-back native MiniMax-H3 run at 1344x768. Not just a crash: thermal protection pulled the plug before the OS got a word out. I reproduced it on purpose with the thermometer outside the machine: uncapped, run two died at **156 s**; capped with `nvidia-smi -lgc 300,2200`, the same run finished at **251.302 s**. Time at or above 95 °C went from **12% of the run to 0%**, peak power from **93.2 W to 74.0 W**. Capping is a workaround, not a fix — the defect stays. Caveat: `nvidia-smi` reads 8-15 °C low and will tell you the machine is fine.
## Preface
The previous article has one cell I could not fill: a second consecutive native run, uncapped. Every time I tried, the machine turned itself off.
Not a hang. Not a kernel panic. Off. Someone walks over to the desk and presses the button.
That happened twice in one day, so I stopped benchmarking and went after it instead. What follows is not a new bug. It is a known defect that other people had already reported, that had a community fix sitting on GitHub, and that my own second machine had been quietly mitigating for two months. So I reproduced it deliberately, with the instrument outside the machine, and what follows is the capped-versus-uncapped comparison that came out of it.
## The machine died twice, both times on the second back-to-back native run
The job was video-generation benchmarking on an ASUS Ascent GX10 — GB10 chip, 121 GiB of unified memory. MiniMax-H3 generating natively at 1344x768, about 200 s a run, GPU pinned at full load from the first second to the last. This was the control arm for the two-stage pipeline in the previous article.
The second failure has the cleanest timeline, because both runs happened inside one ComfyUI process:
```text
15:41:31 run 1 starts
15:45:20 run 1 finishes, 201.852 s — machine alive
201 seconds of unbroken full load
15:45:20 run 2 starts immediately, no gap
15:46:50 power gone — 90 seconds in
```
Run one survives. Run two, starting from a board that never got to cool down, does not.
## Five places that should have held evidence were empty, and that is the answer
I went looking for a cause the normal way, and came back with nothing five times:
1. `journalctl -b -1` stops **mid-line** on an ordinary entry. The last record is a routine tailscaled session close.
2. `/sys/fs/pstore/` is empty.
3. The SBSA hardware watchdog (`RuntimeWatchdogSec=10s`) never fired. There was no auto-reboot between the two boots.
4. The peer machine, on a direct ConnectX-7 link, saw both mlx5 ports go `Link down` **in the same second**. Zero AER, zero driver reset.
5. RJ45 shows `Link detected: yes`, and roughly 740 Wake-on-LAN magic packets did nothing.
Five dead ends, all consistent with one explanation: the power went before anything could be written down. journald stops mid-line. pstore never gets written. The watchdog cannot reboot a board with no power in it. The NIC drops carrier in the same instant.
Be careful with the word *because* here. These observations are consistent with that story rather than proof of it. A watchdog can also stay quiet because systemd is still feeding it, and a NIC losing link does not necessarily raise a PCIe AER event at all — I can say I saw no AER, not that there was no time to raise one. What actually points at power is having to walk over and press the button.
**It is not a crash. There is no power.** Once you accept that, the missing evidence stops being frustrating and starts being the diagnosis.
## Reproducing it needed the thermometer to sit outside the machine
The lethal combination was already obvious from two identical failures: native 1344x768, two runs back to back with no gap. Run one survives, run two dies around 90 s in.
The real problem was different: **neither failure left a curve.** A hard power-off eats whatever has not been flushed to the machine's own disk, and the unflushed part is exactly the part worth looking at. Anything I logged locally would die with the machine.
So the instrument went outside. Sampling every 2 seconds, streamed live over ssh to a MacBook:
```text
/sys/class/thermal/thermal_zone*/temp — package temperature
nvidia-smi --query-gpu=clocks.current.sm,power.draw,utilization.gpu — clock, watts, load
```
When the box dies, the samples are already off it.
## On this box nvidia-smi read 8 to 15 degrees low, and it would have told me the machine was fine
This one deserves to stand on its own, because it nearly cost me the whole investigation.
**On this machine the `nvidia-smi` temperature read 8 to 15 degrees below the ACPI zone I was sampling.** When `nvidia-smi` said 75-84 °C, that zone was already sitting at 92-98 °C. Thread 379195 records a comparable gap, 84 °C against 93.1 °C, so it is not unique to my box — but I have not established it as a rule for the part, and `thermal_zone*` is a set of sensors rather than one package temperature, so check which zone you are reading.
I had planned to watch `nvidia-smi`. It would have shown me the eighties on a machine that was about to cut its own power, and I would have written down "it is not hot" and gone looking somewhere else entirely. Read `/sys/class/thermal/thermal_zone*/temp`. Not the GPU tool.
## Capped at 2200 MHz, the run that died at 156 s finished at 251 s
Four runs, one machine, one workflow, one day. Two uncapped, two with the GPU locked to 2200 MHz.
| | uncapped | capped at 2200 MHz |
|---|---|---|
| measured clock under load | 2450, self-throttling to 1475 | 2164-2184 throughout |
| run 1 (cold), peak acpitz | 95.5 °C | 88.7 °C |
| run 2 (warm), peak acpitz | 96.0 °C | 91.1 °C |
| run 2, share of time at or above 95 °C | 12% | 0% |
| peak power draw | 93.2 W | 74.0 W, down 21% |
| run 1 | survived, 226 s | survived, 246.627 s |
| **run 2 — the killer** | **DIED at 156 s** | **survived, 251.302 s** |
The last sample that made it off the machine before it died:
```text
10:34:54 acpitz=92.2 GPU=84 util=96% 77.5W clk=2385
```
And then nothing. No shutdown line, no final flush, no next sample two seconds later.
Note the two temperature columns on that last row: `acpitz=92.2` while `nvidia-smi` reports 84. That is the 8-to-15-degree gap, caught in the act, on the sample immediately before the power went.
## Two flags get you through the run. They do not fix the machine
```bash
sudo nvidia-smi -pm 1 && sudo nvidia-smi -lgc 300,2200
```
Default boost on this part is about 2418. Capped at 2200, the same back-to-back pair that killed the machine completes.
The temperature tells it best. Peak goes from 96.0 °C to 91.1 °C, and **the share of the run spent at or above 95 °C goes from 12% to zero**. The run that killed the machine at 156 s now finishes at 251.302 s. Peak power drops from 93.2 W to 74.0 W at the same time.
**This is a way around the defect, not a repair.** It is still in the machine. One NVIDIA forum thread title says, in so many words, that it persists after a full platform firmware update; another ends in a fieldiag FAIL and an approved RMA. Firmware is not a settled answer either way — a third thread reports its power-offs stopping after an EC and SoC update. Capping just slows the heat down enough that it never reaches whatever the controller is watching. What you buy is a run that finishes, not a machine that is fixed.
(It costs around 9%: within one session the uncapped first run was 226 s against 246.6 s capped. Measure that on your own workload rather than borrowing mine — there is a section below on why.)
**The trap: do not read Applications Clocks or Max Clocks to see whether the cap took.** They still report 2418 and 3003. Neither moves when you lock, because neither is the ceiling you just set — one is the application-clock setting, the other the design maximum. What you want is the current clock under load, which `nvidia-smi -q -d CLOCK` does report, or `--query-gpu=clocks.current.sm`. I looked at those two unchanged numbers and nearly concluded the lock had silently failed.
## We turned the cap off again, because the cost depends on the shape of the workload
Twenty percent is not a constant. It is what you pay when your workload never lets go of the clock ceiling.
| workload | uncapped | capped 2200 | cost |
|---|---|---|---|
| native H3 1344x768, 4 steps | 226 s | 246.6 s | 9% |
| two-stage pipeline (warm) | 66.1 s | 70.4 s | 6% |
Native runs 200 seconds unbroken with every one of them pressed against the ceiling. The two-stage pipeline breaks for VAE decode, a handoff and a re-encode, so a smaller share of it is capped in the first place.
That same difference explains which runs killed the machine. **The two-stage pipeline ran four times on this box without a single failure, at a memory peak of 104 GiB — higher than the 74 GiB in use during the crashes.** Uncapped, one warm two-stage run takes 66.1 s and peaks at 74 °C, nowhere near the 95-plus of the failures. It never sits at the top long enough.
So the cap is off on this machine now, because it will not be running large native video jobs again. The unit file stays where it is in `/etc/systemd/system/`, and one line brings it back:
```bash
sudo systemctl enable --now gb10-clock-cap.service
```
## Cap it if your workload holds full load for minutes; skip it if your pipeline breathes
If you run jobs that stay at full load for two or three hundred seconds without a break — native video generation, long training steps, a power stress test — cap the clock. The 9% is cheap next to walking over to press a button, and cheaper still than the run you lose.
If your pipeline has natural interruptions in it, you may never hit this at all, and you do not need to pay for insurance against it. Measure your own longest unbroken stretch of full load before you decide.
---
## Deep dive: not memory, not the chip failing to protect itself, and not missing firmware
Everything above is what you need to run the machine. This part is the three explanations I ruled out, the two wrong turns I took, and where the fix had already been sitting.
### 104 GiB survived and 74 GiB died, so memory is not the variable
The obvious first guess on a 121 GiB unified-memory box is that something ran out of room.
| what ran | longest unbroken full load | memory peak | outcome |
|---|---|---|---|
| two-stage, cold | ~110 s | — | survived |
| two-stage, warm | ~67 s | 104 / 121 GiB | survived |
| native, single run | 201.8 s | 74 / 121 GiB | survived, barely |
| native, second consecutive | no gap | 74 / 121 GiB | died |
**The 104 GiB run survived. The 74 GiB runs are the ones that died.** Whatever decides the outcome, it is not how much memory was in use — the heaviest memory load on the machine is also the one that never failed. What separates the rows is the length of the unbroken stretch at full load.
### The chip was already throttling below our cap, and it died anyway
The second guess is that the chip failed to protect itself and a cap does the protecting. The samples say otherwise: uncapped, it was already throttling, and further down than we ever locked it.
| | uncapped run 1 | uncapped run 2 | capped (both runs) |
|---|---|---|---|
| clock min / median | 1735 / 2340 | 1475 / 2288 | 2164 / 2171 |
| share of samples below 2200 | 13% | 26% | — |
It went down to 1475, well below our 2200 cap, and cut power anyway. And it throttled *harder* on run two than run one — 26% of samples below 2200 against 13% — which is the chip reacting to a board that was already hot.
The difference is timing, not depth. Dynamic throttling reacts after things are hot; by the time the clock comes down, the heat is already in the board. A static cap never makes that heat in the first place.
**Be careful how far you push that.** The only claim the data supports is: hot enough for long enough and it cuts power. It does not support a threshold. Death came at 92.2 °C, the machine sat on a plateau between 89 and 96 °C for minutes, and run one touched 95.5 °C and lived. Anyone quoting you a magic number, me included, is reading more out of this curve than is in it.
One more thing worth reading off the capped runs: **there is no throttling at all.** Cold and warm capped runs have identical clock distributions across all four statistics — min, p5, median and max. Thermal throttling would put the hotter run lower; it does not. Sitting at 2164-2184 just under a 2200 cap is clock binning, not the chip pulling back.
### Two wrong turns I took
**One: I blamed the kernel first.** I checked `6.17.0-1032-nvidia` and driver `580.173.02`, found both current and known-good, and noted that my second machine on the same kernel was fine. Clean reasoning with a hole in it: the second machine was idle. An idle machine on the same kernel proves nothing about that kernel under load. I was comparing a machine that was working hard against one that was doing nothing and calling it a controlled comparison.
**Two: I nearly used the wrong thermometer.** The `nvidia-smi` gap above. Planning to watch the tool that read 8 to 15 degrees low here, on a problem that is entirely about temperature.
### Firmware is current, and a forum thread title is itself the negative result
```text
SBIOS GX10DGX.0105.2026.0505.1153 (ASUS ships 0105 after 0104)
EC fwupdmgr reports current
Model ASUSTeK GX10 (ASUS Ascent GX10), not an NVIDIA FE, so warranty goes through ASUS
```
My SBIOS is the version ASUS ships after 0104, and `fwupdmgr` says the EC is current, so updating firmware was not going to be the answer on this box.
The wider evidence on firmware is split, and I had only read half of it. One thread puts its negative result in the title: ["hard power off under sustained GPU load at 90W — persists after full platform firmware update"](https://forums.developer.nvidia.com/t/hard-power-off-under-sustained-gpu-load-at-90w-persists-after-full-platform-firmware-update/378315). But 377365 reports the opposite outcome — after an EC and SoC firmware update its hard power-offs stopped, and PowerStress ran to completion, failing on thermals instead. So "firmware does not fix it" is not settled. It did not fix mine.
### The fix already existed, and it was in my own house
This is not a new problem. The community reports predate mine:
- [Hard freezes under sustained inference](https://forums.developer.nvidia.com/t/dgx-spark-hard-freezes-under-sustained-few-minutes-inference-powerstress-thermal-failure-support-portal-unavailable/379195) — same driver 580.173.02, also running MiniMax-H3 inference; temperatures climbed to the levels they record within about two minutes and the machine then hard-froze. A freeze, not a power cut — a different failure from mine.
- [partnerdiag powerstress reproducibly hard-powers off the box](https://forums.developer.nvidia.com/t/dgx-spark-gb10-partnerdiag-powerstress-reproducibly-hard-powers-off-the-box-acpitz-88-97-8-c-in-5s-all-other-field-tests-pass/377365) — acpitz climbing from 88 to 97.8 °C in five seconds.
- [fieldiag powerstress FAIL, RMA approved](https://forums.developer.nvidia.com/t/dgx-spark-fieldiag-powerstress-fail-mods-020000600139-rma-approved-requesting-advance-replacement/372145).
And a fix already existed on GitHub: [tonyd2wild/dgx-spark-hard-poweroff-fix](https://github.com/tonyd2wild/dgx-spark-hard-poweroff-fix).
Here is the uncomfortable part. That author is also the source of the TP=2 serving recipe I have been running for weeks. His repo had been sitting at `~/src/tonyd2wild-nvfp4/` on our machines for two months.
It gets worse. The systemd unit on our **second** machine has carried this description since the day it was written:
```text
Description=GB10 GPU clock cap (2200 MHz)
— mitigates the EC hard power-off under sustained load
```
That second machine has never failed. I read that line for the first time after the first machine had already died twice.
So let me be honest about what this article actually contributes. Not "we found a new problem". We independently reproduced a known defect and ran a capped-versus-uncapped comparison on one machine, one workflow, one day.
I had wanted to claim more than that — that I supplied the curve every other report was missing. Checking before publishing, thread 377365 already describes an external 1 Hz thermal sampler and publishes timestamped readings from before its power-off. So that claim is gone. The comparison is what is left, and it is enough.
### Environment
```text
Machine ASUS Ascent GX10 (GB10), 121 GiB unified memory
OS DGX OS, kernel 6.17.0-1032-nvidia, driver 580.173.02
SBIOS GX10DGX.0105.2026.0505.1153
Sampling every 2 s: thermal_zone + clocks.current.sm + power.draw, streamed off-box over ssh
Raw data RUN-native-CRASHED (527 samples), RUN-capped2200-SURVIVED
```
---
*The benchmark that kept killing this machine: [MiniMax H3 Super Acceleration on a DGX Spark](/en/blog/h3-ltx-two-stage-dgx-spark) · The other way a Spark loses power, and how to tell them apart: [30 W safety mode, 100 W cap and the 5 W driver bug](/en/blog/dgx-spark-30w-power-safety-mode)*
---
# [Video] MiniMax H3 Super Acceleration on a DGX Spark: 2x native cold, 3.14x warm
URL: https://ai-muninn.com/en/blog/h3-ltx-two-stage-dgx-spark
Date: 2026-09-14
Series: DGX Spark (Part 47)
On a DGX Spark, MiniMax-H3 drafting at 672x384 and LTX-2.5 refining to 1344x768 takes **118.8 s** cold, against **237.7 s** for native H3 at full size: 2.00x. Run both again with the models still loaded and the gap opens to **73.3 s against 230.1 s**, or 3.14x. The Spark's 121 GiB of unified memory holds both stages' 53.6 GiB of weights at once, so nothing gets evicted between runs. A 31.84 GiB RTX 5090 cannot hold stage 1's 33.5 GiB alone and reloads every time. Caveat: in absolute terms the Spark is 2.4-5.5x slower than a 5090 here, 118.8 s against 40.3 s. This pipeline needs **ComfyUI 0.34.0 or newer** — below that the refine quietly produces garbage frames.
## Preface
A small kitchen makes you put the mixing bowls away before the roasting pans come out. A big counter lets both sit there all afternoon. The recipe does not change. What changes is how much of the afternoon you spend fetching and putting away.
[Part 8 of the RTX 5090 series](/en/blog/minimax-h3-ltx-hybrid-refine-rtx5090) established the method: let MiniMax-H3 draft at 672x384, then let LTX-2.5 spend three steps refining the take you keep up to 1344x768. On a 5090 that beats running H3 natively at full size by 1.28x cold.
I ran the same workflow on a DGX Spark. Same graph, same weights, one quantization swap. The gap widens to 2.00x cold, and to 3.14x once both paths have their models loaded.
A naming note first, because these four terms are easy to run together. NVIDIA calls the method **MiniMax H3 Super Acceleration** and publishes it under Sol Engine, full name Sol Video Inference Engine. The port to a DGX Spark they call **Sol-H3-Spark**, and that is the line this article is on. The terms sit at different levels:
| Name | What it actually is |
|---|---|
| **MiniMax H3 Super Acceleration** | the method — H3 drafts small, LTX-2.5 refines |
| **Sol Engine** | NVIDIA's acceleration framework, which the method ships under |
| **Sol-H3-Spark** | NVIDIA's own build of that method for a DGX Spark, the one here |
| **Sol-Attn** | an attention kernel you can use inside the refine stage |
From here on it is just "two-stage", since what matters is the pipeline rather than which build you came in through.
One thing worth stating because it cuts against the obvious guess: **the 672x384 draft is [NVIDIA's own setting on the Spark](https://nvlabs.github.io/Sana/Sol-Engine/Sol-H3-Spark/), not something I picked.** 896x512 is the draft size on [their GB200 line](https://nvlabs.github.io/Sana/Sol-Engine/H3-Super-Acceleration/); the two lines draft at different sizes. And 672x384 is not an arbitrary number: both lines output 1344x768, and the Spark line runs `LTXVLatentUpsampler` against the `x2` upscaler — 672x384 doubled lands exactly on 1344x768. Going up from 896x512 is 1.5x, which is a different part. So the sigma 0.78 from the last article lines up with this one — if you follow the GB200 build at 896x512 instead, that value needs re-checking.
For a coordinate: NVIDIA report 6.852 s for a 5-second 1344x768 clip on a single GB200. ⚠️ That figure sums separately measured stages and excludes model loading and warmup, so it is not the same quantity as the submission-to-finish times in this article's table. Do not put them side by side.
The Spark is the slower machine at every step of this job. That is the interesting part.
## 118.8 s against 237.7 s, and 3.14x once the models stay loaded
Both paths produce the same thing: 1344x768, 124 frames, 24 fps, with audio. Four draft steps and three refine steps on the two-stage path, four steps at full resolution on the native path.
"Cold" and "warm" appear throughout and have nothing to do with temperature. Cold means the models were freed beforehand and this run reads them off disk. Warm means the previous run just finished and the models are still in memory.
**Every number in the table is the whole workflow, submission to finish** — draft sampling, the handoff, the upscale, refine sampling, VAE decode and writing the file. It is not the time the models alone spent computing. So the 45.5 s a warm run saves is not compute getting faster: the draft and the refine are both recomputed on the second run. What it saves is moving the models in and out of memory. I audit that node by node in the [deep dive](#deep-dive-what-the-18-cached-nodes-were-and-three-departures-from-the-5090-build), because it is the claim in this article most worth doubting.
| | DGX Spark | RTX 5090 |
|---|---:|---:|
| Native H3 at 1344x768 (cold) | **237.7 s** | 51.5 s |
| Native (warm) | **230.1 s** | 41.5 s |
| Two-stage, H3 draft + LTX refine (cold) | **118.8 s** | 40.3 s |
| Two-stage (2nd run, models still resident) | **73.3 s** | 30.6 s |
**Every ratio below compares two paths on the same machine**, two-stage against native. None of them compares one machine to the other.
- Spark: 237.7 against 118.8 cold is **2.00x**; 230.1 against 73.3 warm is **3.14x**
- 5090: 40.3 against 51.5 cold is 1.28x; 30.6 against 41.5 warm is 1.36x
**All four Spark cells were taken with the GPU capped at 2200 MHz.** That is not a choice: uncapped, a second consecutive native run takes the machine down, so the cell cannot be filled at all. The cap costs roughly 20% per run, but all four cells sit under the same restriction, so dividing them is clean. The next article covers the power loss.
One thing to be clear about first. **Every Spark cell is 2.4-5.5x worse than the 5090 cell beside it.** Two-stage costs 118.8 s on the Spark and 40.3 s on the 5090. The pipeline gets a bigger speedup on the Spark. The Spark itself is still the slower machine.
## NVIDIA reports 56.17 s on the same machine. I measure 73.3 s.
The [Sol-H3-Spark page](https://nvlabs.github.io/Sana/Sol-Engine/Sol-H3-Spark/) quotes **56.17 s on a single DGX Spark**, and it is explicit about what that covers: "from prompt arrival, including fresh Qwen encoding, to a completed MP4 with audio", warm. **That is the same quantity as the numbers in my table** — submission to file on disk, Qwen encoding and audio mux included. Their configuration matches too: a 672x384 draft at 124 frames in four steps, three refine steps, 1344x768 and 121 frames out.
So these are directly comparable. **Theirs is 56.17 s, mine is 73.3 s, and I am 1.30x slower.** I chased both reasons. One I could fix, one I cannot.
**One: I did not have Sol-Attn installed, and adding it bought back 4%.** The workflow asks for `auto_sol_attn_conservative_exp`, but there was no `ComfyUI-SolAttn_triton` on this box, so it quietly dropped to dense — the code path is literally called `dense_fallback_sol_attn_not_loaded` and raises nothing. Installed at the same commit the 5090 runs and measured again: **warm goes 73.294 → 70.386 s**, same seed, and the frames look the same side by side.
Four percent, not the 3.1x that page quotes — because the 3.1x is the kernel against FA4, and not many calls in a run qualify. The log is explicit about it:
```text
[sol_attn] sparse (1, 16128, 32, 128) tau=1.0 bf16 pointer
[sol_attn] dense (1, 16128, 32, 128): cross-attention (kept dense)
[sol_attn] dense (1, 126, 32, 64): head_dim 64 != 128
```
Only head_dim-128 self-attention reaches the sparse path. Cross-attention stays dense by design, and the head_dim-64 calls do not qualify at all.
**Two: the clock cap costs this pipeline 6%.** Cap off, one warm run: **66.134 s**, against 70.386 s capped.
(That 6% has to be measured on the two-stage pipeline itself. Native, within one session, goes 226 s to 246.6 s — 9%. The two workloads spend different amounts of time against the clock ceiling, so neither number scales to the other.)
| | Warm |
|---|---|
| Capped at 2200 MHz, no Sol-Attn | 73.294 s |
| Capped at 2200 MHz, with Sol-Attn | 70.386 s |
| Uncapped, with Sol-Attn | **66.134 s** |
| NVIDIA, single Spark | 56.17 s |
So **66.1 s against 56.17 s, still 1.18x, and I did not track it down.** The two factors I could name account for part of the gap. The rest I do not know, and that is where I am leaving it.
⚠️ The four cells in the table below were measured **without** Sol-Attn, because that is the state you are in after following this article. If you want the 4%, install it yourself:
```bash
git clone https://github.com/kijai/ComfyUI-SolAttn_triton \
ComfyUI/custom_nodes/ComfyUI-SolAttn_triton
git -C ComfyUI/custom_nodes/ComfyUI-SolAttn_triton checkout 26d816e
```
The T8 pack identifies a Sol-Attn implementation by **AST-hashing its source**, so a same-named package from a different source is not guaranteed to be accepted — which is why the commit is pinned above.
## Nine weight files, two node packs, and a graph that has to be the -nogemma one
There is no new code here. [T8mars's node pack](https://github.com/T8mars/comfyui-minimax-h3-audio-T8) implements the whole path inside ComfyUI, and the weights are two downloads.
**Both repos are gated** — you have to accept the terms in a browser before your account can download anything. Skip it and the `hf download` below returns a 401. Open [coolthor/MiniMax-H3-pruned-NVFP4](https://huggingface.co/coolthor/MiniMax-H3-pruned-NVFP4) and [Lightricks/LTX-2.5](https://huggingface.co/Lightricks/LTX-2.5) in a browser, accept the terms on each, then:
```bash
hf auth login
```
⚠️ The gate on the H3 repo is deliberate. MiniMax-H3's community licence excludes the EU, the UK, South Korea and the United States, and that restriction travels with the weights.
Everything on the H3 side is in [one repo](https://huggingface.co/coolthor/MiniMax-H3-pruned-NVFP4) — both transformers, the text encoder, both VAEs, the turbo LoRA, the conditioning cache, the custom node and the workflow — and it is laid out as ComfyUI's `models/` tree, so the download lands each file where it belongs instead of leaving you to match folders by hand. LTX-2.5 is the one thing fetched separately; its licence differs from H3's, so it is linked rather than mirrored.
```bash
hf download coolthor/MiniMax-H3-pruned-NVFP4 --local-dir ComfyUI/models \
--include "diffusion_models/minimax_h3_fl2va*" "text_encoders/*" "vae/*" \
"loras/minimax_h3_fl2v*" "conditioning_cache/*" "custom_nodes/*"
```
[LTX-2.5](https://huggingface.co/Lightricks/LTX-2.5) is a separate download under a different license:
```bash
hf download Lightricks/LTX-2.5 --local-dir ComfyUI/models \
--include "diffusion_models/ltx-2.5-22b-distilled-transformer-nvfp4.safetensors" \
"vae/ltx-2.5-*" "latent_upscale_models/*"
```
The first download lands a `custom_nodes` directory inside `models/`, which is the wrong place. Move it once:
```bash
mv ComfyUI/models/custom_nodes/ComfyUI-CondCache ComfyUI/custom_nodes/
```
Then the node packs. **There are two, and the graph will not load if either is missing:**
```bash
git clone https://github.com/T8mars/comfyui-minimax-h3-audio-T8 \
ComfyUI/custom_nodes/comfyui-minimax-h3-audio-T8
git clone https://github.com/xmarre/ComfyUI-Spectrum-MiniMax-H3 \
ComfyUI/custom_nodes/ComfyUI-Spectrum-MiniMax-H3
git -C ComfyUI/custom_nodes/ComfyUI-Spectrum-MiniMax-H3 checkout 4783a22
```
⚠️ **Pin Spectrum at `4783a22`.** An older checkout throws `native MiniMax H3 module is missing required helpers: time_shift_slope` on ComfyUI 0.34.0 and stops the graph at the draft node. At least that one says something, unlike the failure in the next section.
The T8 pack carries the handoff with two nodes. `MiniMaxH3SolEngineDraftToLTXT8Advanced` trims frames and crops the aspect ratio before the draft is passed on, and `MiniMaxH3SolEngineLTXIdentityRefinerSetupT8Advanced` configures how the refine runs.
The second pack supplies `SpectrumApplyMiniMaxH3`, which node 7 of the graph needs. **Miss it and the whole graph refuses to load**, without telling you which node is missing.
`LTXVLatentUpsampler` needs no pack at all — the x2 latent upscaler ships with ComfyUI core.
You do not have to wire it yourself. **This is the exact graph that produced every number in this article** — 32 nodes, renumbered, no local paths in it:
**[⬇︎ minimax-h3-ltx-hybrid-refine-nogemma.json](/workflows/minimax-h3-ltx-hybrid-refine-nogemma.json)**
Drag it into ComfyUI. The same file also sits under `workflows/` in the [Hugging Face repo](https://huggingface.co/coolthor/MiniMax-H3-pruned-NVFP4), which is easier if you are pulling the weights anyway; the direct link above is for reading the graph before you request access.
⚠️ **On a DGX Spark you have to use the `-nogemma` graph.** The Gemma variant errors out on this machine. Details in the deep dive.
### Two things to check yourself
**One: confirm both custom nodes actually registered.** `LoadConditioningT` is a custom node that is in no registry, so if the node pack did not load, the failure reads "node does not exist" rather than "file missing", and you will go looking for a weight file that is already there. Ask the server what it knows:
```bash
curl -s http://:8188/object_info \
| grep -o -E 'LoadConditioningT|MiniMaxH3SolEngineDraftToLTXT8Advanced|SpectrumApplyMiniMaxH3' \
| sort -u
```
All three names have to come back. If any one is missing, the graph loads in the UI and then fails at queue time.
**Two: confirm the refine schedule starts at 0.78.** Not the official 0.909375, written 0.909 from here on. The full schedule is `0.78, 0.643, 0.546, 0`. At 0.909 the refine stage stops sharpening the draft and redraws the face into a different person. That defeats the point of drafting first.
## Get the versions wrong and the refine quietly hands you garbage
This section sits here because it is likelier to cost you a day than anything above it.
**Single-stage H3 is fine on ComfyUI 0.30.x. The two-stage refine is not, and it will not tell you.**
On 0.30.0 the refine returned `status: success`, exit code 0, a log with no errors, and a correctly shaped 1344x768 h264+aac file with 121 frames. Every frame was garbage — five seconds of pure black on the first day, colored noise when I reran the same graph the next morning.
Everything feeding it checked out. The H3 draft decodes to a clean picture. So does the upsampled latent one node *before* the refiner. The latent coming out of the refine has zero NaNs and a standard deviation of 0.80, which is exactly what a healthy latent looks like. So where is the damage? It correlates 0.235 with its own input — and that same input with noise added still correlates 0.74.
Same weights, same graph, same seed, run on an RTX 5090 that happened to already be on 0.34.0: correct clip. Matching the Spark to it fixed the Spark, and **torch was never touched.**
| | correct output | silent garbage |
|---|---|---|
| ComfyUI | 0.34.0 | 0.30.0 |
| comfy-kitchen | 0.2.31 | 0.2.26 |
| ComfyUI-Spectrum-MiniMax-H3 | `4783a22` (2026-08-18) | `fcf2332` (2026-08-05) |
| torch | 2.13.0+cu130 | 2.13.0+cu130 |
**Take that column as one unit.** The three are not independently selectable: ComfyUI 0.34.0 will not finish importing against comfy-kitchen 0.2.26, raising `module 'comfy_kitchen' has no attribute 'int8_attention_is_available'`. There is no configuration that isolates one package, so there is nothing to pin the blame on and no point looking.
⚠️ **Do not reach for `pip install -r requirements.txt --upgrade` to get there.** ComfyUI leaves `torch` unpinned in that file, so `--upgrade` can take your PyTorch and CUDA runtime packages with it. Install the pinned entries instead:
```bash
pip install comfy-kitchen==0.2.31 comfy-aimdo==0.4.15 \
comfyui-frontend-package==1.49.6 \
comfyui-workflow-templates==0.11.48 \
comfyui-embedded-docs==0.5.10
```
**Decode a frame before you trust a number.** Every mechanical check passed on the broken runs — exit code, stream layout, resolution, frame count, duration — and once the failure shifted from black to noise, a black-frame detector passed too. If you are benchmarking this pipeline, look at a frame, or you are benchmarking a pipeline that produces nothing.
## 53.6 GiB of weights fit in 121 GiB, and that is the whole gap
Two stages means two complete model stacks. Nothing is shared between them.
```text
Stage 1 — MiniMax-H3
transformer 11.67 GiB
text encoder 14.61 GiB
video VAE 4.85 GiB
audio VAE 0.56 GiB
turbo LoRA 1.82 GiB
----------
33.5 GiB
Stage 2 — LTX-2.5
transformer 17.44 GiB
video VAE 1.35 GiB
audio VAE 0.34 GiB
latent upscaler 0.93 GiB
----------
20.1 GiB
```
About 53.6 GiB of weights across both stages. Measured peak including working space is 104 GiB out of the 121 GiB available.
An RTX 5090 has 31.84 GiB. (Both 31.84 and 121 are what my two machines report as usable, not the 32 GB and 128 GB on the spec sheets.) That is not enough for stage 1 on its own. So on a 5090 every single run is: load H3, draft, evict H3, load LTX, refine, evict. There is no state to carry into the next run, because there is no room to carry it in.
A DGX Spark's 121 GiB of unified memory holds both stacks with room left over. Load them once and they stay. The difference between the cold run and the second run is 45.5 s (118.815 minus 73.294), and most of that is the loading.
That is the mechanism behind the wider ratio. The Spark is slower at the compute, and the compute is most of what is left once you stop paying for loading.
## Residency is worth 38.3% to two-stage and 3.2% to native
**Two-stage's second run saves 45.5 s. Native's saves 7.6 s.** That is the whole finding: residency helps the two-stage pipeline, not the machine.
| | Cold | Warm | Change | Nodes reused |
|---|---|---|---|---|
| **Native** | 237.7 s | 230.1 s | **-3.2%** | 10 |
| Two-stage | 118.8 s | 73.3 s | **-38.3%** | 18 |
Both paths reuse nodes, so "native has nothing to keep" is too simple an answer. What separates them by a factor of twelve is **how much there is to load** and **what share of the run loading accounts for**. Two-stage has to keep 53.6 GiB resident against native's 33.5 GiB, and native's 230-odd seconds go almost entirely into four sampling steps at 1344x768 — the 7.6 s of loading it saves is 3% of that. Two-stage's sampling is cheap by comparison, a 672x384 draft plus three refine steps, so loading is the larger share.
The 121 GiB buys native almost nothing, then, not because it has nothing to keep but because it has less to keep and its time was never going into loading in the first place.
ComfyUI reports which nodes it skipped: **18 of 32 on two-stage's second run.** All 18 are loaders and configuration — nine model loaders, plus guiders, schedulers, setup nodes and the prompt.
What is *not* among them matters more. Both `SamplerCustomAdvanced` nodes re-ran, so the H3 draft sampling and the LTX refine sampling were recomputed from scratch. So were `VAEEncode`, both `VAEDecode` nodes, `VAEDecodeAudio`, the `DraftToLTX` handoff, the latent upsampler, and `RandomNoise` because the seed changed. **The draft was redrawn.** Every second of generation was paid for again, which rules out saved compute as the explanation for the 45.5 s.
**The speedup is not the hardware being generous. It is that two-stage leaves far more worth keeping in memory, and spends proportionally less of its run computing.**
## The machine lost power twice, both on the second consecutive native run
Not a hang. Power loss. The kind where someone has to walk over and press the button.
It happened twice in one day, and both times it was the second back-to-back native 1344x768 run. The first native run completed fine at 202 s under full load. The second started with no gap and died about 90 s in.
Two-stage ran four times on the same machine with zero crashes, at a memory peak of **104 GiB** — higher than the **74 GiB** that was in use during both crashes. So memory pressure is not the variable.
Sustained-load duration is the candidate that fits. Native is 200 s of unbroken generation. Two-stage's longest continuous segment is 110 s, with lighter VAE and handoff stages in between.
This is not something the pipeline causes, and it has a fix: capping the GPU at 2200 MHz gets the same back-to-back pair to finish, at a cost of about 20% per run. [A report on the NVIDIA developer forum](https://forums.developer.nvidia.com/t/dgx-spark-hard-freezes-under-sustained-few-minutes-inference-powerstress-thermal-failure-support-portal-unavailable/379195) describes hard lockups under sustained inference with the same driver version and the same model. **How I tracked it down, and why a clock cap is what works, is the next article.**
That said, with the clock capped native finishes too. Two-stage's stability edge is real, but a clock cap is the simpler fix — the reason to reach for two-stage is still the 2.00x.
---
## Deep dive: what the 18 cached nodes were, and three departures from the 5090 build
### Every number here was measured a second time
This article first went up on 2026-09-14 quoting 110.6 / 208.5 / 66.8 s and 1.89x. Those two-stage runs were on ComfyUI 0.30.0, and **their output was broken** — the silent garbage described above. The timings themselves were taken correctly, but comparing a pipeline that produces no picture against one that does is not a comparison, so the article came down and was redone.
Every cell in the table above now comes from a run on 0.34.0, and a frame from each of those runs was decoded and looked at. The four old figures are void; do not cite them.
You can run everything above without reading this. Nothing here changes the method or the commands. It is how the numbers were taken, the node-by-node audit behind the 18, and where this build differs from the one in the 5090 article.
### The warm run is only a warm run if you change the seed
Every timing in this post is ComfyUI's `/history` endpoint: `execution_success` minus `execution_start`, divided by 1000.
Cold runs were preceded by:
```bash
curl -X POST http://:8188/free \
-H 'Content-Type: application/json' \
-d '{"unload_models":true,"free_memory":true}'
```
Warm runs have a trap in them. My first attempt reused the seed and came back at **0.006 s** with `cached=31`. Thirty-one of 32 nodes skipped: ComfyUI had recognised the identical graph and returned the previous output. That is a cache hit on the result, not a warm run of the pipeline.
Change the seed and the cached count drops to 18, which is the number the rest of this post uses.
### The 18-node audit
Cached on the two-stage second run:
| Count | Node |
|---:|---|
| 4 | `VAELoader` |
| 2 | `UNETLoader` |
| 1 | `CLIPLoader` |
| 1 | `LoraLoaderModelOnly` |
| 1 | `LatentUpscaleModelLoader` |
| 2 | `BasicGuider` |
| 1 | `KSamplerSelect` |
| 1 | `BasicScheduler` |
| 1 | `SpectrumApplyMiniMaxH3` |
| 1 | `IdentityRefinerSetup` |
| 1 | `LTXVConditioning` |
| 1 | `LoadConditioningT` |
| 1 | prompt node |
Nine of those are loaders. The other nine are configuration that depends only on the loaders.
The 14 that re-ran include both `SamplerCustomAdvanced` nodes, `VAEEncode`, `VAEDecode` x2, `VAEDecodeAudio`, the `DraftToLTX` handoff, `LatentUpsampler`, and `RandomNoise`. Everything that touches pixels or latents was recomputed.
Since the draft was redrawn, the 45.5 s cannot be saved compute. **I attribute it to model loading, but that is an inference rather than a direct measurement** — `execution_cached` reports that a node's output was reused, which is not the same as timing disk I/O or GPU residency. Pinning it down would need the setup and read phases timed separately.
### Three differences from the RTX 5090 build
**LTX-2.5 runs the nvfp4 checkpoint here, int8-convrot in the previous article.** I checked whether that costs speed before swapping: n=3 warm runs on the 5090 gave a median of 30.574 s for nvfp4 against 30.819 s for int8, a difference of 0.245 s while the within-arm spread was 6.0 s. Indistinguishable on speed. I chose nvfp4 because it is 2.6 GiB smaller, and for no other reason.
**Two-stage runs the no-Gemma variant, and on this machine that is mandatory rather than an optimisation.** The stage-2 prompt is a single fixed string, so it is computed once and cached to a file, and the 14.32 GiB text encoder never loads. On the Spark the Gemma graph fails outright:
```text
ValueError: not enough values to unpack (expected 4, got 1)
sd1_clip.py:266
```
Line 266 sits in `forward`, which unpacks what `process_tokens` (line 172 of the same file) returns into four values, and on this machine gets one. A version mismatch between my ComfyUI and that code path is the obvious read, but I did not verify it. **I did not find evidence that every Spark hits this — I can only say mine does.** Swapping to the cached-conditioning graph steps around that call entirely, and the substitution is semantically equivalent rather than an approximation: I diffed the prompt that generated the cache and it is character-identical.
**All four cells in the main table were taken at a 2200 MHz clock cap.** That is not a preference. Uncapped, a second consecutive native run takes the machine down — both attempts are the power losses described above — so the cell cannot be filled at all. The cap costs roughly 20% per run, but it applies to all four cells equally, so the ratios between them are clean.
Two-stage's cold cell was measured twice, at 118.316 s and 118.815 s. The table uses the second.
### Environment
```text
Machine ASUS Ascent GX10 (GB10), 121 GiB unified memory
OS DGX OS, kernel 6.17.0-1032-nvidia
Driver 580.173.02
GPU clock capped at 2200 MHz (nvidia-smi -lgc 300,2200)
ComfyUI 0.34.0, 1157 nodes registered
Packages comfy-kitchen 0.2.31, comfy-aimdo 0.4.15, torch 2.13.0+cu130
Node pack ComfyUI-Spectrum-MiniMax-H3 @ 4783a22
Output 1344x768, 124 frames, 24 fps, with audio
Steps 4 draft / 3 refine
```
---
*Previous in the method: [MiniMax-H3 + LTX-2.5 two-stage on an RTX 5090](/en/blog/minimax-h3-ltx-hybrid-refine-rtx5090)*
---
# [Benchmark] Two-stage MiniMax-H3 + LTX-2.5 on a 2080 Ti: 1344x768 with audio in 165s
URL: https://ai-muninn.com/en/blog/solh3-two-stage-on-2080ti
Date: 2026-09-14
Series: 改裝 2080 Ti 22G (Part 18)
A modified RTX 2080 Ti 22G — a 2018 card — runs the two-stage MiniMax-H3 + LTX-2.5 pipeline at **1344x768**, 121 frames, 5.04 s, with audio, in **165 s** warm and **178 s** cold. The two stages are **53.97 GiB** of weights; the card never holds more than a slice of that, and does not need to. The exact workflow is on HuggingFace, ready to download. Five things have to change from the published Blackwell workflow, two of which fail without printing anything — including one that returns `status: success` with a valid mp4 in which every pixel is exactly RGB(0,0,0).
*Rendered on one modified RTX 2080 Ti 22G: 1344x768, 121 frames, with audio. MiniMax-H3 drafts at 672x384 and LTX-2.5 spends three steps refining it up to twice that — the whiskers, the backlit guard hairs and the dust in the light all come from those three steps. The cat is saying, in Mandarin, "this card is older than I am, but it still runs."*
## Preface
A freight elevator with a 500 kg limit will still get three tonnes to the tenth floor. It just goes up and down more times. The thing that decides whether the job is possible is not the size of the elevator; it is whether the loading dock is big enough to stage what is waiting.
NVIDIA calls this pipeline **[MiniMax H3 Super Acceleration](https://nvlabs.github.io/Sana/Sol-Engine/H3-Super-Acceleration/)**: MiniMax-H3 produces a draft in four steps, then LTX-2.5 spends three refining it up to the target resolution. Four names are easy to mix up here: **H3 Super Acceleration** is the method; **Sol Engine** is the framework it was published under; **[Sol-H3](https://nvlabs.github.io/Sana/Sol-Engine/Sol-H3-Spark/)** is NVIDIA's own version of that method on a DGX Spark; and **Sol-Attn** is the sparse-attention kernel stage 2 uses.
NVIDIA runs this configuration on one DGX Spark in **56 s**. Don't compare that against the 6.852 s on the GB200 page: that figure sums two separately measured stages, and the page says model loading and warmup are excluded, so it is not a wall clock from prompt to finished file.
[Part 11](/en/blog/minimax-h3-on-modded-2080ti-22gb) proved this card can run MiniMax-H3 at all — single-stage, 864x480. [Part 8 of the RTX 5090 series](/en/blog/minimax-h3-ltx-hybrid-refine-rtx5090) took the method apart, and that is where the refine sigma moved from NVIDIA's `0.909375, 0.725, 0.421875, 0` down to `0.78, 0.643, 0.546, 0`.
⚠️ Worth settling up front, because the two NVIDIA pages disagree: **the pipeline parameters here match NVIDIA's Spark line** — a 672x384 draft, 124 frames, four draft steps, three refine steps, output at 1344x768, 5 seconds at 24 fps. The GB200 page lists a 896x512 draft, but that belongs to the GB200 line, not this one.
**The weights are a different story.** NVIDIA runs an NVFP4 text encoder and an FP8 DiT on the Spark, and Turing has neither format. That is why this article ends up on int8-convrot, w4a4 and GGUF Q4_K_M instead: same pipeline, different things loaded into it. The sigma schedule below was calibrated at 672x384 and the knee moves if you change the draft size.
This card has 22 GB and the elevator goes up and down a lot. The pipeline still finishes 1344x768 with audio in 165 seconds.
## 178 s cold, 165 s warm, and 53.97 GiB that never fits
One modified RTX 2080 Ti 22 GB, compute capability 7.5, a Turing part from 2018. Output is 1344x768, 121 frames at 24 fps, 5.04 seconds, with audio.
Cold — the models were freed beforehand and this run reads them off disk — is **178 s**. Warm, with the models still resident and only the seed changed, is **165 s**, the median of three runs with a 1.08 s spread between them. Model loading is 13 s of that — the cold/warm difference. The warm 165 s is all compute.
One number is higher than both, and it is the first one you will see after setting this up: **190 s**, twice, to the tenth of a second. Restarting ComfyUI throws away Triton's kernel cache, which forces SageAttention's six kernels to recompile — about 12 s. You pay it once per ComfyUI process: free the models inside that same process and the next run is 178 s again.
Which gives one practical rule for the whole rest of this article: while you are iterating on parameters, do not free the models between runs. That 13 s is free.
The two stages together are 53.97 GiB of weights. A 22 GB card cannot hold that and is never asked to — ComfyUI loads models sequentially, and the H3 transformer reports as much on a run that produces a correct video:
```text
loaded partially ... 2861 MB offloaded
```
So the constraint that actually decides whether this machine can do the job is not VRAM. It is fast storage plus enough system RAM to absorb the offload. This box has 128 GB.
> 📦 **The workflow that produced these numbers is on HuggingFace, ready to download.**
> Not a sketch, not a simplified version — the exact 31-node graph this machine runs:
>
> ```bash
> hf download coolthor/H3-Super-Acceleration-Turing --local-dir . \
> workflows/minimax-h3-ltx-two-stage-turing-sm75.json TURING.md
> ```
>
> The same repo carries the startup adapter, the conversion script, and the 13.2 GiB heretic
> text encoder. Full inventory and step-by-step in [`TURING.md`](https://huggingface.co/coolthor/H3-Super-Acceleration-Turing/blob/main/TURING.md).
## Start from TURING.md: five departures from the Blackwell workflow, and two of them are silent
The executable version of everything below lives in `TURING.md` in the [Hugging Face repo](https://huggingface.co/coolthor/H3-Super-Acceleration-Turing), along with the workflow, the startup adapter and the conversion script. Read that for the steps:
```bash
hf download coolthor/H3-Super-Acceleration-Turing --local-dir . TURING.md && cat TURING.md
```
This section is the part `TURING.md` cannot be: **why each departure is mandatory**. It matters because three of the six fail with no error at all. Copy the published Blackwell graph onto this card and you do not get a stack trace — you get broken output, or you get correct output at half the speed you should be getting, and nothing in the log tells you which.
### 1. Both repos are gated, and a 401 is easy to misread
`coolthor/H3-Super-Acceleration-Turing` and `Lightricks/LTX-2.5` are both gated. `hf download` returns a 401 and the message is actually explicit (`Access to model ... is restricted. You must have access to it and be authenticated`), but it is easy to read as a network problem if you are running someone else's script. Accept the terms in a browser on each repo, then `hf auth login`.
The H3 gate is deliberate. MiniMax-H3's community licence excludes the EU, the UK, South Korea and the United States, and that restriction travels with the weights.
### 2. Weights: H3 from one repo, the LTX refiner as GGUF from another
Six files from `coolthor/H3-Super-Acceleration-Turing`, all in one call:
```bash
hf download coolthor/H3-Super-Acceleration-Turing --local-dir ComfyUI/models \
diffusion_models/minimax_h3_fl2va_pruned_int8_convrot.safetensors \
text_encoders/qwen3vl_32b_heretic_convrot_w4a4.safetensors \
loras/minimax_h3_fl2v_turbo_4step_v0.1_768p_sla_comfyui_bf16.safetensors \
vae/minimax_h3_video_vae_fp16.safetensors \
vae/minimax_h3_audio_vae_fp32.safetensors \
conditioning_cache/ltx_generic_refine.cond
```
The LTX refiner is the GGUF build, and that is not a size optimisation — see the black-video section below. The VAEs and the x2 upscaler come from `Lightricks/LTX-2.5` as bf16 and get converted locally, which is departure 4.
```bash
hf download agosh/LTX-2.5-Comfy-GGUF --local-dir ComfyUI/models/diffusion_models \
ltx-2.5-22b-distilled-transformer-bf16-Q4_K_M.gguf
hf download Lightricks/LTX-2.5 --local-dir ComfyUI/models \
vae/ltx-2.5-video-vae-conv-bf16.safetensors \
vae/ltx-2.5-audio-vae-bf16.safetensors \
latent_upscale_models/ltx-2.5-latent-spatial-upscaler-x2-bf16-1.0.safetensors
```
Where you put these files is worth ten minutes. Storage speed shows up directly in that 13 s of loading. Measured on this machine: ext4 on NVMe at 2.3 GB/s, and an ntfs3 volume on the same box at 1.2 GB/s. The 13.2 GiB text encoder started life on the slow one. Moving it saved 5.6 s per cold run.
### 3. Two node packs, plus a startup adapter
```bash
git clone https://github.com/T8mars/comfyui-minimax-h3-audio-T8
git clone https://github.com/city96/ComfyUI-GGUF
```
The second one is needed only on this card: it provides `UnetLoaderGGUF`, which node 15 of the workflow uses instead of `UNETLoader`.
⚠️ **Updated 2026-09-16: a third pack, `ComfyUI-Spectrum-MiniMax-H3`, used to be here and has been removed.** See [the node that never fires](#bonus-spectrum) for why.
A fourth does not come from git. Node 32's `LoadConditioningT` lives in `ComfyUI-CondCache`, which ships alongside the workflow — pull the one file into `custom_nodes/`:
```bash
hf download coolthor/H3-Super-Acceleration-Turing --local-dir ComfyUI \
custom_nodes/ComfyUI-CondCache/__init__.py
```
Miss it and the whole graph refuses to load, with an error that says the node does not exist rather than that a file is missing — so you go hunting for a weight that is already on disk.
On top of those, a startup adapter ships in the HF repo at `custom_nodes/ComfyUI-LTXV-Turing-FP16/`. It only acts when `torch.cuda.get_device_capability() == (7, 5)`, so it is inert on any other GPU:
```bash
hf download coolthor/H3-Super-Acceleration-Turing --local-dir ComfyUI \
custom_nodes/ComfyUI-LTXV-Turing-FP16/__init__.py
```
What it fixes, and why the obvious flag does not fix it, is the second silent failure in the deep dive.
### 4. Convert the LTX bf16 files to fp16, or pay for them twice
Turing has no bf16 hardware. ComfyUI upcasts bf16 to fp32, and the tensor then takes exactly twice its on-disk size in VRAM. Measured: `ltx-2.5-video-vae-conv-bf16.safetensors` is 1.35 GiB on disk and loads as **2769.87 MB**. The x2 upscaler is 0.93 GiB on disk and loads as **1899.22 MB**.
Convert all three — video VAE, audio VAE, x2 upscaler — with the script in the repo. It saves about 2.7 GB:
```bash
hf download coolthor/H3-Super-Acceleration-Turing --local-dir . scripts/bf16_to_fp16.py
```
I checked tensor by tensor: **zero tensors exceeded the fp16 range**. That claim is narrower than it sounds. It covers the numeric range of the weights themselves — not the activations flowing through at inference, not underflow, and not output quality. fp16 stores 10 fraction bits against bf16's 7, but converting hands no precision back: whatever bf16 dropped during training is gone. All you buy is that ComfyUI stops upcasting.
⚠️ The script preserves the safetensors header metadata, and it has to. `save_file()` drops metadata by default, and ComfyUI's `VAELoader` reads the `config` key out of that header to pick the VAE architecture. My first version dropped it. The symptom is a shape mismatch that looks like you downloaded the wrong file:
```text
size mismatch for encoder.down_blocks.7.conv.conv.weight: copying a param with
shape [128, 1024, 3, 3, 3] ... current model is [256, 1024, 3, 3, 3]
```
### 5. SageAttention 1.0.6, and one integer inside it
Launch flags:
```bash
python main.py --use-sage-attention --reserve-vram 2 --disable-pinned-memory
```
The version has to be **1.0.6**. Everything from 2.x on needs sm_80 or newer; [SageAttention issue #137](https://github.com/thu-ml/SageAttention/issues/137) is another 2080 Ti owner hitting `Unsupported CUDA architecture: sm75`.
Installing 1.0.6 is not enough on its own. At stock settings its Triton kernels request **67584 bytes** of shared memory and Turing's hard limit is **65536**. Triton refuses, and ComfyUI quietly falls back to PyTorch attention — which is the third silent failure, and it costs you the whole point of installing it. In all six `attn_qk_int8_*.py` files under `site-packages/sageattention/`:
```python
num_stages=3 if head_dim == 64 else 1)
```
⚠️ Do **not** touch `BLOCK_M` while you are in there. It looks like a sibling scheduling knob and it is not one. `quant_per_block.py`'s `per_block_int8(BLKQ=128)` produces one quantization scale per `BLKQ` rows, and the kernel indexes that array with its own `BLOCK_M`. Change one without the other and you read invalid scales, or index past the end of the array, with no error either way. `num_stages` only changes pipeline depth; it leaves the algorithm itself alone.
### 6. Two values inside the workflow
The graph is 31 nodes:
```bash
hf download coolthor/H3-Super-Acceleration-Turing --local-dir . \
workflows/minimax-h3-ltx-two-stage-turing-sm75.json
```
Two things in it differ from the Blackwell version, and this table is the one to check node by node after you drag the JSON in:
| Node | Value | Why |
|---|---|---|
| 15 | `UnetLoaderGGUF`, not `UNETLoader` | The big one. See the next section. |
| 16 | `attention_backend` = `dense_reference` | Sol-Attn's kernel is bf16-only, so this card never reaches it |
Node 16 is the one where the honest setting and the useful setting are the same. Setting `auto_sol_attn` on this card does not enable anything; it just makes every call fall back to dense, silently. Writing `dense_reference` describes what the card does anyway.
## The 284 s run that reported success and wrote a completely black mp4
The first full-pipeline run took 284 s and finished with `status: success`. The output was a valid mp4: 1344x768, 121 frames, 5.04 s, h264 and aac both present, `cached=0`. There was no error anywhere in the log.
I extracted three frames. All three JPEGs were **exactly 6250 bytes**, which is the fingerprint of a solid colour, and every pixel in them was exactly `RGB(0,0,0)`.
That byte count is what turned a mystery into a diagnosis. An all-zero latent decoded through a VAE does not come out black — bias terms push it to a non-uniform grey. That is not a diagnosis on its own — black output can come from cropping, decoding or postprocessing — but it was enough to make me go and measure the latent itself. `SaveLatent` on both sides of the refine step confirmed it:
| | shape | NaN | min | max | std |
|---|---|---|---|---|---|
| before refine | `(1,128,16,24,42)` fp32 | 0 | -6.1942 | 5.4041 | 0.9560 |
| after refine | same | 2,064,384 / 2,064,384 | — | — | — |
The draft latent was healthy. The refine pass destroyed it. Swap in the GGUF Q4_K_M build of the same model and it is correct on the same card, and smaller — 11.38 GiB against 20.03. That is why node 15 is `UnetLoaderGGUF`.
⚠️ Be careful how far you carry that. What the comparison establishes is that **this checkpoint fails and the GGUF one works on this stack** — ComfyUI 0.31.0, comfy-kitchen 0.2.28, torch 2.6. It does not isolate whether the fault is in the weights, the dequantization, or the kernel, because swapping the file changes all three at once. I could not test the version axis: comfy-kitchen 0.2.31 will not import under torch 2.6 (`infer_schema` rejects the `list[int]` annotation in `backends/eager/na.py`), and torch 2.6 is what sageattention 1.0.6 and triton 3.2.0 are pinned against. That version set is what this card can run, so it is the set the finding is scoped to.
⚠️ The trap in this is that H3's own int8-convrot build is fine on this card. Same quantization family, same machine, one works and one does not. ComfyUI prints a line at load that reads like a green light:
```text
Native ops: int8_tensorwise, asym_w4a8_int8, convrot_w4a4
```
That line means "not emulated". It does not mean "correct". Verify per model.
## The node that never fires
**Added 2026-09-16.** After this went out, a reader pointed out that `SpectrumApplyMiniMaxH3` is pure wrapper overhead at a 4-step draft and cannot change the output. They were right, and the proof is in the node's own logging.
It is configured with `warmup_steps = 5`, and the draft runs **4 steps**. It never finishes warming up. Turn its `debug` on and it says so itself:
```text
actual_steps=4 forecast_steps=0 phase_counts=model:a4/f0
actual_transformer_calls=4 forecast_calls=0 bypassed_steps=0
```
`forecast_calls=0` — it never forecast once. All four steps were computed in full, which is the same number of transformer calls you get with the node absent.
So how much does removing it save? **Neither card shows a measurable difference.**
| | with Spectrum | without |
|---|---:|---:|
| 2080 Ti, warm (n=3 each) | 165.0 | 165.0 |
| RTX 5090, warm (interleaved, n=6 pairs) | 22.96 | 22.37 |
The 5090 medians differ by 0.59 s, or 2.6%, against a standard deviation of 2.88 s within each arm — a fifth of the noise. My first pass, without interleaving and without discarding warm-up runs, said +7.1%. That number was an artifact.
**It is dead weight, not a bottleneck.** I took it out anyway, for a reason that has nothing to do with speed: it forces anyone following this guide to install **an extra node pack** and to assume that pack is load-bearing. That is why the pack list above went from three to two and the graph from 32 nodes to 31.
⚠️ One departure went with it. This article used to list a sixth — writing `bootstrap_first_forecast: false` explicitly on node 7 — and **that departure existed only because Spectrum did**. One fewer node, one fewer trap.
---
## Dropping the draft to 544x320 saves 30% of the clock and no detail I can see
`LTXVLatentUpsampler` is a fixed x2, so the draft is always exactly half the output. Lowering the draft lowers the finished video with it — this is not a quality knob with a free lunch attached, it is a resolution knob.
Three points, same workflow, only the draft size and the handoff target changed. Read the last two columns against each other:
| draft | output | cold | warm | draft pixel ratio | warm time ratio |
|---|---|---:|---:|---:|---:|
| 672x384 | 1344x768 | 179.8 | 167.0 | 1.000 | 1.000 |
| 544x320 | 1088x640 | 129.5 | 117.3 | 0.675 | 0.702 |
| 432x240 | 864x480 | 84.5 | 76.9 | 0.402 | 0.460 |
Time tracks pixels almost exactly. The fit is `warm seconds ≈ 16.4 + 150.6 × (draft pixels / 258,048)`, which predicts 118.0 s for the middle row against 117.3 measured, 0.6% off.
I expected superlinear scaling and was wrong, and the reason matters: attention cost grows with the square of token count, so I assumed attention would dominate. It does not. In this workload it is not the dominant term.
**Stop at 544x320 → 1088x640.** 117 s, 30% saved, and hair strands, earring detail and skin shading all look essentially intact. The next rung down is 77 s and visibly soft.
*Same cat, same seed, draft dropped to 544x320 for a 1088x640 output. Put it beside the clip at the top — what changes is mostly size, not detail.*
⚠️ Those three rows are three separate generations, not three quality levels of one clip. Changing the resolution changes the latent shape, so the same seed follows a different sampling trajectory and you get a different take. Compare detail density between them, not content.
The other lever, and the one that costs no spatial detail at all, is frame count. Cutting it scales close to linearly.
---
## Deep dive: four hypotheses the measurements killed, and three ways this stack fails quietly
Reading this is optional — everything you need to run the pipeline is above. This is how the black video got diagnosed, and the three places on this card where something switches itself off and says nothing.
### Four hypotheses ruled out before the right one
**Out of memory.** The log had a line that looked like a smoking gun: the final LTX VideoVAE reported `loaded partially; 0.00 MB usable, 0.00 MB loaded, 2769.87 MB offloaded` while `nvidia-smi` showed 4,260 MiB still free on the card. I swapped in `VAEDecodeTiled`; the memory behaviour changed completely and the output was still black. Later, runs that produced correct video printed the same line. Symptom, not cause.
**Compute dtype falling to fp32.** Side by side, the two stages disagreed:
```text
Stage 1 (H3) model weight dtype torch.float16, manual cast: torch.float16
Stage 2 (LTX) model weight dtype torch.bfloat16, manual cast: torch.float32
```
The convrot kernels only take FP16 or BF16, so this was a real problem. Fixing it cut the run from 266 s to 179 s, a 33% saving. The picture was still black. Necessary, not sufficient — and worth separating out, because 33% less wall-clock time is exactly the kind of result that makes you think you have found the bug.
**Schedule or conditioning strength.** I pushed sigma down to `0.05, 0.03, 0.01, 0`, where the refine stage should barely perturb its input at all. Still black.
**fp16 range overflow.** I concluded this one and was wrong. The evidence looked strong: the blackness was too clean, the latent was all NaN, and it matched an overflow this same card produced with H3 back in August 2026. What killed it is that the fp32 runs were also black. A pure range problem should have made fp32 slow, not broken. Both dtypes black rules out the top-level compute dtype as the explanation. Strictly it does not rule out an overflow inside a kernel that still works in fp16 internally — establishing that would need instrumentation I did not do.
The comparison that settled it changes one thing — the refiner file — holding model, version, sigma, VAE and machine constant:
| LTX refiner file | dequant path | seconds | result |
|---|---|---:|---|
| `...comfy-int8-convrot` 20.03 GiB | comfy-kitchen convrot kernel | 179.1 | all NaN |
| `...bf16-Q4_K_M.gguf` 11.38 GiB | ComfyUI-GGUF (dequant→fp16→ordinary GEMM) | 185.0 | correct |
| `sulphur-distil-ltx23av-Q4_K_M.gguf` (LTX **2.3**) | same | 198.2 | correct but changes the face |
The third row is worth a note if you are tempted to substitute an older refiner. LTX-2.3 refines perfectly well, but the face comes back as a different person. sigma 0.78 is the knee calibrated for **2.5** in the six-arm sweep from the 5090 article; a different model generation slides off it. That is a calibration problem, not a GGUF problem.
### Silent failure 1: Sol-Attn never tells you it did not run
`ComfyUI-SolAttn_triton`'s kernel is bf16-only. The eligibility check is at `__init__.py:176-177`:
```python
if q.dtype != torch.bfloat16:
return f"dtype {q.dtype} (kernel is bf16-only)"
```
Turing has no bf16, so that condition held on every call in this workflow. The rejection path is `return None` falling back to dense, not an exception. And the registry entry point `attention_sol` hardcodes `verbose=False`, so a path entered through `attention_backend` prints nothing whatsoever.
There is a way to check. Sol-Attn keeps its own counters: `sol_attn_stats()` returns a dict with `sparse` and `dense_fallback`, and `sparse > 0` is what proves the kernel actually ran. That is more reliable than reading the log, because `_log_once` deduplicates on `(shape, reason)` — "no message in the log" cannot distinguish "never engaged" from "deduplicated away". The counter can.
The other two ComfyUI ports exclude Turing too, and say so in their own docs: [Saganaki22/ComfyUI-sol-attn](https://github.com/Saganaki22/ComfyUI-sol-attn) states SM89 through SM121, and [quzopl/ComfyUI-SolAttn-H3](https://github.com/quzopl/ComfyUI-SolAttn-H3) states SM89, 90, 100 and 120. Neither of the two ports I checked covers sm_75 either.
### Silent failure 2: --fp16-unet does nothing for a quantized model
This is why the startup adapter exists at all.
`LTXV.supported_inference_dtypes` is `[bfloat16, float32]`. No bf16 on Turing means the compute dtype lands on fp32, which is the 33% tax from the hypothesis section above. The obvious fix is `--fp16-unet`. It does not work, and `comfy/sd.py` says why:
```python
if model_config.quant_config is not None:
manual_cast_dtype = unet_manual_cast(None, load_device, model_config.supported_inference_dtypes)
else:
manual_cast_dtype = unet_manual_cast(unet_dtype, load_device, model_config.supported_inference_dtypes)
```
A quantized model takes the first branch, where `weight_dtype` is deliberately `None`. That is a defensible choice on its own terms: the weights are int8, and their dtype says nothing about what the compute should be. But every branch inside `unet_manual_cast` that inspects `weight_dtype` then falls through, leaving only the `for dt in supported_dtypes` loop — and the flag's `unet_dtype` is never passed in on that path. The symptom is the half-applied line from earlier:
```text
model weight dtype torch.float16, manual cast: torch.float32
```
The flag reached the storage dtype and never touched the compute dtype. Three ways to fix that:
| approach | works | scope | survives ComfyUI upgrade | visible |
|---|---|---|---|---|
| edit `comfy/supported_models.py` | yes | LTXV only | no, gets overwritten | no |
| `--fp16-unet` flag | no for quantized models | whole service | yes | yes |
| **startup adapter in `custom_nodes/`** | yes | LTXV only | yes | yes, in the startup log |
The third wins on the two columns that matter for a machine you come back to in three months: it survives an upgrade, and it announces itself in the startup log so future-you can see it is there. This box already had a `kitchen_turing_int8_enable.py` doing the same kind of thing, so the pattern was local precedent rather than invention. To revert, delete that one file.
### Silent failure 3: SageAttention falls back, and the margin is 2048 bytes
Dozens of these in the log:
```text
Error running sage attention: out of resource: shared memory,
Required: 67584, Hardware limit: 65536. using pytorch attention instead.
```
67584 − 65536 = 2048. Here is where the shared memory goes at `BLOCK_M=128 / BLOCK_N=64 / HEAD_DIM=128`:
| num_stages | Q | K | V | total |
|---:|---:|---:|---:|---:|
| 4 | 16384 | 32768 | 65536 | 114688 |
| 2 | 16384 | 16384 | 32768 | 65536 |
| 1 | 16384 | 8192 | 16384 | 40960 |
`num_stages=2` lands exactly on the limit. The extra 2048 bytes that push it over are unaccounted for in my estimate — I did not chase where they come from. Dropping to 1 leaves headroom either way.
The generalisable part of this is the rule about `BLOCK_M` from departure 5. That constant also determines the **shape** of `q_scale`, as `(qo_len + BLKQ - 1) // BLKQ`. **If a constant determines the shape of a tensor, it is not a scheduling parameter.** That is a test you can apply to any kernel you are tempted to tune, without knowing anything about the kernel.
### What SageAttention is actually worth here: not speed, feasibility
Same workflow, n=3, warm median:
| config | cold | warm |
|---|---:|---:|
| SageAttention 1.0.6 | 178 | 165 |
| disabled, plain pytorch SDPA | 213 | out of memory |
With it disabled the cold run completes 35 s slower. The second run does not complete at all — it dies about four seconds in:
```text
Got an OOM, unloading all loaded models
```
PyTorch's memory-efficient SDPA needs more VRAM than SageAttention's INT8 kernels, and on a warm run the models are still sitting on the card. So on this hardware SageAttention is not a 20% optimisation you can skip. It is the difference between a warm run and no warm run.
⚠️ One research note, because it nearly went into this article as a fact. While looking into this, two web searches fed back "SageAttention is 16.8% faster than PyTorch SDPA on a 2080 Ti" as though it were external corroboration. That number came from this site's own August article. **When you are researching a topic you have written about, check that the hit is not you.** It was also measured on 864x480 single-stage H3. Same card, different workload shape — and a number measured on one shape does not carry to another.
### Environment
```text
GPU RTX 2080 Ti 22G (modified) - compute capability 7.5 (Turing)
OS Linux - torch 2.6.0+cu124 - triton 3.2.0 - Python 3.12
ComfyUI 0.31.0 - comfy-kitchen 0.2.28 - sageattention 1.0.6
Launch flags --use-sage-attention --reserve-vram 2 --disable-pinned-memory
Storage ext4 NVMe measured at 2.3 GB/s - 128 GB system RAM
Weights 53.97 GiB total
Output 1344x768 - 121 frames - 24 fps - with audio
Steps 4 draft / 3 refine
```
---
The workflow JSON, the startup adapter, the conversion script and the 13.2 GiB heretic text encoder — ConvRot W4A4, the first build of it published anywhere as far as I know — are all documented in `TURING.md` at [coolthor/H3-Super-Acceleration-Turing](https://huggingface.co/coolthor/H3-Super-Acceleration-Turing).
*The method on a card with room to spare: [MiniMax-H3 + LTX-2.5 two-stage on an RTX 5090](/en/blog/minimax-h3-ltx-hybrid-refine-rtx5090)*
---
# [Benchmark] Roll cheap, then enhance the keeper: NVIDIA's two-stage MiniMax-H3 + LTX-2.5 pipeline explained
URL: https://ai-muninn.com/en/blog/minimax-h3-ltx-hybrid-refine-rtx5090
Date: 2026-09-13
Series: MiniMax-H3 on RTX 5090 (Part 8)
MiniMax-H3 drafts the clip at 672×384, a quarter of the pixels, and LTX-2.5 spends 3 steps refining it to 1344×768. Cold, single shot: **40.3 s against 51.5 s** for H3 running native at full size. The bigger gain is that every finishing option reuses one draft, so the face stays the same person — native re-rolls the latent at each resolution and hands you someone else. Audio comes out of H3's draft pass and never enters stage 2. One thing to change: NVIDIA's stage-2 sigma of 0.909375 repaints faces on the ComfyUI path. Use 0.78.
A photographer shoots a contact sheet, looks at it, and prints one frame. Nobody prints all thirty-six, and nobody shoots the whole roll at print quality either.
[Part 2](/en/blog/minimax-h3-rtx5090-speedup-vsr) of this series replaced Real-ESRGAN (109 s) with RTX VSR (11.2 s) and got the upscale down to something you stop noticing. [Part 7](/en/blog/ltx25-vs-minimax-h3-rtx5090) put LTX-2.5 and MiniMax-H3 head to head on the same card. On 2026-09-11 NVIDIA Research's Efficient AI team published [Sol-H3-Spark](https://nvlabs.github.io/Sana/Sol-Engine/Sol-H3-Spark/), whose claim is one sentence long: don't run the generator at its most expensive resolution. The ComfyUI implementation that makes it reachable without writing code is [T8mars's node pack](https://github.com/T8mars/comfyui-minimax-h3-audio-T8).
This is what that costs and buys on one RTX 5090, with the one setting you have to change from the official recipe.
---
## H3 never runs at 1344×768 — LTX-2.5 does
Both paths end in the same place: 1344×768, 5 seconds, with audio. The native path is one model at one resolution — MiniMax-H3 runs 4 steps at 1344×768, decodes, done. The hybrid path splits the job: H3 runs its 4 steps at 672×384, then [LTX-2.5](https://huggingface.co/Lightricks/LTX-2.5) runs 3 refinement steps at full resolution.
The handoff is the whole trick. H3's latent (the compressed tensor the sampler actually works on, before anything becomes pixels) comes out at 672×384, gets decoded to RGB, gets re-encoded with LTX's own VAE, goes through LTX's ×2 latent upsampler to land at 1344×768, takes 3 refine steps, and is decoded by the LTX VAE.
Three things about that diagram are not obvious.
**Resolution only changes after the handoff.** H3 never touches 1344×768 in the hybrid path — the upscale happens in LTX's latent space, on LTX's terms.
**Audio never enters stage 2.** H3 generates video and audio in one forward pass, so the track is done at draft stage and is muxed into the MP4 at the end. Simplified Chinese dialogue quality is H3's, and refinement cannot help or hurt it.
**The two stages are two independent model stacks.** Nothing is shared — not the transformer, not the VAE, not the text encoder. That matters for VRAM, and the memory numbers are in the deep dive.
## Three nodes carry the handoff, and nine files sit behind them
The path adds three nodes to a working H3 workflow. `MiniMaxH3SolEngineDraftToLTXT8Advanced` trims H3's decoded frames to LTX's 8n+1 frame grid and centre-crops them to half the requested output size. `MiniMaxH3SolEngineLTXIdentityRefinerSetupT8Advanced` returns the model, sampler and sigmas for stage 2. `LTXVLatentUpsampler` is the official ×2 latent upsampler, unmodified.
The weights, by side:
```text
H3 side
minimax_h3_fl2va_pruned_nvfp4 11.67 GiB
qwen3vl_32b_heretic_minimax_h3_nvfp4 14.61 GiB
minimax_h3_video_vae_fp16 4.85 GiB
minimax_h3_audio_vae_fp32 0.56 GiB
minimax_h3_fl2v_turbo_4step_v0.1_768p_sla 1.82 GiB
LTX side
ltx-2.5-22b-distilled-transformer-int8 20.03 GiB
ltx-2.5-video-vae-conv-bf16 1.35 GiB
ltx-2.5-audio-vae-bf16 0.34 GiB
ltx-2.5-latent-spatial-upscaler-x2-bf16 0.93 GiB
```
The 4-step turbo LoRA on the H3 side is [lightx2v](https://huggingface.co/lightx2v)'s, not the FastVideo one NVIDIA used. That substitution and two others are in the deep dive.
### Download the whole workflow
You don't have to wire any of this by hand. Here is the exact graph every number in this post came from — 33 nodes, renumbered, no internal paths in it:
**[⬇︎ minimax-h3-ltx-hybrid-refine.json](/workflows/minimax-h3-ltx-hybrid-refine.json)**
Drag it into ComfyUI and it expands. The prompt baked in is the one from the clip above; swap it for yours. ComfyUI flags any missing weight in red — look the filename up in the list above.
⚠️ This is the **basic build**: zero code, and without the text-encoder removal from the deep dive.
📌 **The same pipeline on a DGX Spark goes from 1.28x to 1.89x over native**, because its 121 GiB of unified memory holds both stages and stops the per-run reload: [Two-stage on a DGX Spark](/en/blog/h3-ltx-two-stage-dgx-spark).
The H3 half of the weights is packaged in one repo — both transformers, the text encoder, both VAEs and the 4-step turbo LoRAs, laid out as ComfyUI's `models/` tree so one download gets you running: **[coolthor/MiniMax-H3-pruned-NVFP4](https://huggingface.co/coolthor/MiniMax-H3-pruned-NVFP4)**. Both graphs live there too, under `workflows/` — this one and the no-text-encoder variant from the deep dive. LTX-2.5 is not mirrored there; different license, so you fetch it from Lightricks.
## 1344×768 is forced: both latent grids have to come out 42×24
Two constraints pin the size. Output width and height must both be divisible by 32, which is a hard requirement of the LTX latent, and the draft must be exactly half the output in each dimension.
Work it through at 1344×768: 1344/32 = 42 and 768/32 = 24 on the LTX side, while the H3 side divides by 16, giving 672/16 = 42 and 384/16 = 24. Both latent grids are 42×24, which is what the handoff needs.
One consequence worth stating out loud: 1344×768 is 7:4, not 16:9. True 16:9 at height 768 would be 1365.33 px wide, which is not an integer and certainly not a multiple of 32.
## The one number you have to change from NVIDIA's config is the stage-2 sigma
The sigma schedule tells the sampler how much noise it should assume is still in the latent. A high first sigma means "treat this as mostly noise", which gives the refiner licence to repaint rather than sharpen. NVIDIA's `configs/default.json` hardcodes the stage-2 schedule at `[0.909375, 0.725, 0.421875, 0]`, and on the ComfyUI decode-then-re-encode path that breaks.
To measure it I picked a window in the background — pure background, nothing in the scene moves it, so any shift is an artifact — and counted the frames where that region scaled by 1 px or more, out of 120 frame transitions. Read the right-hand column as "how often the geometry twitched":
| First sigma | Frames the background moved |
|---|---:|
| no refine | 0 |
| 0.5 (official identity preset) | 1 |
| **0.78** | **2** |
| 0.85 | 6 |
| 0.909 | 11 |
0.65 also came in at 1, so the usable range is wider than the table suggests. What the table shows is that degradation is not linear — it is a cliff between 0.78 and 0.85.
The frame count is the machine-readable symptom; the visible one is worse. At 0.909 the refiner swaps the face outright, repainting the features into a different person and dropping the necklace entirely. At 0.85 it starts leaking: the necklace changes from a square pendant to a heart. 0.78 kills both problems, and it was the fastest of the six settings I ran.
T8mars's identity refiner node has a `manual_exp` mode. Enter:
```text
0.78, 0.643, 0.546, 0
```
## The upscaler can't invent detail, so it belongs last
Here is the same 672×384 draft with two different finishes. This is the draft, as it comes out of H3 in 25.5 s:
Send it through VSR and the canvas reaches 1344×768. The face goes from 175×161 to 350×323 effective pixels, which sounds like the job is done. It isn't: not one eyelash is new. Interpolation spreads the pixels that already exist over a larger grid, and that is all it can do.
LTX's 3 refinement steps run the generator again at full resolution, with the draft as the starting point rather than noise. Hair strands, tooth edges, skin texture — none of that is in the draft, and after the refine it is there. The difference isn't learned versus not learned. It's whether a generator gets a second pass.
And that is the placement argument, not an argument against VSR. It is a cheap, driver-level upscaler that cannot add information; run it where there is information to spread, which is after the refine, not instead of it.
## One draft, many finishes: the saving is in the takes you throw away
The single-shot comparison is the least interesting number here. Cold — models unloaded before each run — the hybrid path takes 40.3 s and native 4-step H3 at 1344×768 takes 51.5 s. An 11 s gap on one clip is not a reason to rewire a workflow.
The reason is that nobody ships the first take. The draft on its own costs 25.5 s, which means you can roll ten of them and only pay full price on the one you keep:
```text
hybrid: 10 × 25.5 (roll drafts) + 50.2 (refine the keeper) ≈ 305 s
native: 10 × 51.1 ≈ 511 s
```
That is arithmetic, not a measurement. I measured the three components separately and added them; I did not sit through a ten-take session on either arm.
The part that is not arithmetic is identity. Every finishing option in the hybrid path reads the same draft file, so they are necessarily the same person — that is why panels 1, 2 and 3 of Figure 3 match. Native has no such guarantee: changing the resolution changes the latent shape, which changes the noise, which gives you a different face for the same seed. The person you approved at 672p is not the person you get at 1344p.
So the hybrid path splits "which person" and "how detailed" into two decisions you make separately. Native welds them into one dice roll, and you re-roll both every time you change your mind about either.
## Bonus: VSR after the refine buys 2688×1536 for 9.4 s
This is not part of the core path — the method above is complete without it. But since VSR is sitting right there, and it now has real detail to work with:
49.7 s for 2688×1536, which is 9.4 s over the 40.3 s hybrid for 4× the pixels.
---
## Deep dive: most of the hybrid's cost is loading, not sampling
You can run the workflow without reading this section; everything above stands on its own. What follows is where the seconds go, what I cut, and the three places I deliberately diverged from NVIDIA's recipe.
### Gemma is 15.37 GiB of one constant string, and removing it saves 7.85 s
Stage 2 takes conditioning from a text encoder, which on a normal LTX workflow is reasonable. On this one it is not, because the stage-2 conditioning is a single constant string:
```text
4K, refined, high quality, cinematic detail, clean textures, natural motion.
```
Positive and negative are both wired to the same node output. Nothing varies per scene, per prompt or per seed — and loading `gemma4-12b-with-proj-ltx-2.5-comfy-int8-convrot` to produce it costs 15.37 GiB of residency on every single run.
NVIDIA never had this problem. Their config carries `"online_text_encoder": false`, because their pipeline precomputes the stage-2 conditioning once. The ComfyUI implementation has no such layer, so I added the cheap version of one: a small save/load-conditioning node pair that writes the tensor to disk once and reads it back thereafter.
| | Cold run |
|---|---:|
| with Gemma | 48.114 s |
| without Gemma | **40.260 s** |
| saved | 7.854 s (16.3%) |
Generating the cache costs 55.185 s, once, ever.
The output is not merely similar. Frame by frame, 121 of 121 frames are identical. The comparison was sanity-checked both ways. Baseline against itself returned "identical", so it can report a match; a different seed against the baseline returned "all 121 frames differ", so it catches one when there is one.
### 4× the pixels costs 2× the time, not 4×
Pure H3 generation, no upscale, 4 steps, three resolutions:
| Resolution | Pixels | 4 steps |
|---|---:|---:|
| 672×384 | 258k | 25.5 s |
| 960×544 | 522k | 28.9 s |
| 1344×768 | 1032k | 51.1 s |
Attention is quadratic in sequence length, so the naive expectation is that 4× the pixels costs a lot more than 4× the time. It costs 2×. In this size range the fixed costs — model loading, VAE, encode — are still large enough relative to sampling to flatten the curve.
That cuts against the hybrid path as much as for it. Drafting at a quarter of the pixels saves half the time, not three quarters, which is exactly why the single-shot gap is 11 s rather than the 30 s you would guess from the pixel counts.
### Two stacks need 56.2 GiB and the card has 31.84 GiB
Add up what has to be resident and the hybrid path wants 71.5 GiB with Gemma, 56.2 GiB without. A 32 GB RTX 5090 offers 31.84 GiB usable. That is 2.25× over with Gemma and 1.76× over without.
Stage 1 alone is 33.5 GiB, which does not fit either — so ComfyUI is already swapping the text encoder out within the H3 stage before stage 2 is even in the picture. Adding a second stack does not introduce swapping; it adds another round of it.
The cost shows up when you compare cold runs (models freed beforehand) against warm ones (nothing freed, only the seed changed):
| | Cold | Warm | Loading |
|---|---:|---:|---:|
| hybrid, with Gemma | 48.1 s | 32.2 s | 15.9 s |
| native, 4 steps | 51.5 s | 41.5 s | 10.0 s |
The hybrid path loses 5.9 s more to loading than native does, because it loads two stacks instead of one. Take loading out of both and hybrid is 27% faster than native, against the 6.6% it manages cold.
⚠️ The warm numbers are optimistic and the two arms are not strictly comparable: the warm runs reported `execution_cached` node counts of 18 and 10, so they skipped different amounts of work. Only the relative comparison — hybrid pays more for loading — survives that. Treat the absolute warm figures as a ceiling on what a persistent-model setup would give you, not as a measurement of one.
### Three deliberate departures from NVIDIA's recipe
**Stage 2 runs the distilled int8 checkpoint, not the official dev BF16.** 22B in BF16 is roughly 44 GB and does not fit on this card. `ltx-2.5-22b-distilled-transformer-int8-convrot` is equivalent to dev with the distill LoRA merged in, which means it is effectively strength 1.0 where the official recipe uses 0.8.
**The draft LoRA is lightx2v's `minimax_h3_fl2v_turbo_4step_v0.1_768p_sla`, not the official FastVideo VSA DataFree one.** The FastVideo LoRA is meant to pair with VSA sparse attention, and there is no VSA path on a 5090.
**There is no H3→LTX latent adapter in my chain.** NVIDIA has a learned one, [H3-to-LTX-Latent-Adapter](https://huggingface.co/Efficient-Large-Model/H3-to-LTX-Latent-Adapter), 389 MB, which maps H3 latents straight into LTX space and skips both a decode and an encode. I wrapped it as a ComfyUI node and ran it: every tensor shape lined up and the conversion itself takes 0.177 s. Total time on the 5090 did not improve, because the VAE round trip it removes is offset by the H3 latent upsampler it adds. It is a real win for memory — one fewer VAE encoder resident — just not on a card that swaps models every run anyway.
### Every second came from ComfyUI /history, and I ignore gaps under 4 s
All timings are `execution_success` minus `execution_start` from the ComfyUI `/history` endpoint, divided by 1000. Every run was checked for `execution_cached.nodes` being empty (cold) or had its length recorded (warm). Cold runs were preceded by:
```bash
curl -X POST http://:8188/free \
-H 'Content-Type: application/json' \
-d '{"unload_models":true,"free_memory":true}'
```
Run-to-run jitter in the same batch measured at about 4 s. The clearest evidence is a pair that should have gone the other way: the 672p native run took 25.5 s while the same run with VSR added took 21.9 s, and VSR can only add time. So I don't draw conclusions from gaps under 4 s. That is also why I read the 51.5 s native figure in the single-shot comparison and the 51.1 s in the resolution table as the same measurement.
---
*Also in this series: [Part 2 — Real-ESRGAN 109 s to RTX VSR 11.2 s](/en/blog/minimax-h3-rtx5090-speedup-vsr) · [Part 7 — LTX-2.5 vs MiniMax-H3 on one card](/en/blog/ltx25-vs-minimax-h3-rtx5090)*
---
# [vLLM] Qwen3.8-Flash-Next TP=2 on Two DGX Sparks: 51.9 tok/s
URL: https://ai-muninn.com/en/blog/qwen38-flash-next-tp2-two-dgx-sparks
Date: 2026-09-12
Series: DGX Spark (Part 46)
A second DGX Spark takes Qwen3.8-Flash-Next NVFP4 from 41.7 to 51.9 tok/s median decode, +24.5%, and the KV pool from 1,027,392 to 2,128,927 tokens, 2.07x. TTFT drops from 0.26 s to 0.17 s. Both machines need a full 124 GiB copy of the model: vLLM shards tensors after load, not files on disk. The interconnect is not the bottleneck — during decode it runs at 0.3% of the 185 Gb/s I measured, because only activations cross machines. Caveats: 51.9 is the median of three runs (56.6 / 51.7 / 51.9), and this deployment does not survive a reboot.
## Preface
Two movers carrying a couch each take half the weight, but they still walk the whole staircase and still have to match steps at every turn. That is roughly what a second DGX Spark does for decode: the weight reads split, the per-step overhead does not, and the result is +24.5% rather than +100%.
This is Part 46 of the DGX Spark series. The direct prerequisite is [Part 45](/en/blog/qwen38-flash-next-nvfp4-dgx-spark-vllm-recipe), which covers the single-node NVFP4 recipe — the checkpoint, the nine bind-mounted overlays, PLE modes, MTP, and where the 41.7 tok/s baseline comes from. I am not repeating any of it here.
This article covers what changes when you add the second machine, and the short version is two things: **bigger models fit** (242 GiB across the pair against 121 on one) **and it is faster**. Below: what it costs in disk and memory, how to cable two ConnectX-7 NICs without losing a day to a cable that turns out to be fine, and where the gain actually comes from.
## What you get: 242 GiB between them, 51.9 tok/s, a 2.07x KV pool
Look at the first row for speed and the second for capacity. The second row is the one that decides whether a model you could not load before will load now.
| measurement | one Spark (TP=1) | two Sparks (TP=2) |
|---|---|---|
| 40-prompt harness median decode | 41.7 tok/s | **51.9 tok/s (+24.5%)** |
⚠️ The two medians are not the same kind: **41.7 is the 40-prompt median of a single TP=1 run, while 51.9 is the median of three TP=2 runs, each itself a 40-prompt median.** The three were 56.6, 51.7 and 51.9, a 9.5% spread.
| TTFT, short prompt | 0.26 s | 0.17 s |
| KV cache pool | 1,027,392 tokens | 2,128,927 tokens (2.07x) |
Same checkpoint, same harness, thinking off, concurrency 1.
> I ran the TP=2 harness three times: 56.6, 51.7, 51.9. Median 51.9, spread 9.5%. My first pass computed the speedup off 56.6 and reported +35.7%, which is selective reporting — picking the best of three runs and comparing it to a single baseline. The headline is the median.
A per-prompt probe, same prompt text on both configurations and warmed up, shows where the gain lands. The third row is the one that needs a warning label.
| prompt type | one Spark | two Sparks |
|---|---|---|
| code | 45.25 tok/s | 61.79 tok/s |
| English prose | 28.16 tok/s | 37.87 tok/s |
| Traditional Chinese prose | 15.24 tok/s | 33.16 tok/s |
The throughput gain on Chinese prose is the largest in the table, and it is **not** a TP=2 result. The two configurations also differ in PLE mode, and the MTP draft head reads the PLE table: the single node ran `PLE_MODE=staged` (table on disk, fetched row by row), the two-node configuration uses `PLE_MODE=none`. The single-variable test — one node with `PLE_MODE=none` — has not been run. Until it is, that row is an observation after a configuration change, not a tensor-parallel gain.
## Both machines need a full copy: disk x2, memory x2
This is where most people get it wrong, so it goes first. vLLM cross-node tensor parallel does not put half the weights on each node. Sharding happens after load, at the tensor level, which means **every node needs a full copy of the model directory**.
The second row is the one that surprises people who sized their disks for "half the model each".
| requirement | value for this recipe |
|---|---|
| memory budget | 121 GiB `MemTotal` per node x 2 = 242 GiB, not pooled (OS and CPU share it — measure available separately) |
| disk | 124 GiB (132.7 GB) per node = **265 GB total** |
| container image | 22.2 GB, on both machines |
| driver / kernel | identical on both; mine are 580.173.02 and 6.17.0-1032-nvidia |
| launcher script | byte-identical on both; verify with `sha256sum` |
Two of those rows have failure modes worth naming. If the worker is missing the container image, it stalls in `docker pull` for ten-plus minutes and from the head you see nothing except a rank that never joins. And the launcher script has to actually match: I edited only the head, `scp` silently failed to land the file on the worker, `bash -n` passed against the stale copy, and the worker exited with `LANE must be A or B`. A syntax check does not catch a file that never arrived.
Copying the weights over the ConnectX-7 link took 2 min 43 s at 812 MB/s. The bottleneck there is ssh's AES, not the cable — the link was 4% used.
```bash
rsync -a --info=progress2 -e "ssh -c aes128-gcm@openssh.com" \
/home/coolthor/models/qwen38-fn-nvfp4-nvidia/ \
sleipnir-2:/home/coolthor/models/qwen38-fn-nvfp4-nvidia/
# then, on both nodes:
sha256sum ~/patches/*.sh
```
## Cabling: one port is two interfaces, and RoCEv2 needs the IPv4 GID entry
The official procedure is NVIDIA's [connect-two-sparks playbook](https://github.com/NVIDIA/dgx-spark-playbooks/tree/main/nvidia/connect-two-sparks), and it works. Three things in it are easy to get wrong, and each one produces a symptom that looks like broken hardware.
First, use the interface pair that `ibdev2netdev` reports as `(Up)`. On port 0 that is `enp1s0f0np0` and `enP2p1s0f0np0`.
Second, those two names are not a typo. **One physical port exposes two logical interfaces across two PCIe domains, and both need an IP address to get full bandwidth.** That is why the official measurement procedure runs two streams and adds them. Configure one and you get half, then start blaming the cable.
```yaml
# /etc/netplan/40-cx7.yaml (chmod 600; the other machine uses .13)
network:
version: 2
renderer: NetworkManager
ethernets:
enp1s0f0np0:
addresses: [192.168.200.12/24]
enP2p1s0f0np0:
addresses: [192.168.201.12/24]
```
Third, the RoCEv2 GID index only exists once IPv4 is configured. On my machine the table then looks like this:
```
0 link-local RoCEv1
1 link-local RoCEv2
2 IPv4 RoCEv1
3 IPv4 RoCEv2 <- RoCEv2 needs this one
```
⚠️ Index 3 is **not** universal — the table is built from whichever addresses are actually configured, so add IPv6 and you get more entries. Read your own table and match on address family and type.
Until an IPv4 address is assigned, only entries 0 and 1 exist, and RoCEv2 then fails with `Failed to modify QP to RTR` and `Unable to Connect the HCA's through the link`. That message reads like a dead NIC or a dead cable. On my pair it meant IP was not configured yet.
MTU does not need changing. NVIDIA's own example output shows `Mtu : 1024[B]` (netdev 1500) reaching 92 Gb/s. I had assumed 9000 was the last untouched knob, and it was the wrong direction entirely.
Verify with two streams and add them:
```bash
# NVIDIA's procedure is four terminals on two port pairs, running at the same time.
# On the far node, one server per interface:
ib_write_bw -d rocep1s0f0 -p 12000 -D 12 --report_gbits
ib_write_bw -d roceP2p1s0f0 -p 12001 -D 12 --report_gbits
# On this node, both clients concurrently:
ib_write_bw -d rocep1s0f0 -p 12000 -D 12 --report_gbits
ib_write_bw -d roceP2p1s0f0 -p 12001 -D 12 --report_gbits
```
🔴 **The two streams have to overlap.** Run them one after another and each will approach its own single-link ceiling, so the sum means nothing.
Mine: **92.57 Gb/s each, 185.14 Gb/s aggregate.** That 92.57 is the same number as NVIDIA's documented example output for NIC1, so it is the expected result rather than a good one.
That number has a PCIe explanation, and it is the same two-domain story as above: `lspci -vv` shows the CX7 at `Speed 32GT/s, Width x4` **per link**, and dmesg prints `126.028 Gb/s available PCIe bandwidth` for one of them. No single stream gets past about 126 Gb/s, which is exactly why the aggregate has to come from two. NVIDIA's own documented example is asymmetric for the same reason: 92.57 + 97.28 = 189.85 Gb/s.
## Start the worker first, then the head
I used the recipe author's SPEED profile (Kai / Tech2Wild) and changed four environment values: the CX7 addresses, `NCCL_IB_ADDR_RANGE` (pointed at the CX7 subnet, the `192.168.200.x` side here), `--served-model-name` so the server accepts requests under two model IDs, and `MODEL_HOST`.
```bash
# SPEED profile, unchanged from the recipe
PLE_MODE=none GRAPHS=nocompile MTP=3 SEQS=6 CHUNK=4096 \
KV=fp8_e4m3 GMU=0.70 MAXLEN=262144
# the paths I changed
MODEL_HOST=/home/coolthor/models/qwen38-fn-nvfp4-nvidia
```
Order matters. **Start the worker first** — it runs `--headless` and exposes no API — **then the head.** Reversed, the head cannot find the second rank.
🔴 Do not set `GRAPHS=compile`. Inductor's autotune duplicates the n-gram table, which costs roughly **24 GiB per rank at TP=2**; the author's script comment records this starving and rebooting two Sparks on 2026-09-05. With `nocompile`, `mem_avail` settles at 25-27 GB.
## Verify with a completion, not /health
`/health` answering proves the head's web server is up and nothing else. Send a real request instead:
```bash
curl -s http://:8000/v1/chat/completions \
-H 'Content-Type: application/json' \
-d '{"model":"qwen38-flash-next",
"messages":[{"role":"user","content":"Say hello in one sentence."}],
"temperature":0, "max_tokens":64}'
```
**TP=2 cannot serve with one rank missing, so the head answering at all proves both machines are alive.** That is a stronger signal than pinging both boxes: my Tailscale path intermittently degrades to 200 ms RTT, and ping keeps succeeding through that.
One log line looks alarming and is not. `distributed_init_method=tcp://:29533` is the rendezvous bootstrap channel, not the data path. Seeing `tcp` there does not mean NCCL fell back to sockets.
## Deep dive: debugging notes
You can stop here if you just want TP=2 running — everything above is the working recipe. What follows is where the time went, which measurements settled which question, and two conclusions I published and had to withdraw.
## Why was a working cable only doing 13 Gb/s?
Three signals said the hardware layer was fine. Both ends negotiated 200 Gb/s. `ibdev2netdev` showed both interfaces `(Up)`. `ib_write_lat` reported t_typical of **1.99 µs**, completely normal. And `ib_write_bw` gave 13.2-13.9 Gb/s, 6.7% of line rate.
**What I expected, and why you might expect the same:** I read those three green signals as "the physical layer is healthy, so this is a configuration problem", and spent the afternoon on QP count, message size, memlock and MTU. The hole in that reading is that `ethtool`'s 200000 Mb/s is a *negotiated link speed* and `ib_write_lat`'s 1.99 µs is a *single-operation latency*. Neither one measures throughput. None of the three green signals was looking at the thing I cared about.
The cable was the obvious suspect. `ethtool -m` reports it as an OEM `Q112P-400G-0.5M` — I could not find a manufacturer page for that part number, so treat it as what the module claims about itself — and it is not on NVIDIA's approved list (approved are Amphenol NJAAKK0006 and Luxshare LMTQF022-SD-R). An unapproved copper DAC barely holding 200G on FEC is a very plausible story, so I checked the FEC counters over 5 seconds of traffic.
| counter | delta over 5 s |
|---|---|
| `rx_corrected_bits_phy` | +10,214 |
| `rx_err_lane_0` | +2,209 |
| `rx_err_lane_1` | +8,005 |
| `rx_pcs_symbol_err_phy` | **0** |
That last row acquits the cable: every error was corrected by RS-FEC and nothing reached the packet layer. ⚠️ I originally divided by application throughput to get a pre-FEC BER of about 1.5e-7. That denominator is wrong — the counter wants physical bits, and the same deltas against a 200 Gb/s line rate land nearer 1.0e-8. **Naming a BER needs the matching physical-bit delta, which I did not capture.** What I can say is that every error was corrected and the cable was fine.
It was also insensitive to every knob: 1QP/64KB 13.49, 8QP/64KB 13.25, 1QP/1MB 13.30, 4QP/256KB 13.24, memlock unlimited 13.46. TCP was equally slow (iperf3, 8 streams: 15.9 Gb/s, zero retransmits), so this was not RDMA-specific. Loopback on a single machine ran **11.43 Gb/s** — slow with the cable entirely out of the path.
The decisive measurement was the PHY byte counters. Over a 10-second transfer the sender's `tx_bytes_phy` rose by only 17.86 GB, which is 14.3 Gb/s. The receiver's `rx_bytes_phy` rose by exactly the same amount, and `tx_discards_phy`, `rx_discards_phy`, `rx_pause_ctrl_phy` and `rx_out_of_buffer` were all 0. Nothing was being dropped. The NIC simply never sent more.
That pair of counters separates two causes that look identical from outside, because both present as low bandwidth:
- small `tx_bytes_phy` delta, zero discards → the host is not sending
- large `tx_bytes_phy` delta, nonzero discards → it is sending and the path is dropping
Root cause, from NVIDIA developer forum threads 363461, 370035 and 373538: **after plugging or re-seating a QSFP cable, the system can stay in a degraded state until it is rebooted.** One case went from 13.39/13.76 to 98.01/98.01 after a reboot (thread 363461, post 10). ⚠️ The successful report in thread 373538 explicitly describes a **full power drain**, not just a reboot — do not collapse the two. And the comment that the dmesg line `Detected insufficient power on the PCIe slot (27W)` is cosmetic came from forum user `mashie`, whose profile carries no NVIDIA staff flag, so read it as one participant's view rather than an official position.
After my reboot: 92.57 x 2 = 185.14 Gb/s. Re-verified after a later driver upgrade: 92.56 x 2 = 185.12.
## Why did netplan generate fail on a file I never wrote?
The official cabling procedure has you write a netplan file. `netplan generate` then failed outright on both machines:
```
Invalid YAML: control characters are not allowed
```
The culprit was not my file. It was `/etc/netplan/90-NM-2edf06d6-....yaml`: **715 bytes of all-NUL**, same filename, same size and the same 2025-09-29 factory date on both machines. That UUID is not in either machine's NetworkManager connection list, so it is an orphan. Moving it out of `/etc/netplan/` unblocks everything.
There is a related red herring: `netplan get renderer` crashes with a `UnicodeDecodeError`, which looks like netplan itself is broken. It is the CLI failing to decode while printing the parse error above.
## The interconnect sits at 0.3% during inference
I measured this with PHY byte counters rather than inferring it from the absence of NCCL warnings. `NCCL_DEBUG=WARN` only prints when something is wrong, so silence is not evidence.
Over 99 seconds of inference the ConnectX-7 moved **6.87 GB, about 0.555 Gb/s** — 0.3% of the 185 Gb/s link. Discards stayed at 0 throughout, and the worker's tx matched the head's rx exactly.
The mechanism: single-stream decode exchanges **activations** across machines, not weights. Weight reads are local, each node reading its own half; the cross-machine traffic is one hidden-dimension tensor per step. Three orders of magnitude apart.
This also explains a knob that did nothing. `NCCL_CHANNELS=8` is pinned to 8 in TJ Klug's two-Spark recipe, and here it made no measurable difference: a link running at 0.3% has nothing for eight channels to carry.
## Effective weight bandwidth lands at 1.41x, and the link is not the limit
If decode were purely weight reads and the weights split exactly in half, the speedup should approach 2. It does not. Measured effective weight bandwidth, using MTP-disabled runs as a proxy, came out at **1.41x**, and the ratio held to within 0.2% across three prompt types.
The link's throughput is not the explanation: the 0.3% figure above rules that out. It does **not** rule out collective latency or synchronisation cost — that needs latency profiling I have not done.
Where it might be, in order of how much I would bet on each:
1. fixed per-step overhead — kernel launch, scheduling, the fixed cost of all-reduce
2. the difference in PLE mode and `gpu-memory-utilization` between the two configurations
**To tell those apart I need one more test: one node, `PLE_MODE=none`, MTP off.** I have not run it. So for now the missing 0.59x can only be described as "not the network".
> **Retracted.** I previously wrote up a step-time decomposition — 34 ms weight read plus 20 ms other — as established. It assumed all-reduce was approximately zero, and cross-checking it against 9.27 GiB/token produced an implied per-rank bandwidth that did not hold. Two measurement points cannot solve three unknowns.
## Five config variants, all inside my own run-to-run spread
The recipe author's results directory holds 84 JSON files, 69 of them complete 40-prompt harness runs, which means the remaining knobs can be looked up instead of re-measured. TP=2 medians from that corpus, against mine:
| configuration | TP=2 median |
|---|---|
| `speed_mtp4_ixs` (MTP=4 + index share) | 55.2 |
| `ram_mirror` | 53.7 |
| `speed_dv64k` (reduced-vocabulary drafting) | 53.2 |
| `speed_async` (`ASYNC_SCHED=1`) | 52.4 |
| `speed_nccl8` (`NCCL_CHANNELS=8`) | 51.9 |
| my SPEED config | 51.9 (single best 56.6) |
My own three runs spanned 51.7 to 56.6, a 9.5% spread, so every gap in that table is smaller than my run-to-run variation — and my single best 56.6 is my own local number rather than part of that corpus, whose highest TP=2 concurrency-1 median is 55.2. Nothing in those 69 runs is cleanly faster than what I am already running.
You can trade speed for a much larger KV cache. The CONTEXT profile (`PLE_MODE=mmap GRAPHS=piecewise MTP=4 SEQS=8 GMU=0.80`) pushes the KV pool to **5.87M tokens** at the cost of dropping to 35.8 tok/s.
## The 0.046 quality drop is not a TP=2 cost
My harness auto_score went from 0.889 on the single node to 0.843 at TP=2, a 5.2% drop. All three TP=2 reruns returned exactly 0.843, spread 0.000, and I declared the quality cost real on that basis.
That was wrong. Reproducibility only proves the number is deterministic for that configuration. It says nothing about whether the gap *between* configurations means anything.
Those 69 runs settle it:
| set | auto_score range |
|---|---|
| TP=1 configurations | 0.815 - 0.919 (span 0.104) |
| TP=2 configurations | 0.821 - 0.906 |
The ranges almost entirely overlap. One TP=1 run at 0.815 sits below my TP=2 result, and three TP=2 runs at 0.906 sit above my TP=1 result. A 0.046 gap is smaller than the normal variation between configurations on either side.
## Remote operation with no BMC: the rollback path does not exist
These two machines sit in an office. There is no BMC. That makes one thing worth checking before any kernel or driver work, and it failed for me:
```bash
modinfo -k -F version nvidia
# ERROR: Module nvidia not found
```
After the kernel upgrade `/boot` still holds the old `vmlinuz`, so GRUB offers the old kernel — but the module package was removed, so booting it gets you a machine that cannot see its GPU. The rollback path looks like it exists and does not. The only real safety net is touching one machine at a time.
Tailscale degrades rather than disconnecting, which is its own trap. Ping keeps succeeding while RTT goes from 3 ms to 120-200 ms and the SSH handshake times out. That is the signature of falling back to a DERP relay, not a machine fault. To tell them apart, ssh a node at a different location first. To work around it, drive the worker from the head over the ConnectX-7 link.
Last one, still open: TP=2 does not survive a reboot. Both nodes run a manual `docker run --restart no`, and the systemd unit for the single-node deployment is still enabled, so rebooting the head silently reverts to one machine. Not fixed yet.
## Takeaways
Two things here transfer outside this hardware.
When you see low bandwidth, first separate **"not sending"** from **"sending but dropping"**. PHY byte counters plus discard counters cut cleanly between them, and that split applies to any network bottleneck, not just RDMA. It is what ended the cable investigation, and it would have ended it hours earlier.
A liveness probe should key on a signal that *must* visibly break. The head answering a completion proves both ranks are present, because TP=2 cannot serve without both; pinging each machine gets fooled by the Tailscale degradation described above.
And the bottom line on the second machine: 121 GiB becomes 242, the KV pool goes 2.07x, decode goes +24.5%, and the link still has 99.7% spare. **Both things hold at once: a model that would not fit now fits, and it runs faster.** If you expected decode to double, it does not. Capacity, bandwidth and headroom all do.
---
# [Benchmark] LTX-2.5 vs MiniMax-H3 on one RTX 5090: 29s vs 81s for the same Chinese dialogue clip
URL: https://ai-muninn.com/en/blog/ltx25-vs-minimax-h3-rtx5090
Date: 2026-09-11
Series: MiniMax-H3 on RTX 5090 (Part 7)
Same RTX 5090, same Simplified Chinese line, same ComfyUI: **LTX-2.5 finishes in 28.67 s, MiniMax-H3 in 81.22 s**, and both come back at ASR character error rate 0%. The gap is per-pass cost, not step count, since LTX runs 11 forward passes and H3 runs 9. LTX also lands at −10.4 LUFS where H3 sits at −30 to −34, so H3 needs a gain stage before anything ships. On two speakers LTX dropped two characters (CER 9.52%) while H3 stayed word for word. Neither leaves headroom: peaks of 31,736 and 31,811 MiB on a 32,607 MiB card. One script, one scene, n=1.
*First half is MiniMax-H3, second half is LTX-2.5, same two-speaker script, both loudness-matched to −16 LUFS before concatenation.*
## Preface
Two kitchens, one bowl of soup. The fast one puts it in front of you in four minutes and gets a word of the order wrong. The slow one takes twelve and reads your order back to you exactly as you said it.
Part 1 of this series got MiniMax-H3 onto a single RTX 5090. Part 6 put two characters into one shot with Ref2VA. Lightricks then shipped LTX-2.5 with synchronised audio, which makes it the first local model that competes with H3 on the thing H3 was interesting for: dialogue that comes out of the same forward pass as the picture.
So I ran both on the same card, with the same Chinese script, and measured what each one gives up.
---
## 28.67 s vs 81.22 s for the same line
One RTX 5090, 32,607 MiB total. ComfyUI. Both models local, no API in the path.
The test line is single-speaker, Simplified Chinese, 25 characters, about 5.17 s of speech. Identical text into both models:
```text
今天的汤头特别浓,先喝一口暖暖身子,再慢慢告诉我你的故事。
```
The row that matters below is `Whole flow`, which is sampling plus load, decode and save:
| | MiniMax-H3 | LTX-2.5 |
|---|---|---|
| Resolution, frames | 1344×768, 124 | 1280×704, 121 |
| Steps | 14 + Spectrum | 8 + 3, two-stage |
| Sampling | 66.40 s | 14.31 s |
| Whole flow | **81.22 s** | **28.67 s** |
| ASR character error rate | 0% | 0% |
Both models transcribe back cleanly, so on this line the machine gate does not separate them. The wall clock does.
One thing that keeps this from being a clean subtraction: the two models want different shapes, and I let each one run at its own native size. LTX's pixel-times-frame load comes to about 85% of H3's. That is not enough to explain a 3x gap, but it does mean you cannot read the difference as a pure engine comparison.

Same line, same card. H3 on top, LTX-2.5 below. The two scenes are separately generated, not two renders of one frame.
## 11 forward passes vs 9, so the gap is per-pass cost
The obvious first guess is that H3 is simply doing more work per clip. It is not, and the step counts say so.
LTX-2.5 runs two stages, 8 steps then 3, so 11 forward passes through the transformer.
H3 runs 14 steps, but Spectrum is on. Spectrum is H3's step-skipping scheduler: it keeps a short history of previous steps and forecasts some of them instead of actually running them. On this configuration it forecast 5, which leaves 9 real passes.
Eleven vs nine is close enough to call a tie. The 3x wall-clock gap therefore has to live in what one pass costs, not in how many there are. That number turns out to be around 5 s per actual pass for H3, which I take apart in the deep dive.
## H3 comes out 15-20 dB under normal loudness, LTX does not
LUFS is the loudness unit broadcast normalisation uses. Zero is the ceiling and more negative is quieter, so a number like −30 means the file is very quiet in a way a peak meter will not warn you about.
On this run, H3's clip measured −25.1 LUFS integrated and LTX's measured −10.4. Across the runs I have done, H3's native output sits between −30 and −34 LUFS, which is 15 to 20 dB below normal content. Anything you publish needs a gain stage in front of it.
LTX at −10.4 is close enough to normal that the step disappears. That is one fewer node in the graph and one fewer thing to forget before you upload.
## 1344×768 is arithmetic, not preference
Every H3 recipe you will find uses 1344×768, and it looks like a community convention. It is not. It is what you get when you satisfy two constraints at once:
```text
short edge 768 (MiniMax model card default)
16:9 would want 768 × 16/9 = 1365.333… (not even an integer)
ComfyUI path both dimensions divisible by 32
1365.333 / 32 = 42.666… -> round down to 42
42 × 32 = 1344
```
Worth being precise about what that leaves you with: 1344 / 768 = 1.75, which is **7:4, not 16:9**. The 16:9 width at this short edge is not reachable, so 1344 is the nearest legal value below it.
Two independent sources land on the same shape, which is a decent sign the derivation is not just mine: NVIDIA's Sol-Engine benchmark runs H3 at 1344×768 by 124 frames, and FastVideo's H3 distillation was trained at 768×1344 by 124 frames.
## Frame counts do not port between the two models
If you try to hold frame count constant across the comparison you will hit an error, because the two models count frames on different grids.
LTX-2.5 requires `frames % 8 == 1`. So 121 works, since 121 is 15×8+1. 124 is rejected outright.
H3 uses a 17k+5 grid, where 124 is 17×7+5.
The grids do intersect — 73, 209 and 345 satisfy both rules, and 209 is 26×8+1 as well as 12×17+5 — but none of those sit near either model's native working point. I ran each at a legal value close to 5 seconds and noted the gap instead.
## Five files from Lightricks/LTX-2.5, and three ways to download the wrong ones
Everything for LTX-2.5 comes from one repository, [Lightricks/LTX-2.5](https://huggingface.co/Lightricks/LTX-2.5). On-disk sizes:
| File | Size |
|---|---|
| `diffusion_models/ltx-2.5-22b-distilled-transformer-comfy-int8-convrot.safetensors` | 20.03 GiB |
| `text_encoders/gemma4-12b-with-proj-ltx-2.5-comfy-int8-convrot.safetensors` | 14.32 GiB |
| `vae/ltx-2.5-video-vae-conv-bf16.safetensors` | 1.35 GiB |
| `vae/ltx-2.5-audio-vae-bf16.safetensors` | 0.34 GiB |
| `latent_upscale_models/ltx-2.5-latent-spatial-upscaler-x2-bf16-1.0.safetensors` | 0.93 GiB |
Three places to get this wrong:
- **Take `distilled`, not `dev`.** The dev transformer produced melted-looking output at both quantizations I tried. It is not a quality-versus-speed trade in this graph, it is a broken picture.
- **Take the `conv` video VAE.** A third-party measurement on a 5090 puts it 22.5% faster overall, with decode falling from 8.91 s to 4.68 s and peak VRAM essentially flat (31,692 MB to 31,728 MB, up 36 MB). Free.
- **The latent upscaler is not optional.** The official blueprint samples in two stages with `LTXVLatentUpsampler` at ×2 sitting between them. Skip the file and you have no second stage to run.
## The official sampler settings, and the wiring mistake that raises `split_with_sizes`
These come straight out of the ComfyUI blueprint in [Comfy-Org/workflow_templates](https://github.com/Comfy-Org/workflow_templates), and I did not tune any of them:
```text
sampler euler_ancestral
guider LTXVDualCFGGuider [1, 1]
stage-1 sigmas 1.0, 0.99375, 0.9875, 0.98125, 0.975, 0.909375, 0.725, 0.421875, 0.0 (8 steps)
stage-2 sigmas 0.85, 0.7250, 0.4219, 0.0 (3 steps)
conditioning LTXVConditioning [24]
decode VAEDecodeTiled [512, 64, 64, 16] + LTXVAudioVAEDecode
AV latent LTXVSeparateAVLatent / LTXVConcatAVLatent
```
The last line is the one that bites. Audio and video travel as a single combined latent and have to be split before decode and concatenated after. If you wire that chain wrong, the error you get is `split_with_sizes`, which reads like a tensor-shape problem and is actually a graph-topology problem.
## LTX names the speaker in the sentence, H3 tags them and keeps identity elsewhere
The two models take dialogue in shapes that do not convert into each other.
LTX-2.5 has a template that puts the line in quotes and names the language. One caveat first, because I got this wrong on the way in: that template lives in the **Dub-It (speech replacement)** section of the docs, and that section opens with "Unlike text-to-video generation". I read it as the general dialogue syntax. It isn't. For text-to-video there is no equally specific official template.
The template:
```text
[Speaker] is speaking [Language/Accent], saying: "[Dialogue]"
```
The model card lists nine languages including Chinese. Cantonese is not one of them.
H3 uses positional tags, `(S1)` and `(S2)`, and this is where people lose an afternoon: the tag carries no identity at all. It is a pointer. Who S1 is gets established in the subject description, like ` (S1), a young woman with shoulder-length black hair…`, and if you never say who S1 is then the model invents someone. `(S1,S2)` means both speaking at once.
## Two speakers: LTX 29.21 s at CER 9.52%, H3 94.82 s at CER 0%
Same scene, two lines, two voices:
```text
S1 young woman 这碗汤是你煮的吗,闻起来好香。
S2 middle-aged man 是我煮的,趁热喝吧。
```
Look at the bottom two rows, because that is where the models finally separate:
| | MiniMax-H3 | LTX-2.5 |
|---|---|---|
| Sampling | 67.94 s | 14.34 s |
| Whole flow | 94.82 s | 29.21 s |
| Peak VRAM | 31,811 MiB | 31,729 MiB |
| S1 / S2 character error rate | 0% / 0% | 15.38% / 0% |
| Total character error rate | **0%** | **9.52%** |
LTX stays about 3x faster with a second voice in the scene. It also stops being free.
## Four signals say both models really alternate, and none of them rules out overlap
I had read the single-speaker guidance as a model-wide limit, so the first question was whether the second voice was real or whether one voice was doing an impression while both mouths flapped. I checked four things that fail in different ways:
- **ASR timestamps do not overlap.** H3 puts S1 at 0.00-2.40 s and S2 at 3.02-4.88 s. LTX puts S1 at 0.00-1.54 s and S2 at 2.56-4.84 s.
- **Frame-by-frame mouth attribution is correct.** On the LTX clip, from 0 to 1.4 s the woman's mouth is moving and the man's is mostly closed; from 2 to 4.8 s the man is speaking and the woman is closed.
- **The handover goes quiet.** A 20 ms RMS envelope at the switch reads 0.000296 for H3 and 0.000646 for LTX, each about 1.1 to 1.2% of the preceding line's mean level.
- **Pitch medians drop where they should.** H3 goes from 242 Hz to 104 Hz between the lines, LTX from 286 Hz to 130 Hz.
Where that stops being evidence: a single mixed-audio envelope cannot separate two speakers, only measure the sum. The transcriber can miss overlapping speech entirely, which is the exact failure I was testing for. A measurable pause is not the same claim as no overlap in any millisecond. And pitch medians say something about register, never about voice identity. One script, one scene, n=1 for each model.
## LTX drops 「这碗」 and padding silence does not bring it back
The 15.38% on LTX's first line is two characters at the very start, 「这碗」. That position is suspicious, because transcription heads routinely clip the beginning of a file.
So I padded 0.75 s of silence before and after the audio and re-ran ASR. The same two characters went missing. That makes a head-boundary artifact unlikely and points at the generation.
H3 got both lines word for word on the same script.
## Neither model leaves headroom: 871 and 796 MiB free
| | Peak | Free on a 32,607 MiB card |
|---|---|---|
| LTX-2.5 | 31,736 MiB | 871 MiB |
| MiniMax-H3, two speakers | 31,811 MiB | 796 MiB |
Under 900 MiB of slack in both cases, which means neither model is the light one. Third-party reports put LTX-2.5 into the 32 GB wall at 8 seconds of 720p, and my own runs agree that about 10 seconds is the practical ceiling for a single generation on this card.
---
## Deep dive: where the VRAM peak actually sits
You can use either model without reading any of this. The first act said neither model leaves 900 MiB. This is how that number was measured, and what happened when I tried to push it down.
### LTX's VRAM peak sits in stage-2 sampling, so smaller decode tiles miss it
LTX-2.5 leaves 871 MiB free. `VAEDecodeTiled` runs a 512 tile and is the easiest knob to reach, so the first thing worth knowing is which node actually holds the peak.
The measurement: that run kept 123 VRAM samples and 114 execution events, and the events carry `elapsed_s`. Line the two timelines up and each node interval gets its own peak.
| Node | Interval peak |
|---|---:|
| `CLIPTextEncode` | 19,032 MiB |
| `UNETLoader` | 16,632 MiB |
| **stage-1 sampling** | **31,653 MiB** |
| `LTXVLatentUpsampler` | 31,466 MiB |
| **stage-2 sampling** | **31,736 MiB** |
| `VAEDecodeTiled` | 30,873 MiB |
| `SaveVideo` | 27,193 MiB |
The peak is in stage-2, with stage-1 only 83 MiB behind it. **Both sampling stages sit at the ceiling and decode is below both**, so shrinking the tile cannot reach the number that matters.
The same table answers a related question. Text encoding peaks at 19,032 MiB and drops to 16,632 once the transformer loads, which means the text encoder unloads before sampling begins. **Swapping it for a smaller quantization does nothing for the sampling peak.**
### NVFP4 is 2.59 GiB smaller on disk and 72 MiB larger at the peak
Weights stay resident through sampling, so a smaller checkpoint is the next thing to measure. The same repository ships an NVFP4 variant at 18,721,548,408 bytes, 2.59 GiB below int8-convrot.
That variant used to fail with a dimension mismatch at the sampling stage. The checkpoint's `__metadata__` was missing `_quantization_metadata`, so ComfyUI silently dropped the quantization scale tensors and fed packed FP4 weights straight into the linear layer. Lightricks says on the HF discussion thread that it is fixed. ⚠️ **I cannot independently confirm "re-upload only, no code change"** — I inferred it from the ComfyUI-side issue still being open, not from a file revision diff. Either way, a local copy downloaded early needs checking.
You can check the header with two HTTP range requests instead of pulling the whole 18 GB. A safetensors file starts with an 8-byte little-endian u64 header length followed by that many bytes of JSON, so **before** downloading you can pull bytes 0-7 for the length and then that slice of JSON over HTTP range requests. **After** downloading, the same parse runs on the local file:
```python
import struct, json
with open(path, 'rb') as f:
n = struct.unpack('
There is a moment in every stock-photo search where you notice that none of these people work at your company. Preset TTS voices have the same problem, and it gets worse the more specific your voice is.
Narration sits on top of something you wrote, and the voice reading it is part of what people recognise. Narration sits on top of something you wrote, and the voice reading it is part of what people recognise. So I went looking, and I started with the defaults.
I did try the presets first. macOS ships `say -v Meijia`, which runs at 4.7 characters per second and is too slow to listen to. I auditioned preset voice libraries after that, and they all still sound unmistakably like a machine reading. There was no setting that would fix it, because what was missing was not a setting. So the route left was to clone my own voice, and the surprise is how little that takes.
## Zero-shot cloning is not training, so there is nothing to prepare but one recording
No fine-tune. No hour-long recording. No weight update, no GPU rental, no waiting.
You hand the model two things: a recording of your voice, and that recording's exact transcript. It extracts timbre and delivery from the pair, then applies both to whatever new text you give it. That is the entire mechanism, and it runs in the same call that produces the audio.
One consequence falls straight out of this and shapes everything downstream. Because the model aligns the audio against the transcript, the two must match word for word. That is why a stumble means re-recording the whole take. You cannot trim the audio to fix a mistake without breaking the alignment, and you cannot fix the transcript to describe what you actually said without changing what the model thinks each sound corresponds to.
## Install two packages, and let the model download itself on first run
```bash
python3 -m venv .venv && source .venv/bin/activate
pip install mlx-audio soundfile
```
That is the whole install. [`mlx-audio`](https://github.com/Blaizzy/mlx-audio) pulls in MLX, Apple's machine learning framework, which uses the Apple Silicon GPU directly. My versions: mlx 0.31.1, mlx-audio 0.5.1, Python 3.14 arm64.
The model weights are not in the package. The first `load_model` call pulls them from Hugging Face and caches them, so budget a download on your first run and nothing after that.
## Record 20 to 30 seconds in one take, in the voice you actually talk in
Quiet room. Air conditioning not blowing at you. No background music. The MacBook's built-in mic is enough; I never used an external one. Sit about 15 to 20 cm from it.
Speak at your normal pace and volume, the way you would explain something to one person sitting across from you. Not a broadcast voice. Whatever you do here is what every sentence the model generates will sound like, so performing a voice you don't normally use means committing to it for the rest of the project. Twenty to thirty seconds is the target. Mine is 23.9 seconds.
Find the mic index first:
```bash
ffmpeg -f avfoundation -list_devices true -i ""
```
Mine reports `[1] MacBook Pro的麥克風`. Then record, trim the silence, and check the levels:
```bash
# the leading colon means audio only, no video device
ffmpeg -f avfoundation -i ":1" -t 30 -ac 1 -ar 24000 ref_raw.wav
ffmpeg -i ref_raw.wav -ac 1 -ar 24000 \
-af "silenceremove=start_periods=1:start_threshold=-45dB:stop_periods=-1:stop_threshold=-45dB" \
ref.wav
ffmpeg -i ref.wav -af volumedetect -f null /dev/null 2>&1 | grep volume
```
Mine comes back at `mean_volume: -29.6 dB` and `max_volume: -10.7 dB`. A peak between -6 and -12 dB is the range you want: loud enough that the quiet parts carry, far enough from zero that nothing clips.
## Write your own reference text, and put the English terms in it
Write your own reference text rather than reading a standard passage. The point is coverage: it should contain the kinds of words you will actually be narrating.
Mine deliberately includes English technical terms in the middle of Chinese sentences — GPU, token, `llama.cpp` — because that is what my narration is full of. Read a clean literary passage into the mic and the model has never heard you switch languages mid-sentence, which is exactly the moment it will sound least like you.
Save that text to `ref_text.txt`, exactly as you said it. This file and `ref.wav` are a pair from here on.
## The whole clone is ten lines of Python
```python
from mlx_audio.tts.utils import load_model
import soundfile as sf
model = load_model("mlx-community/Qwen3-TTS-12Hz-1.7B-Base-8bit")
ref_text = open("ref_text.txt", encoding="utf-8").read().strip()
results = list(model.generate(
text="",
ref_audio="ref.wav",
ref_text=ref_text,
lang_code="auto",
split_pattern="",
verbose=False,
))
r = results[-1]
sf.write("out.wav", r.audio, r.sample_rate, subtype="PCM_16")
```
`generate` is a generator, so it needs `list()` around it, and the audio you want is the last item. `split_pattern=""` turns off the library's own text splitting, which matters because I do my own splitting one sentence at a time.
## Two names in that snippet cost me time: `12Hz` and `Base`
The model name contains `12Hz`. The full name is [`Qwen3-TTS-12Hz-1.7B-Base`](https://huggingface.co/mlx-community/Qwen3-TTS-12Hz-1.7B-Base-8bit), and those four characters are load-bearing. Leave them out and the call returns 401.
A 401 reads like an authentication problem. So you go check your Hugging Face token, then your login, then whether the repo is gated — and the actual fix is in the string you typed. If you get a 401 from this model, read the name character by character before you touch anything else.
The second name is `Base`, and it does cloning only. It has no preset voices at all. Preset voices live in the `CustomVoice` variant, and the two have different APIs, so code written against one will not run against the other. If you want presets rather than your own voice, you are downloading a different model, not passing a different argument.
## 83 seconds of narration takes 51 seconds, on the laptop
Faster than realtime, with no GPU machine involved anywhere in the path. That number is what makes the rest of the workflow practical: at this speed, regenerating a line is cheaper than deciding whether to regenerate it.
Know the pacing before you write a script, not after. My clone runs 5.3 to 6.5 characters per second, so 60 seconds of narration holds roughly 320 to 390 Chinese characters. If you are writing to a target length, that is the conversion factor.
## Score it with whisper per segment, then listen to it anyway
The mechanical check is a transcription diff. Run each generated segment through whisper, compare against the script that produced it, and compute character error rate. Mine came out at 7.6%.
What that number catches is mispronounced words. What it does not catch is whether the result sounds good, which still needs your ears — the score can be clean on a take that is flat, or oddly paced, or subtly not you. I listened to mine. It passed.
Measure it per segment rather than over the whole concatenated file. That distinction is not a style preference; it changed my reading of this pipeline by a factor of 4.6, and the mechanism is in the deep dive below.
## All three variants are Apache-2.0 and non-gated
`Base`, `1.7B-CustomVoice` and `0.6B-CustomVoice` are all Apache-2.0 and non-gated, so commercial use is fine.
Check it yourself before you build on top of it. Several comparable open TTS models are not commercially usable.
## Deep dive: three variants, no seed, and a number that lied
Nothing below changes how you run the pipeline above, so skip it if you have what you came for. It is the measurement record: which variant does what, why the same sentence comes out differently every run, and how a full-file score lied to me by 4.6x.
### Three variants, three different jobs, three different calls
I found the split between variants documented inconsistently, and what I measured differs from what several web sources claimed. Here is what the three actually do:
| Variant | What it does | Call |
|---|---|---|
| `Base` | Cloning only. No preset voices. | `model.generate(text=, ref_audio=, ref_text=)` |
| `CustomVoice` | 9 preset voices, plus an `instruct` emotion parameter | `model.generate_custom_voice(text=, speaker=, language=, instruct=)` |
| `VoiceDesign` | Describe a voice in words, get that voice | `model.generate_voice_design(text=, language=, instruct=)` |
The nine presets in `CustomVoice`:
```
serena / vivian / uncle_fu / ryan / aiden / ono_anna / sohee / eric / dylan
```
The eleven languages:
```
auto / chinese / english / german / italian / portuguese / spanish / japanese / korean / french / russian
```
`Base` takes no `instruct` parameter because its delivery comes from your recording. Telling it to sound cheerful would be a second, competing source of prosody. If you want to direct the emotion, `CustomVoice` is the variant that accepts direction.
### There is no seed, so the same sentence comes out different every run
**What I saw.** I regenerated a line I had already generated, expecting a byte-identical file, and got a different reading. The characters were right both times. The intonation drifted, and individual English letters came out differently from run to run.
**What I assumed going in.** That there was a seed parameter somewhere and I had not found it yet, since a seed is table stakes for a sampling-based generative model.
**What I did.** Went looking for one in the generate signature and the model config.
**What happened.** There is no seed exposed. Sampling is stochastic and this model exposes no seed to pin it down.
**What the assumption missed.** I had been treating run-to-run variation as a defect to eliminate. It is a property of the interface. Once that is settled, the question stops being "how do I make this deterministic" and becomes "how do I make re-rolling cheap", which has a much better answer.
### A pronunciation dictionary would not have fixed anything
**What I saw.** Certain words came out mispronounced. Not every run, which I noted at the time and did not think hard enough about.
**What I assumed going in.** That the fix was a pronunciation dictionary: collect the words that came out wrong, pin each to the reading I wanted, apply it as a preprocessing pass.
**What I did.** Started sketching the dictionary, then went back to check how consistently each word failed, because a dictionary entry needs a stable wrong answer to correct.
**What happened.** The words did not fail consistently. The same word came out one way on one run and another way on the next.
**What the assumption missed.** A lookup table maps one input to one output. It has nothing to say about variance, and building it would have produced a component that could not do the job I built it for.
### Re-rolling per sentence is what actually works
Split the narration into sentences and generate one file per sentence. When a sentence sounds wrong, re-run only that sentence.
This is only practical because generation runs faster than realtime. A single sentence takes a second or two, so re-rolling is effectively free, and you can keep pulling until a line lands right. It also decouples editing from synthesis: changing one line in the script means regenerating one file, not the whole take. On an 83-second narration that is the difference between a 51-second wait and a two-second one every time you change a word.
### CER 0.35 on the whole file, 0.076 per segment
**What I saw.** My first character error rate reading on the 83-second concatenated file was 0.35. A third of the characters wrong is not a tuning problem.
**What I assumed going in.** That the approach was finished. I was ready to write off voice cloning as not accurate enough for narration and go back to presets.
**What I did.** Before dropping it, I looked at where in the transcript the errors were rather than how many there were.
**What happened.** They were all bunched at the end of the file. Whisper hallucinates at the tail of long audio, which is known behaviour. Transcribing per segment gave 0.076. A 4.6x difference, and it made usable audio look broken.
**What the assumption missed.** I had treated a bad number as a fact about the thing being measured. The broken component was the measurement procedure, and in the number those two are indistinguishable. That is the part worth carrying to the next measurement: an aggregate over a long file can hide a defect that lives in one region of it, and the aggregate is the form you are most likely to act on.
### BreezyVoice looked like a shortcut and runs 24x slower than realtime here
[BreezyVoice](https://github.com/mtkresearch/BreezyVoice), from MediaTek, is a Chinese TTS model that also handles Chinese-English code switching. On paper it looked like a shortcut past the whole cloning step, so I tried it first.
On the MacBook it runs 24x slower than realtime. A minute of narration takes 24 minutes, which rules it out for a workflow where I regenerate individual lines while writing.
That is not a verdict on the model. It needs a GPU, and the premise of this pipeline is that it runs on the laptop I am already writing on. If you have a GPU box, measure it yourself rather than taking my number.
## Wrapping up
A 24-second recording, two packages, ten lines of Python, and the narration comes out in your own voice, on your own laptop, under a licence that lets you sell what you make with it.
Three things not to skip: match the transcript to the recording word for word, keep `12Hz` in the model name, and score per segment rather than per file.
What I am actually building with the narration is the next article.
---
**Also in this series**: [The check in the skill was written correctly and never ran once](/en/blog/ai-tic-check-that-never-ran) · [AI slop isn't the em dash, it's the structure](/en/blog/ai-slop-is-structural)
---
# [Benchmark] Two characters in one shot: MiniMax-H3 Ref2VA takes multiple reference images
URL: https://ai-muninn.com/en/blog/minimax-h3-ref2va-two-characters
Date: 2026-09-06
Series: MiniMax-H3 on RTX 5090 (Part 6)
Ref2VA is the only MiniMax-H3 mode that takes more than one reference image; the other four take a first frame, a last frame, or both. Two character sheets, one six-section prompt, 243 frames at 1344x768: **437 s** on one RTX 5090, two distinct voices, no bleed between the two faces (n=1, and I made the designs as different as I could). ASR on the dialogue came back at **CER 6.8%**, and all three errors were homophones. The trap: a `` label carries no identity, so restate the full appearance in every shot or the model invents a person.
## Hand a costume department two photos and the first question back is which robe goes on which person
That question is the entire problem with putting two characters in one AI-generated shot. One reference image is unambiguous: there is one face, and it belongs to the only person on screen. Two reference images need a binding, and nothing about "here are two pictures" tells the model which is which.
[Part 3](/en/blog/minimax-h3-rtx5090-character-lock) of this series locked one character's face with reference portraits. This part does two people in one frame, talking to each other. The scene is the Chinese idiom 自相矛盾 (*zì xiāng máo dùn*, "self-contradiction" — literally, his own spear against his own shield): a market vendor claims his shield stops everything and his spear pierces everything, a young scholar asks what happens when the one meets the other, and the vendor has no answer.
What comes out the other end is a 10.125-second clip with three spoken lines, two distinct voices, and two characters who stay themselves, in 437 seconds on a single RTX 5090. Here is the order to do it in, and the four things that will stop you.
## Ref2VA is the only H3 mode where images mean "this is who", not "this is when"
H3 has five generation modes. Four of them take images, and the difference that matters is not how many but what the images are *for* — read the right-hand column.
| Mode | What the images mean |
|---|---|
| T2VA | none — text only |
| I2VA | one image = the **first frame** |
| FL2VA | two images = first frame + last frame |
| L2VA | one image = the **last frame**, model infers the opening |
| Ref2VA | N images = **`` is an identity, `` is still a frame** |
FL2VA also takes two images, which makes it look like a candidate until you notice that its two slots are already spoken for by time. Ref2VA is the only mode whose image list is open-ended. It also splits the job: an image tagged `` says *this is who* and the model picks the frames, while one tagged `` still works as a concrete target frame or shot-planning anchor. This run used `` only.
## The references are stills, not frames — two character sheets at 45 s each
I generated both character sheets with z-image, a still-image model, taking about 45 seconds each. Full-body, neutral pose, plain background. They are never shown in the video; they exist only to be pointed at.
The distance between those two designs is deliberate and I come back to it in the deep dive. If you are doing this for the first time, make your two characters as unlike each other as the scene allows. It costs nothing and it turns "did the identities hold?" from a judgement call into something you can see at a glance.
## The node is MiniMaxH3ReferenceToVideo, and it wants an audio_vae your ImageToVideo graph does not have
If you already have an H3 graph running, it is almost certainly built on `MiniMaxH3ImageToVideo`. Ref2VA is a different node:
```
MiniMaxH3ReferenceToVideo
required: clip · vae · audio_vae · prompt · width · height · length · ref_image_size
optional: ref_images · ref_videos · ref_video_audios · ref_audios
output: ['CONDITIONING', 'LATENT']
```
Two required inputs are new compared to `ImageToVideo`: `audio_vae` (`minimax_h3_audio_vae_fp32.safetensors`) and `ref_image_size`. The outputs are identical — `CONDITIONING` and `LATENT` — so everything downstream of the node, the whole sampler chain, transfers unchanged. Converting an existing graph is a node swap plus two wires, and forgetting `audio_vae` is the single most likely reason your converted graph will not run.
`ref_images` has type `COMFY_AUTOGROW_V3`, which sounds exotic and is not. In API-format JSON it is a plain array of links:
```json
"ref_images": [["20", 0], ["21", 0]]
```
Nodes 20 and 21 are `LoadImage` nodes. The images themselves have to be `POST /upload/image`'d to ComfyUI first, then loaded — you cannot inline them into the prompt payload.
## length has step 17: 243 frames is 10.125 s and 362 frames is the ceiling
The node schema declares `length` with `step: 17` and `min: 5`. So legal frame counts are 17k+5 — 5, 22, 39, ... 243, ... 362. That grid is enforced by the node, not by a convention downstream of it, which means a round number like 240 fails at the node rather than producing something slightly off.
The two values worth memorising: **243 frames = 10.125 s** and **362 frames = 15.08 s**, the latter being the ceiling for a single generation. Anything longer is a stitching problem, not a parameter.
## ref_image_size=match scales references to the render; max makes you pay on every step
The other new required input has two settings. `match` scales the reference images down to the pixel area of the generation. `max` uses a 2048 px short edge. The node's own tooltip explains the cost:
> Reference tokens ride through every sampling step, so 'max' can be several times slower.
That is the mechanism in one sentence: reference images are not read once at the start; they are conditioning that participates in every denoising step, so their token count multiplies by your step count. I ran `match`. There is a wrinkle in that "several times slower" claim which I get to in the untested list at the end.
## The prompt is six sections, and a label is defined exactly once
This is where Ref2VA diverges most from the three-part prompts you may be used to. The format has six named sections, in order: `subject_definitions` → `summary` → `retention_analysis` → `detailed_description` → `overall_soundscape` → `non_diegetic_music`.
The design point is the arrow on the right of that diagram. A character label is **defined once** in `subject_definitions` and **reused** across the other five sections. Change what a character looks like and you edit section one; every downstream reference follows. That is the payoff for a format that otherwise looks like bureaucracy.
`retention_analysis` is the section people skip and should not. It does not take free text. Visible references (``, ``, `